'잡동사니'에 해당되는 글 14725건
- 2026.07.29 핸드폰 망가짐 2
- 2026.07.29 blender 5.x sculpting
- 2026.07.29 blender export render/viewport
- 2026.07.29 rk-b30 한손 키보드 메뉴얼 획득! 4
- 2026.07.29 llama.cpp 동시에 응답하게 하기
- 2026.07.29 다이소 인켈 usb-c 이어폰
- 2026.07.29 blender 떼어내기, 때우기
- 2026.07.29 blender 보이지 않는 면까지 선택하기
- 2026.07.29 vllm concurrent test/benchmark
- 2026.07.28 vllm parallelism - concurrency
cube는 면이 없으니 안되는데 UV sphere 추가하니 된다.
f키로 size 조절
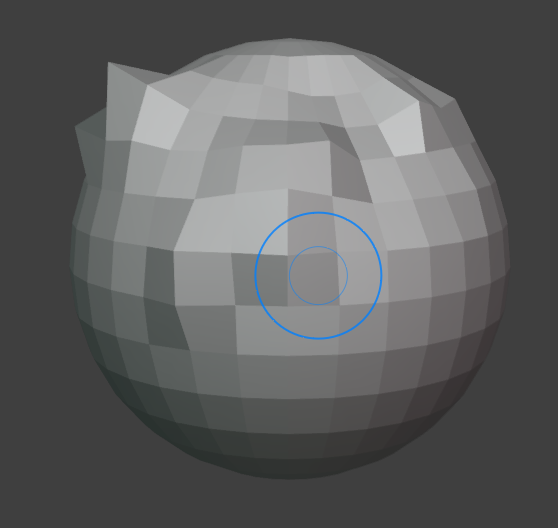
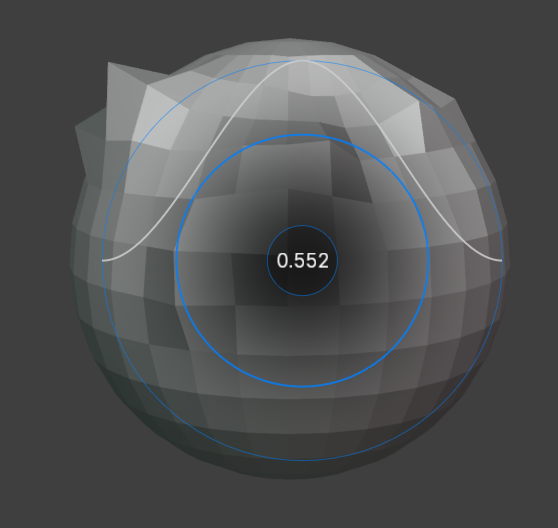
shift-f 로 세기를 조정할 수 있고
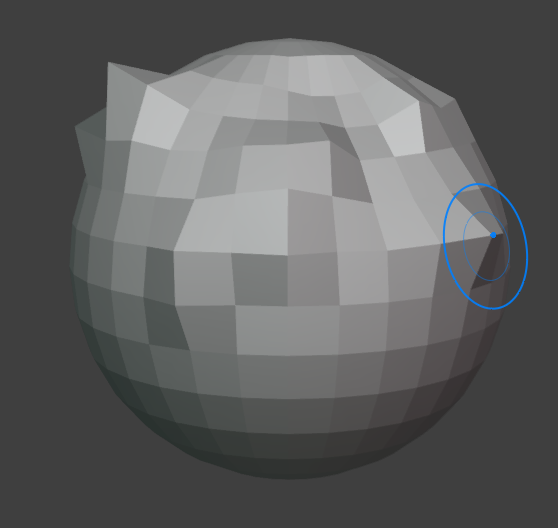
클릭 + 드래그는 뽑아내고
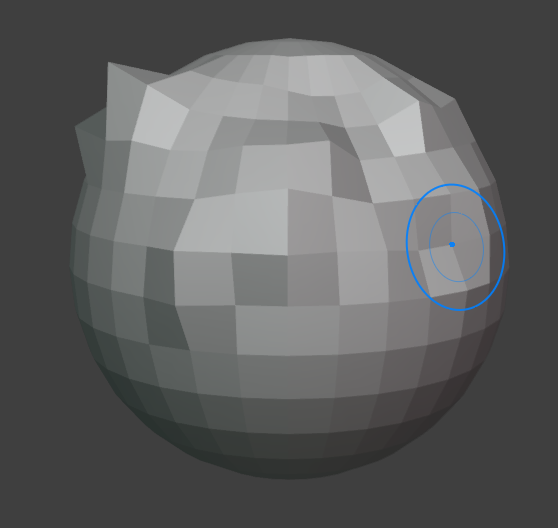
ctrl 클릭 +드래그는 밀어 넣는다.
[링크 : https://kauree.tistory.com/903]
유튜브 보다 보면 양쪽 대칭해서 하던데
상단에 나비 같은거 누르면 좌우 대칭이 된다는데 일단 이걸 잘 (?) 쓰려면 y축을 보게 하고 써야 하는 것 같다.
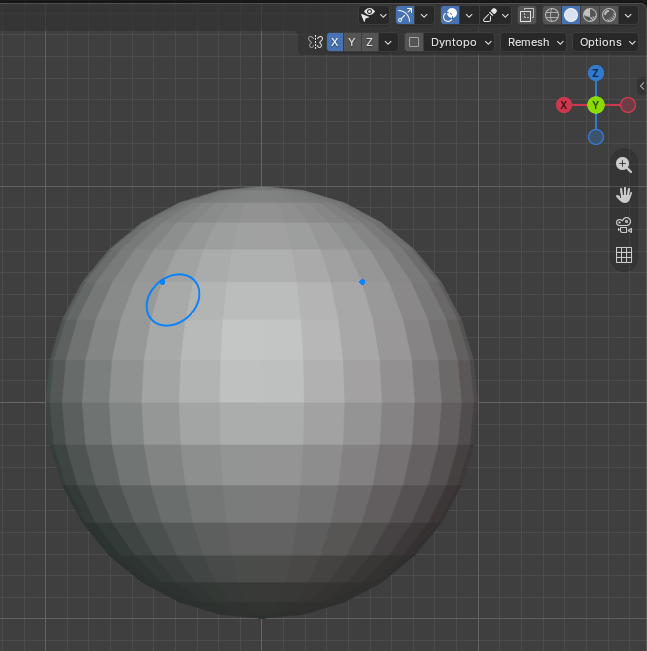
양쪽 뽑!

'프로그램 사용 > Blender' 카테고리의 다른 글
| blender 창 나누기. 카메라 뷰 보기 (0) | 2026.08.28 |
|---|---|
| blender sculpting - dynatopo, grab (0) | 2026.08.06 |
| blender export render/viewport (0) | 2026.07.29 |
| blender 떼어내기, 때우기 (0) | 2026.07.29 |
| blender 보이지 않는 면까지 선택하기 (0) | 2026.07.29 |
요런 모델인데 scene collection 에서 카메라 하나를 검은색으로 설정
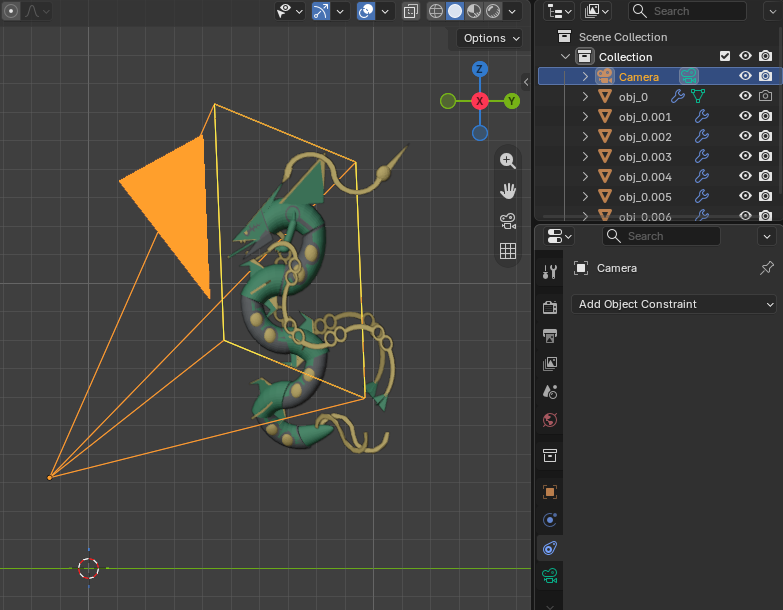
몸통은 사진기 선택을 꺼서 렌더되지 않게 하고 렌더하면 (각도 삑살은 어쩔수 없...) 이렇게 몸통이 빠진다.
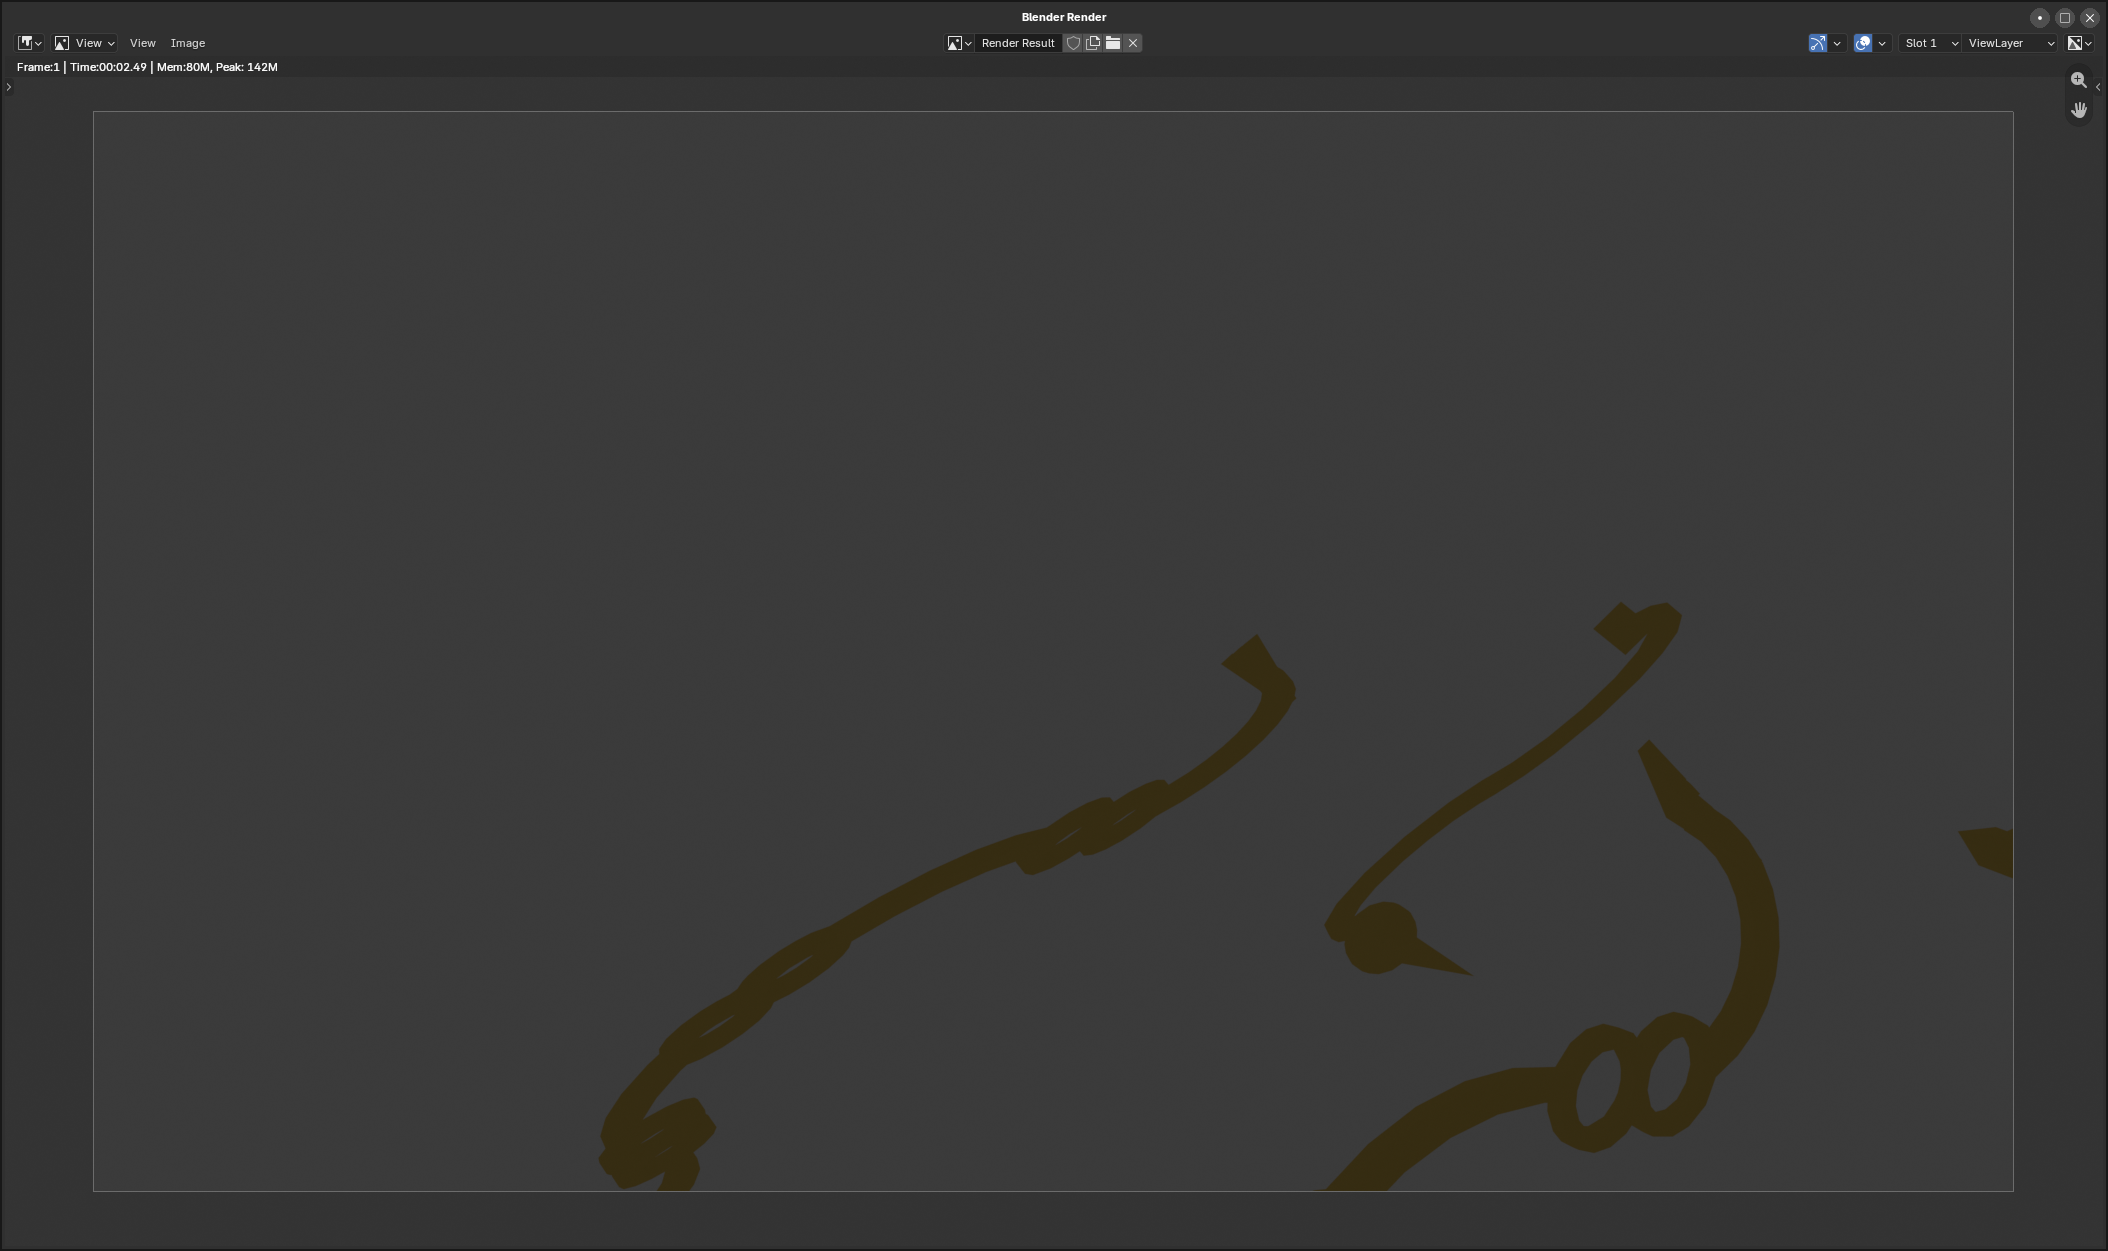
체크하고 렌더걸면 아래처럼 보인다.
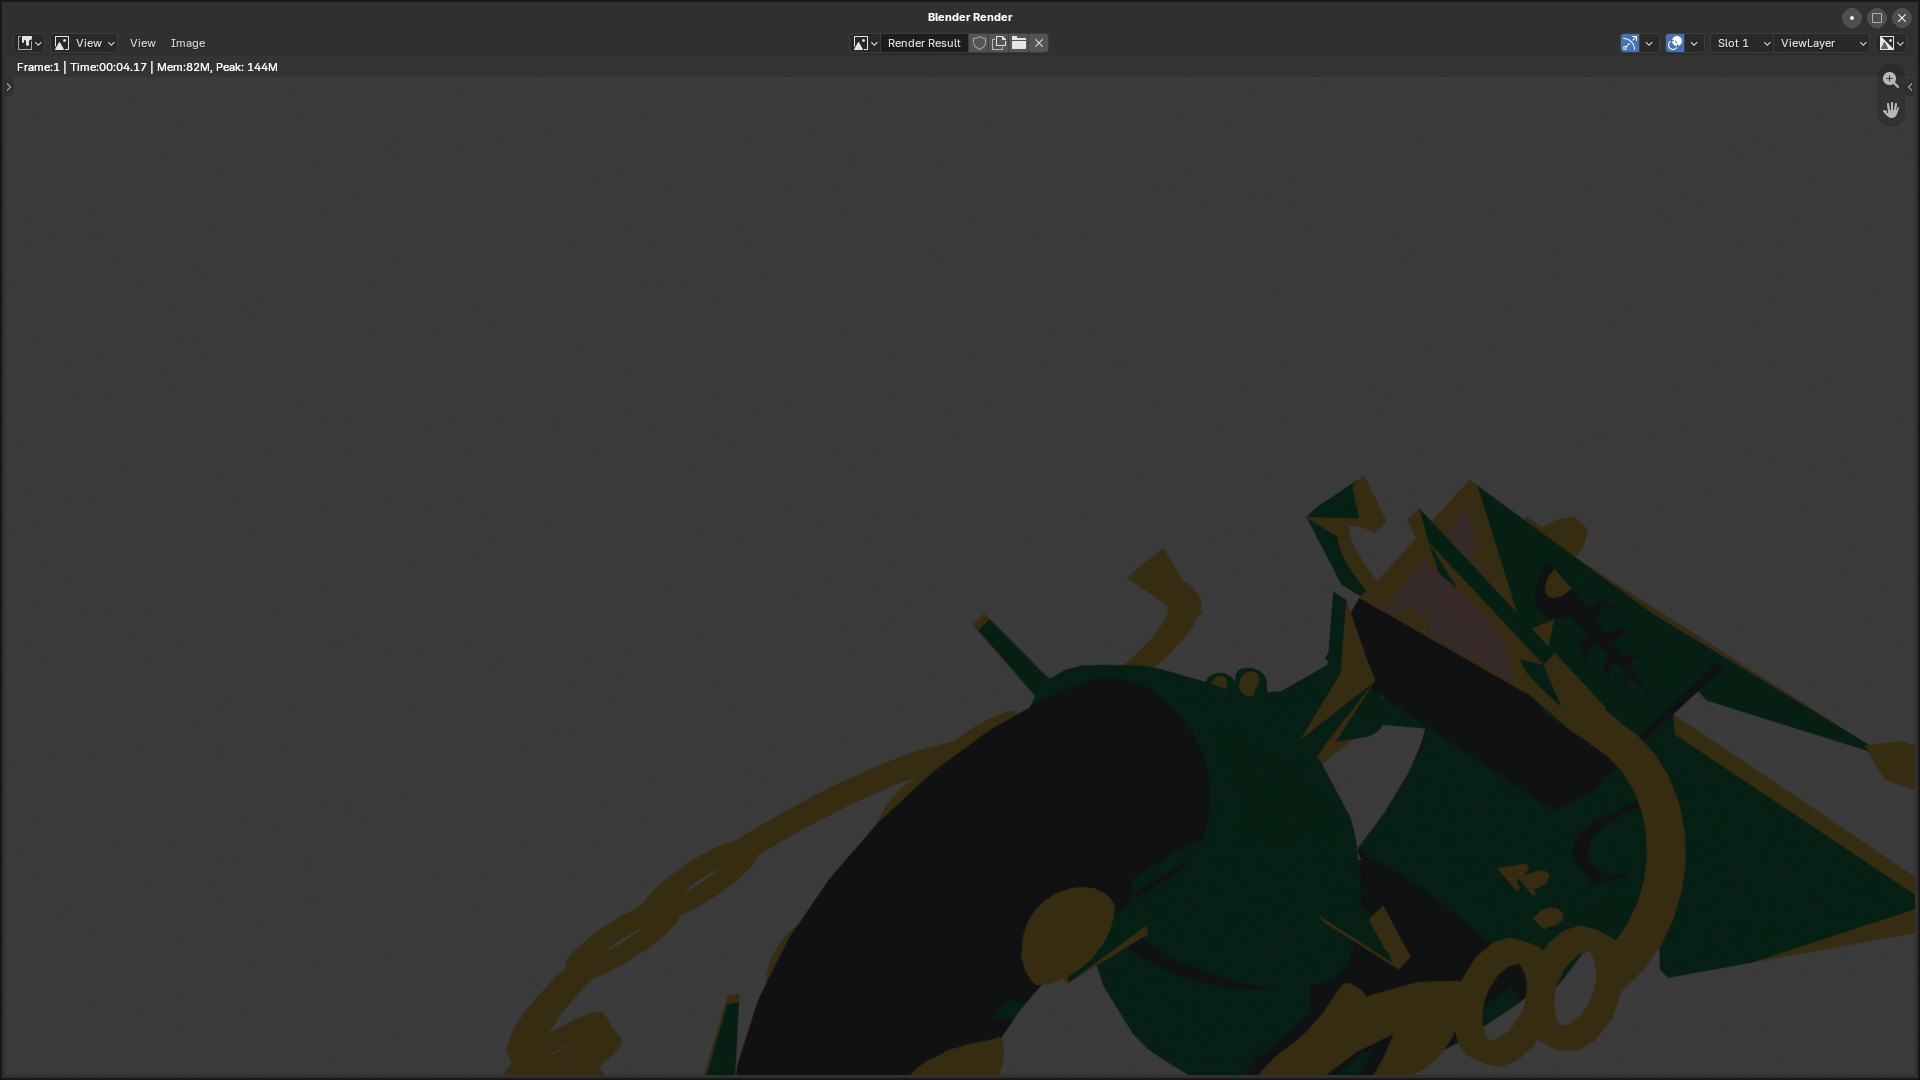
이걸 이용해서
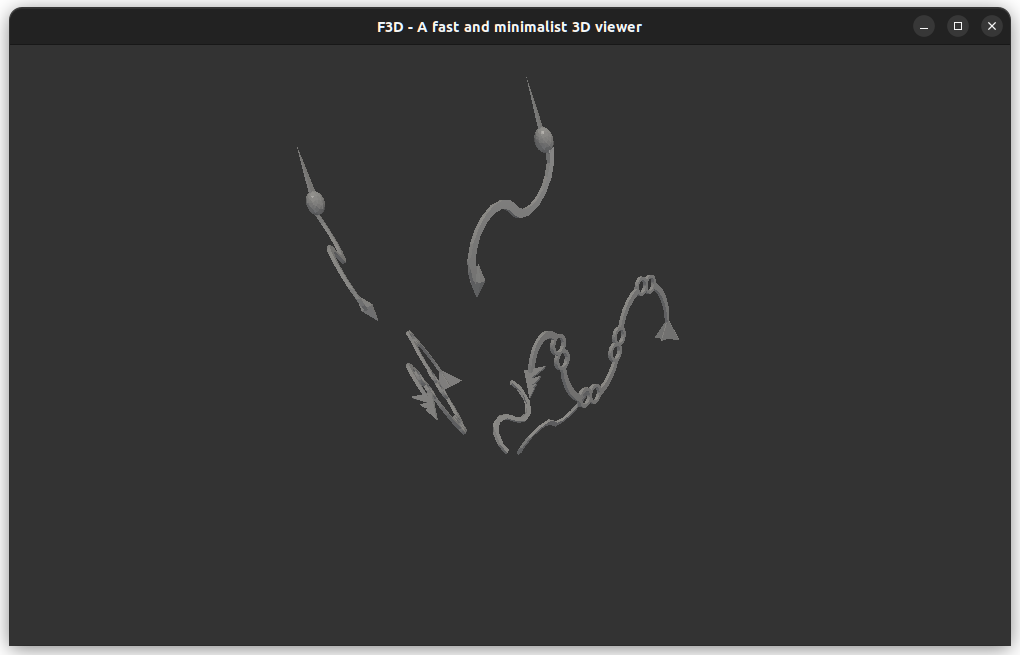
STL export 시 geometry - properties 에서 render로 하고 열어보면
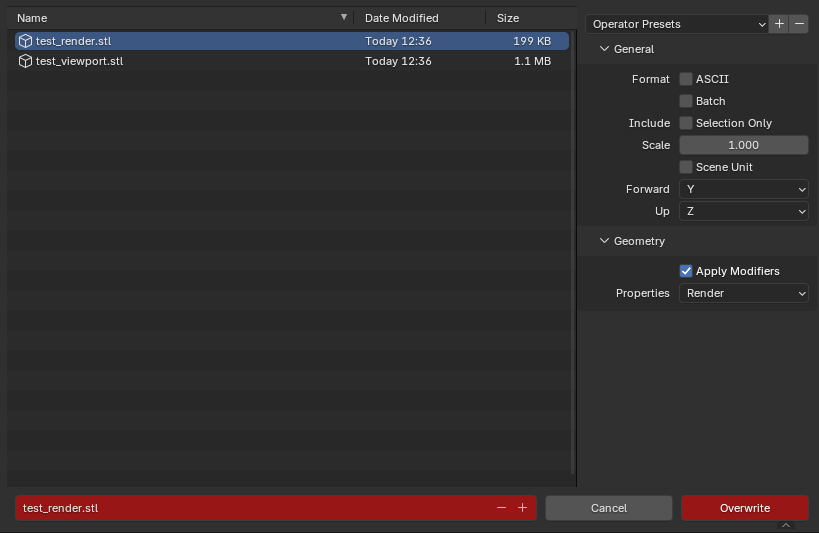
몸통은 렌더에서 빠져 있으니 털만 나오고
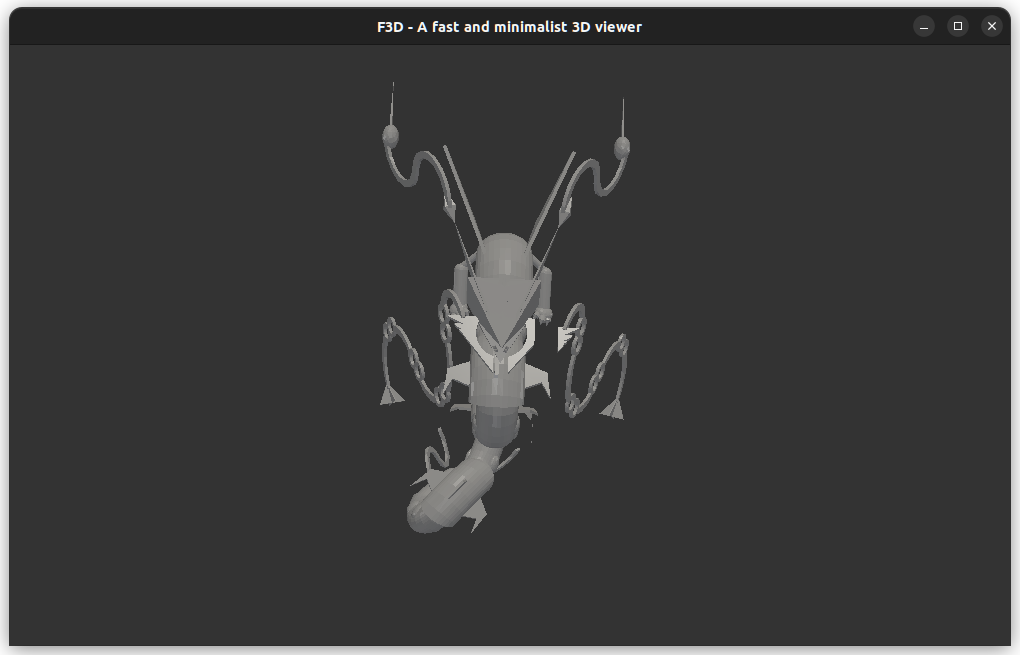
geometry - properties 에서 viewport로 하고 열어보면
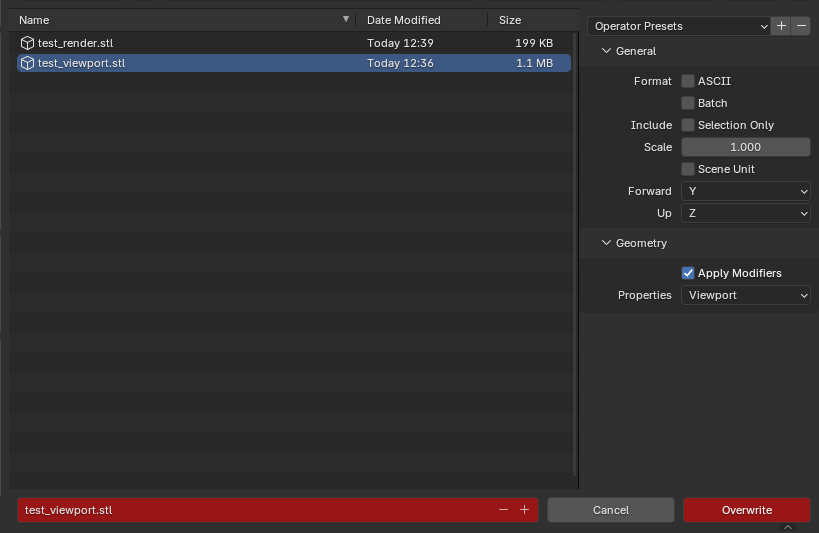
몸통을 포함해서 export 된다.
'프로그램 사용 > Blender' 카테고리의 다른 글
| blender sculpting - dynatopo, grab (0) | 2026.08.06 |
|---|---|
| blender 5.x sculpting (0) | 2026.07.29 |
| blender 떼어내기, 때우기 (0) | 2026.07.29 |
| blender 보이지 않는 면까지 선택하기 (0) | 2026.07.29 |
| blnder 포즈 바꾸면서 렌더하기 (0) | 2026.07.28 |
고객센터님 압도적 감사!
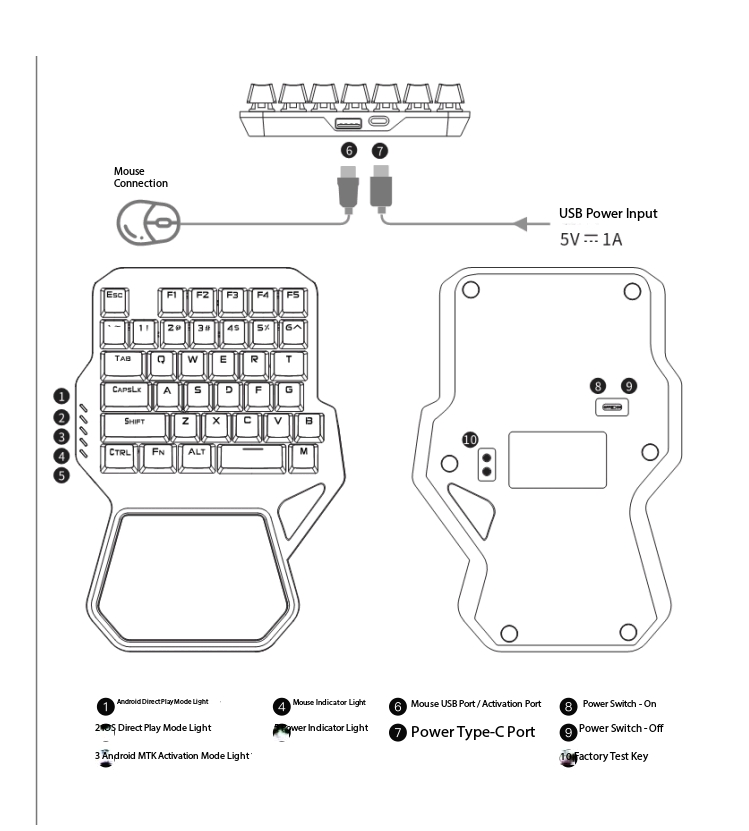
근데 안드로이드 MTK가 머지? 내가 아는 MTK는 미디어 텍인데 -ㅁ-?
USB Type C 는 순수하게 전원만 공급한다.
8/9는 전원 on/off인데 왜 안꺼지지 -ㅁ-???
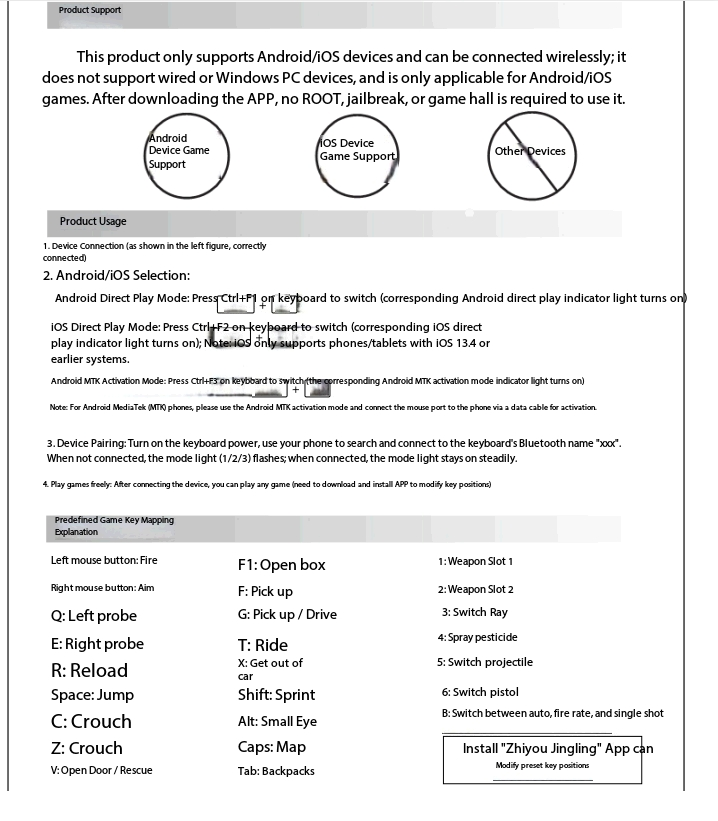
ctrl - f1 누르면 안드로이드 direct play mode
ctrl - f2 는 ios 모드
ctrl - f3 는 android MT activation mode 라는데 머지?(for android mediatek(MTK) phone.. 어.. 그 MTK 맞구만)
그나저나 박스 열고 달리고 문열고 올라타고.. 배그용인가?
+
2026.07.29
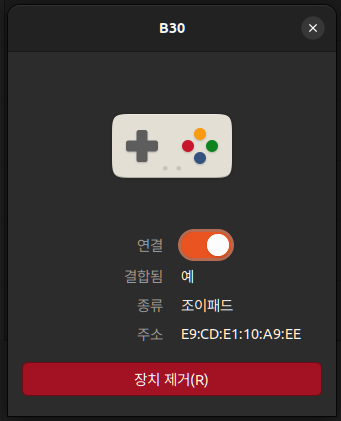
리눅스에서 해보니 왜 조이패드로 뜨는겨 ㅋㅋㅋ
아무튼 a d 눌러보면 특정 위치에서 드래그 되는거 같다.
걍 키만 쓰고 mcu랑 분해해서 버려야하나 ㅋㅋ
'개소리 왈왈 > 컴퓨터' 카테고리의 다른 글
| 오늘자 줍줍 (0) | 2026.08.18 |
|---|---|
| 질러? (2) | 2026.08.07 |
| 다이소 인켈 usb-c 이어폰 (0) | 2026.07.29 |
| 음.. 쓰레기를 샀나? rk-b30 한손 키보드 (2) | 2026.07.26 |
| usb-c 가 있다고 dp alt가 되는건 아니다 (0) | 2026.07.14 |
구글 ai 답변을 따라가니 이런게 있는데
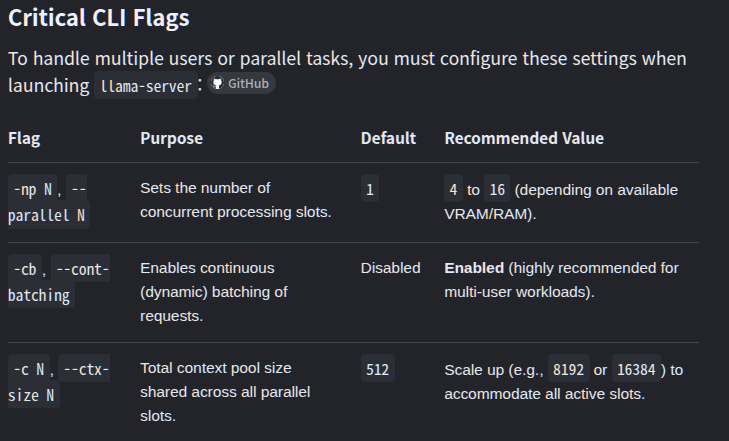
[링크 : https://github.com/ggml-org/llama.cpp/issues/4666]
기본적로 동시에 사용이 가능하도록 되어있나 보다. 오호..
대신 -np 1 을 주면 두개 켜고 양쪽에서 동시에 물어보면 하나만 대답해주다가, 다른쪽이 끝나야 시작한다.
| $ ./llama-b10145/llama-server --help ----- common params ----- -h, --help, --usage print usage and exit --version show version and build info -cl, --cache-list show list of models in cache --completion-bash print source-able bash completion script for llama.cpp -t, --threads N number of CPU threads to use during generation (default: -1) (env: LLAMA_ARG_THREADS) -tb, --threads-batch N number of threads to use during batch and prompt processing (default: same as --threads) -C, --cpu-mask M CPU affinity mask: arbitrarily long hex. Complements cpu-range (default: "") -Cr, --cpu-range lo-hi range of CPUs for affinity. Complements --cpu-mask --cpu-strict <0|1> use strict CPU placement (default: 0) --prio N set process/thread priority : low(-1), normal(0), medium(1), high(2), realtime(3) (default: 0) --poll <0...100> use polling level to wait for work (0 - no polling, default: 50) -Cb, --cpu-mask-batch M CPU affinity mask: arbitrarily long hex. Complements cpu-range-batch (default: same as --cpu-mask) -Crb, --cpu-range-batch lo-hi ranges of CPUs for affinity. Complements --cpu-mask-batch --cpu-strict-batch <0|1> use strict CPU placement (default: same as --cpu-strict) --prio-batch N set process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --poll-batch <0|1> use polling to wait for work (default: same as --poll) -c, --ctx-size N size of the prompt context (default: 0, 0 = loaded from model) (env: LLAMA_ARG_CTX_SIZE) -n, --predict, --n-predict N number of tokens to predict (default: -1, -1 = infinity) (env: LLAMA_ARG_N_PREDICT) -b, --batch-size N logical maximum batch size (default: 2048) (env: LLAMA_ARG_BATCH) -ub, --ubatch-size N physical maximum batch size (default: 512) (env: LLAMA_ARG_UBATCH) --keep N number of tokens to keep from the initial prompt (default: 0, -1 = all) --swa-full use full-size SWA cache (default: false) [(more info)](https://github.com/ggml-org/llama.cpp/pull/13194#issuecomment-2868343055) (env: LLAMA_ARG_SWA_FULL) -fa, --flash-attn [on|off|auto] set Flash Attention use ('on', 'off', or 'auto', default: 'auto') (env: LLAMA_ARG_FLASH_ATTN) --perf, --no-perf whether to enable internal libllama performance timings (default: false) (env: LLAMA_ARG_PERF) -e, --escape, --no-escape whether to process escapes sequences (\n, \r, \t, \', \", \\) (default: true) --rope-scaling {none,linear,yarn} RoPE frequency scaling method, defaults to linear unless specified by the model (env: LLAMA_ARG_ROPE_SCALING_TYPE) --rope-scale N RoPE context scaling factor, expands context by a factor of N (env: LLAMA_ARG_ROPE_SCALE) --rope-freq-base N RoPE base frequency, used by NTK-aware scaling (default: loaded from model) (env: LLAMA_ARG_ROPE_FREQ_BASE) --rope-freq-scale N RoPE frequency scaling factor, expands context by a factor of 1/N (env: LLAMA_ARG_ROPE_FREQ_SCALE) --yarn-orig-ctx N YaRN: original context size of model (default: 0 = model training context size) (env: LLAMA_ARG_YARN_ORIG_CTX) --yarn-ext-factor N YaRN: extrapolation mix factor (default: -1.00, 0.0 = full interpolation) (env: LLAMA_ARG_YARN_EXT_FACTOR) --yarn-attn-factor N YaRN: scale sqrt(t) or attention magnitude (default: -1.00) (env: LLAMA_ARG_YARN_ATTN_FACTOR) --yarn-beta-slow N YaRN: high correction dim or alpha (default: -1.00) (env: LLAMA_ARG_YARN_BETA_SLOW) --yarn-beta-fast N YaRN: low correction dim or beta (default: -1.00) (env: LLAMA_ARG_YARN_BETA_FAST) -kvo, --kv-offload, -nkvo, --no-kv-offload whether to enable KV cache offloading (default: enabled) (env: LLAMA_ARG_KV_OFFLOAD) --repack, -nr, --no-repack whether to enable weight repacking (default: enabled) (env: LLAMA_ARG_REPACK) --no-host bypass host buffer allowing extra buffers to be used (env: LLAMA_ARG_NO_HOST) -ctk, --cache-type-k TYPE KV cache data type for K allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_K) -ctv, --cache-type-v TYPE KV cache data type for V allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_V) -dt, --defrag-thold N KV cache defragmentation threshold (DEPRECATED) (env: LLAMA_ARG_DEFRAG_THOLD) --rpc SERVERS comma-separated list of RPC servers (host:port) (env: LLAMA_ARG_RPC) --mlock DEPRECATED in favor of `--load-mode`: force system to keep model in RAM rather than swapping or compressing (env: LLAMA_ARG_MLOCK) --mmap, --no-mmap DEPRECATED in favor of `--load-mode`: whether to memory-map model. (if mmap disabled, slower load but may reduce pageouts if not using mlock) (env: LLAMA_ARG_MMAP) -dio, --direct-io, -ndio, --no-direct-io DEPRECATED in favor of `--load-mode`: use DirectIO if available (env: LLAMA_ARG_DIO) -lm, --load-mode MODE model loading mode (default: mmap) - none: no special loading mode - mmap: memory-map model (if mmap disabled, slower load but may reduce pageouts if not using mlock) - mlock: force system to keep model in RAM rather than swapping or compressing - mmap+mlock: mmap + force system to keep model in RAM rather than swapping or compressing - dio: use DirectIO if available (env: LLAMA_ARG_LOAD_MODE) --numa TYPE attempt optimizations that help on some NUMA systems - distribute: spread execution evenly over all nodes - isolate: only spawn threads on CPUs on the node that execution started on - numactl: use the CPU map provided by numactl if run without this previously, it is recommended to drop the system page cache before using this see https://github.com/ggml-org/llama.cpp/issues/1437 (env: LLAMA_ARG_NUMA) -dev, --device <dev1,dev2,..> comma-separated list of devices to use for offloading (none = don't offload) use --list-devices to see a list of available devices (env: LLAMA_ARG_DEVICE) --list-devices print list of available devices and exit -ot, --override-tensor <tensor name pattern>=<buffer type>,... override tensor buffer type (env: LLAMA_ARG_OVERRIDE_TENSOR) -cmoe, --cpu-moe keep all Mixture of Experts (MoE) weights in the CPU (env: LLAMA_ARG_CPU_MOE) -ncmoe, --n-cpu-moe N keep the Mixture of Experts (MoE) weights of the first N layers in the CPU (env: LLAMA_ARG_N_CPU_MOE) -ngl, --gpu-layers, --n-gpu-layers N max. number of layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS) -sm, --split-mode {none,layer,row,tensor} how to split the model across multiple GPUs, one of: - none: use one GPU only - layer (default): split layers and KV across GPUs (pipelined) - row: split weight across GPUs by rows (parallelized) - tensor: split weights and KV across GPUs (parallelized, EXPERIMENTAL) (env: LLAMA_ARG_SPLIT_MODE) -ts, --tensor-split N0,N1,N2,... fraction of the model to offload to each GPU, comma-separated list of proportions, e.g. 3,1 (env: LLAMA_ARG_TENSOR_SPLIT) -mg, --main-gpu INDEX the GPU to use for the model (with split-mode = none), or for intermediate results and KV (with split-mode = row) (default: 0) (env: LLAMA_ARG_MAIN_GPU) -fit, --fit [on|off] whether to adjust unset arguments to fit in device memory ('on' or 'off', default: 'on') (env: LLAMA_ARG_FIT) -fitt, --fit-target MiB0,MiB1,MiB2,... target margin per device for --fit, comma-separated list of values, single value is broadcast across all devices, default: 1024 (env: LLAMA_ARG_FIT_TARGET) -fitc, --fit-ctx N minimum ctx size that can be set by --fit option, default: 4096 (env: LLAMA_ARG_FIT_CTX) --check-tensors check model tensor data for invalid values (default: false) --override-kv KEY=TYPE:VALUE,... advanced option to override model metadata by key. to specify multiple overrides, either use comma-separated values. types: int, float, bool, str. example: --override-kv tokenizer.ggml.add_bos_token=bool:false,tokenizer.ggml.add_eos_token=bool:false --op-offload, --no-op-offload whether to offload host tensor operations to device (default: true) --lora FNAME path to LoRA adapter (use comma-separated values to load multiple adapters) --lora-scaled FNAME:SCALE,... path to LoRA adapter with user defined scaling (format: FNAME:SCALE,...) note: use comma-separated values --control-vector FNAME add a control vector note: use comma-separated values to add multiple control vectors --control-vector-scaled FNAME:SCALE,... add a control vector with user defined scaling SCALE note: use comma-separated values (format: FNAME:SCALE,...) --control-vector-layer-range START END layer range to apply the control vector(s) to, start and end inclusive -m, --model FNAME model path to load (env: LLAMA_ARG_MODEL) -mu, --model-url MODEL_URL model download url (default: unused) (env: LLAMA_ARG_MODEL_URL) -dr, --docker-repo [<repo>/]<model>[:quant] Docker Hub model repository. repo is optional, default to ai/. quant is optional, default to :latest. example: gemma3 (default: unused) (env: LLAMA_ARG_DOCKER_REPO) -hf, -hfr, --hf-repo <user>/<model>[:quant] Hugging Face model repository; quant is optional, case-insensitive, default to Q4_K_M, or falls back to the first file in the repo if Q4_K_M doesn't exist. mmproj is also downloaded automatically if available. to disable, add --no-mmproj example: ggml-org/GLM-4.7-Flash-GGUF:Q4_K_M (default: unused) (env: LLAMA_ARG_HF_REPO) -hff, --hf-file FILE Hugging Face model file. If specified, it will override the quant in --hf-repo (default: unused) (env: LLAMA_ARG_HF_FILE) -hfv, -hfrv, --hf-repo-v <user>/<model>[:quant] Hugging Face model repository for the vocoder model (default: unused) (env: LLAMA_ARG_HF_REPO_V) -hffv, --hf-file-v FILE Hugging Face model file for the vocoder model (default: unused) (env: LLAMA_ARG_HF_FILE_V) -hft, --hf-token TOKEN Hugging Face access token (default: value from HF_TOKEN environment variable) (env: HF_TOKEN) --log-disable Log disable --log-file FNAME Log to file (env: LLAMA_ARG_LOG_FILE) --log-colors [on|off|auto] Set colored logging ('on', 'off', or 'auto', default: 'auto') 'auto' enables colors when output is to a terminal (env: LLAMA_ARG_LOG_COLORS) -v, --verbose, --log-verbose Set verbosity level to infinity (i.e. log all messages, useful for debugging) --offline Offline mode: forces use of cache, prevents network access (env: LLAMA_ARG_OFFLINE) -lv, --verbosity, --log-verbosity N Set the verbosity threshold. Messages with a higher verbosity will be ignored. Values: - 0: generic output - 1: error - 2: warning - 3: info - 4: trace (more info) - 5: debug (default: 3) (env: LLAMA_ARG_LOG_VERBOSITY) --log-prefix, --no-log-prefix Enable prefix in log messages (env: LLAMA_ARG_LOG_PREFIX) --log-timestamps, --no-log-timestamps Enable timestamps in log messages (env: LLAMA_ARG_LOG_TIMESTAMPS) --spec-draft-type-k, -ctkd, --cache-type-k-draft TYPE KV cache data type for K for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_K) --spec-draft-type-v, -ctvd, --cache-type-v-draft TYPE KV cache data type for V for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_V) ----- sampling params ----- --samplers SAMPLERS samplers that will be used for generation in the order, separated by ';' (default: penalties;dry;top_n_sigma;top_k;typ_p;top_p;min_p;xtc;temperature) -s, --seed SEED RNG seed (default: -1, use random seed for -1) --sampler-seq, --sampling-seq SEQUENCE simplified sequence for samplers that will be used (default: edskypmxt) --ignore-eos ignore end of stream token and continue generating (implies --logit-bias EOS-inf) --temp, --temperature N temperature (default: 0.80) --top-k N top-k sampling (default: 40, 0 = disabled) (env: LLAMA_ARG_TOP_K) --top-p N top-p sampling (default: 0.95, 1.0 = disabled) --min-p N min-p sampling (default: 0.05, 0.0 = disabled) --top-nsigma, --top-n-sigma N top-n-sigma sampling (default: -1.00, -1.0 = disabled) --xtc-probability N xtc probability (default: 0.00, 0.0 = disabled) --xtc-threshold N xtc threshold (default: 0.10, 1.0 = disabled) --typical, --typical-p N locally typical sampling, parameter p (default: 1.00, 1.0 = disabled) --repeat-last-n N last n tokens to consider for penalize (default: 64, 0 = disabled, -1 = ctx_size) --repeat-penalty N penalize repeat sequence of tokens (default: 1.00, 1.0 = disabled) --presence-penalty N repeat alpha presence penalty (default: 0.00, 0.0 = disabled) --frequency-penalty N repeat alpha frequency penalty (default: 0.00, 0.0 = disabled) --dry-multiplier N set DRY sampling multiplier (default: 0.00, 0.0 = disabled) --dry-base N set DRY sampling base value (default: 1.75) --dry-allowed-length N set allowed length for DRY sampling (default: 2) --dry-penalty-last-n N set DRY penalty for the last n tokens (default: -1, 0 = disable, -1 = context size) --dry-sequence-breaker STRING add sequence breaker for DRY sampling, clearing out default breakers ('\n', ':', '"', '*') in the process; use "none" to not use any sequence breakers --adaptive-target N adaptive-p: select tokens near this probability (valid range 0.0 to 1.0; negative = disabled) (default: -1.00) [(more info)](https://github.com/ggml-org/llama.cpp/pull/17927) --adaptive-decay N adaptive-p: decay rate for target adaptation over time. lower values are more reactive, higher values are more stable. (valid range 0.0 to 0.99) (default: 0.90) --dynatemp-range N dynamic temperature range (default: 0.00, 0.0 = disabled) --dynatemp-exp N dynamic temperature exponent (default: 1.00) --mirostat N use Mirostat sampling. Top K, Nucleus and Locally Typical samplers are ignored if used. (default: 0, 0 = disabled, 1 = Mirostat, 2 = Mirostat 2.0) --mirostat-lr N Mirostat learning rate, parameter eta (default: 0.10) --mirostat-ent N Mirostat target entropy, parameter tau (default: 5.00) -l, --logit-bias TOKEN_ID(+/-)BIAS modifies the likelihood of token appearing in the completion, i.e. `--logit-bias 15043+1` to increase likelihood of token ' Hello', or `--logit-bias 15043-1` to decrease likelihood of token ' Hello' --grammar GRAMMAR BNF-like grammar to constrain generations (see samples in grammars/ dir) --grammar-file FNAME file to read grammar from -j, --json-schema SCHEMA JSON schema to constrain generations (https://json-schema.org/), e.g. `{}` for any JSON object For schemas w/ external $refs, use --grammar + example/json_schema_to_grammar.py instead -jf, --json-schema-file FILE File containing a JSON schema to constrain generations (https://json-schema.org/), e.g. `{}` for any JSON object For schemas w/ external $refs, use --grammar + example/json_schema_to_grammar.py instead -bs, --backend-sampling enable backend sampling (experimental) (default: disabled) (env: LLAMA_ARG_BACKEND_SAMPLING) ----- speculative params ----- --spec-draft-hf, -hfd, -hfrd, --hf-repo-draft <user>/<model>[:quant] Same as --hf-repo, but for the draft model (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_HF_REPO) --spec-draft-threads, -td, --threads-draft N number of threads to use during generation (default: same as --threads) --spec-draft-threads-batch, -tbd, --threads-batch-draft N number of threads to use during batch and prompt processing (default: same as --threads-draft) --spec-draft-cpu-mask, -Cd, --cpu-mask-draft M Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) --spec-draft-cpu-range, -Crd, --cpu-range-draft lo-hi Ranges of CPUs for affinity. Complements --cpu-mask-draft --spec-draft-cpu-strict, --cpu-strict-draft <0|1> Use strict CPU placement for draft model (default: same as --cpu-strict) --spec-draft-prio, --prio-draft N set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --spec-draft-poll, --poll-draft <0|1> Use polling to wait for draft model work (default: same as --poll) --spec-draft-cpu-mask-batch, -Cbd, --cpu-mask-batch-draft M Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) --spec-draft-cpu-strict-batch, --cpu-strict-batch-draft <0|1> Use strict CPU placement for draft model (default: --cpu-strict-draft) --spec-draft-prio-batch, --prio-batch-draft N set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --spec-draft-poll-batch, --poll-batch-draft <0|1> Use polling to wait for draft model work (default: --poll-draft) --spec-draft-override-tensor, -otd, --override-tensor-draft <tensor name pattern>=<buffer type>,... override tensor buffer type for draft model --spec-draft-cpu-moe, -cmoed, --cpu-moe-draft keep all Mixture of Experts (MoE) weights in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_CPU_MOE) --spec-draft-n-cpu-moe, --spec-draft-ncmoe, -ncmoed, --n-cpu-moe-draft N keep the Mixture of Experts (MoE) weights of the first N layers in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_N_CPU_MOE) --spec-draft-n-max N number of tokens to draft for speculative decoding (default: 3) (env: LLAMA_ARG_SPEC_DRAFT_N_MAX) --spec-draft-n-min N minimum number of draft tokens to use for speculative decoding (default: 0) (env: LLAMA_ARG_SPEC_DRAFT_N_MIN) --spec-draft-p-split, --draft-p-split P speculative decoding split probability (default: 0.10) (env: LLAMA_ARG_SPEC_DRAFT_P_SPLIT) --spec-draft-p-min, --draft-p-min P minimum speculative decoding probability (greedy) (default: 0.00) (env: LLAMA_ARG_SPEC_DRAFT_P_MIN) --spec-draft-backend-sampling, --no-spec-draft-backend-sampling offload draft sampling to the backend (default: enabled) (env: LLAMA_ARG_SPEC_DRAFT_BACKEND_SAMPLING) --spec-draft-device, -devd, --device-draft <dev1,dev2,..> comma-separated list of devices to use for offloading the draft model (none = don't offload) use --list-devices to see a list of available devices --spec-draft-ngl, -ngld, --gpu-layers-draft, --n-gpu-layers-draft N max. number of draft model layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS_DRAFT) --spec-draft-model, -md, --model-draft FNAME draft model for speculative decoding (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_MODEL) --spec-type none,draft-simple,draft-eagle3,draft-mtp,draft-dflash,ngram-simple,ngram-map-k,ngram-map-k4v,ngram-mod,ngram-cache comma-separated list of types of speculative decoding to use (default: none) (env: LLAMA_ARG_SPEC_TYPE) --spec-ngram-mod-n-min N minimum number of ngram tokens to use for ngram-based speculative decoding (default: 48) --spec-ngram-mod-n-max N maximum number of ngram tokens to use for ngram-based speculative decoding (default: 64) --spec-ngram-mod-n-match N ngram-mod lookup length (default: 24) --spec-ngram-simple-size-n N ngram size N for ngram-simple speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-simple-size-m N ngram size M for ngram-simple speculative decoding, length of draft m-gram (default: 48) --spec-ngram-simple-min-hits N minimum hits for ngram-simple speculative decoding (default: 1) --spec-ngram-map-k-size-n N ngram size N for ngram-map-k speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-map-k-size-m N ngram size M for ngram-map-k speculative decoding, length of draft m-gram (default: 48) --spec-ngram-map-k-min-hits N minimum hits for ngram-map-k speculative decoding (default: 1) --spec-ngram-map-k4v-size-n N ngram size N for ngram-map-k4v speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-map-k4v-size-m N ngram size M for ngram-map-k4v speculative decoding, length of draft m-gram (default: 48) --spec-ngram-map-k4v-min-hits N minimum hits for ngram-map-k4v speculative decoding (default: 1) --draft, --draft-n, --draft-max N the argument has been removed. use --spec-draft-n-max or --spec-ngram-mod-n-max (env: LLAMA_ARG_DRAFT_MAX) --draft-min, --draft-n-min N the argument has been removed. use --spec-draft-n-min or --spec-ngram-mod-n-min (env: LLAMA_ARG_DRAFT_MIN) --spec-ngram-size-n N the argument has been removed. use the respective --spec-ngram-*-size-n or --spec-ngram-mod-n-match --spec-ngram-size-m N the argument has been removed. use the respective --spec-ngram-*-size-m --spec-ngram-min-hits N the argument has been removed. use the respective --spec-ngram-*-min-hits ----- example-specific params ----- -lcs, --lookup-cache-static FNAME path to static lookup cache to use for lookup decoding (not updated by generation) -lcd, --lookup-cache-dynamic FNAME path to dynamic lookup cache to use for lookup decoding (updated by generation) -ctxcp, --ctx-checkpoints, --swa-checkpoints N max number of context checkpoints to create per slot (default: 32)[(more info)](https://github.com/ggml-org/llama.cpp/pull/15293) (env: LLAMA_ARG_CTX_CHECKPOINTS) -cms, --checkpoint-min-step N minimum spacing between context checkpoints in tokens (default: 8192, 0 = no minimum) (env: LLAMA_ARG_CHECKPOINT_MIN_SPACING_NT) -cram, --cache-ram N set the maximum cache size in MiB (default: 8192, -1 - no limit, 0 - disable)[(more info)](https://github.com/ggml-org/llama.cpp/pull/16391) (env: LLAMA_ARG_CACHE_RAM) -kvu, --kv-unified, -no-kvu, --no-kv-unified use single unified KV buffer shared across all sequences (default: enabled if number of slots is auto) (env: LLAMA_ARG_KV_UNIFIED) --cache-idle-slots, --no-cache-idle-slots save idle slots to the prompt cache on new task, and clear them when using unified KV (default: enabled, requires cache-ram) (env: LLAMA_ARG_CACHE_IDLE_SLOTS) --context-shift, --no-context-shift whether to use context shift on infinite text generation (default: disabled) (env: LLAMA_ARG_CONTEXT_SHIFT) -r, --reverse-prompt PROMPT halt generation at PROMPT, return control in interactive mode -sp, --special special tokens output enabled (default: false) --warmup, --no-warmup whether to perform warmup with an empty run (default: enabled) --spm-infill use Suffix/Prefix/Middle pattern for infill (instead of Prefix/Suffix/Middle) as some models prefer this. (default: disabled) --pooling {none,mean,cls,last,rank} pooling type for embeddings, use model default if unspecified (env: LLAMA_ARG_POOLING) -np, --parallel N number of server slots (default: -1, -1 = auto) (env: LLAMA_ARG_N_PARALLEL) -cb, --cont-batching, -nocb, --no-cont-batching whether to enable continuous batching (a.k.a dynamic batching) (default: enabled) (env: LLAMA_ARG_CONT_BATCHING) -mm, --mmproj FILE path to a multimodal projector file. see tools/mtmd/README.md note: if -hf is used, this argument can be omitted (env: LLAMA_ARG_MMPROJ) -mmu, --mmproj-url URL URL to a multimodal projector file. see tools/mtmd/README.md (env: LLAMA_ARG_MMPROJ_URL) --mmproj-auto, --no-mmproj, --no-mmproj-auto whether to use multimodal projector file (if available), useful when using -hf (default: enabled) (env: LLAMA_ARG_MMPROJ_AUTO) --mmproj-offload, --no-mmproj-offload whether to enable GPU offloading for multimodal projector (default: enabled) (env: LLAMA_ARG_MMPROJ_OFFLOAD) --image-min-tokens N minimum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MIN_TOKENS) --image-max-tokens N maximum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MAX_TOKENS) --mtmd-batch-max-tokens N maximum number of image tokens per batch when encoding images (default: 1024) (env: LLAMA_ARG_MTMD_BATCH_MAX_TOKENS) -a, --alias STRING set model name aliases, comma-separated (to be used by API) (env: LLAMA_ARG_ALIAS) --tags STRING set model tags, comma-separated (informational, not used for routing) (env: LLAMA_ARG_TAGS) --embd-normalize N normalisation for embeddings (default: 2) (-1=none, 0=max absolute int16, 1=taxicab, 2=euclidean, >2=p-norm) --host HOST ip address to listen, or bind to an UNIX socket if the address ends with .sock (default: 127.0.0.1) (env: LLAMA_ARG_HOST) --port PORT port to listen (default: 8080) (env: LLAMA_ARG_PORT) --reuse-port allow multiple sockets to bind to the same port (default: disabled) (env: LLAMA_ARG_REUSE_PORT) --path PATH path to serve static files from (default: ) (env: LLAMA_ARG_STATIC_PATH) --cors-origins ORIGINS comma-separated list of allowed origins for CORS (default: *) if set to special value 'localhost', reflect the Origin header only if it is localhost (env: LLAMA_ARG_CORS_ORIGINS) --cors-methods METHODS comma-separated list of allowed methods for CORS (default: GET, POST, DELETE, OPTIONS) (env: LLAMA_ARG_CORS_METHODS) --cors-headers HEADERS comma-separated list of allowed headers for CORS (default: *) (env: LLAMA_ARG_CORS_HEADERS) --cors-credentials, --no-cors-credentials whether to allow credentials for CORS (default: enabled) note: if this is enabled and --cors-origins is set to * (default), the Origin header will be echoed back, and credentials will always be allowed (env: LLAMA_ARG_CORS_CREDENTIALS) --api-prefix PREFIX prefix path the server serves from, without the trailing slash (default: ) (env: LLAMA_ARG_API_PREFIX) --ui-config, --webui-config JSON JSON that provides default UI settings (overrides UI defaults) (env: LLAMA_ARG_UI_CONFIG) --ui-config-file, --webui-config-file PATH JSON file that provides default UI settings (overrides UI defaults) (env: LLAMA_ARG_UI_CONFIG_FILE) --ui-mcp-proxy, --webui-mcp-proxy, --no-ui-mcp-proxy, --no-webui-mcp-proxy experimental: whether to enable MCP CORS proxy - do not enable in untrusted environments (default: disabled) (env: LLAMA_ARG_UI_MCP_PROXY) --tools TOOL1,TOOL2,... experimental: whether to enable built-in tools for AI agents - do not enable in untrusted environments (default: no tools) specify "all" to enable all tools available tools: read_file, file_glob_search, grep_search, exec_shell_command, write_file, edit_file, get_datetime note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_TOOLS) --mcp-servers-config PATH experimental: path to JSON file with MCP server definitions (Cursor-compatible format) - do not enable in untrusted environments (default: none) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_MCP_SERVERS_CONFIG) --mcp-servers-json JSON experimental: inline JSON with MCP server definitions (Cursor-compatible format) - do not enable in untrusted environments (default: none) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_MCP_SERVERS_JSON) -ag, --agent, -no-ag, --no-agent whether to enable CORS proxy and all built-in tools - do not enable in untrusted environments (default: disabled) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_AGENT) --ui, --webui, --no-ui, --no-webui whether to enable the Web UI (default: enabled) (env: LLAMA_ARG_UI) --embedding, --embeddings restrict to only support embedding use case; use only with dedicated embedding models (default: disabled) (env: LLAMA_ARG_EMBEDDINGS) --rerank, --reranking enable reranking endpoint on server (default: disabled) (env: LLAMA_ARG_RERANKING) --api-key KEY API key to use for authentication, multiple keys can be provided as a comma-separated list (default: none) (env: LLAMA_API_KEY) --api-key-file FNAME path to file containing API keys, one per line; lines starting with a hash are treated as comments (default: none) (env: LLAMA_ARG_API_KEY_FILE) --ssl-key-file FNAME path to file a PEM-encoded SSL private key (env: LLAMA_ARG_SSL_KEY_FILE) --ssl-cert-file FNAME path to file a PEM-encoded SSL certificate (env: LLAMA_ARG_SSL_CERT_FILE) --chat-template-kwargs STRING sets additional params for the json template parser, must be a valid json object string, e.g. '{"key1":"value1","key2":"value2"}' (env: LLAMA_ARG_CHAT_TEMPLATE_KWARGS) -to, --timeout N server read/write timeout in seconds (default: 3600) (env: LLAMA_ARG_TIMEOUT) --sse-ping-interval N server SSE ping interval in seconds (-1 = disabled, default: 30) (env: LLAMA_ARG_SSE_PING_INTERVAL) --threads-http N number of threads used to process HTTP requests (default: -1) (env: LLAMA_ARG_THREADS_HTTP) --cache-prompt, --no-cache-prompt whether to enable prompt caching (default: enabled) (env: LLAMA_ARG_CACHE_PROMPT) --cache-reuse N min chunk size to attempt reusing from the cache via KV shifting, requires prompt caching to be enabled (default: 0) [(card)](https://ggml.ai/f0.png) (env: LLAMA_ARG_CACHE_REUSE) --metrics enable prometheus compatible metrics endpoint (default: disabled) (env: LLAMA_ARG_ENDPOINT_METRICS) --props enable changing global properties via POST /props (default: disabled) (env: LLAMA_ARG_ENDPOINT_PROPS) --slots, --no-slots expose slots monitoring endpoint (default: enabled) (env: LLAMA_ARG_ENDPOINT_SLOTS) --slot-save-path PATH path to save slot kv cache (default: disabled) --media-path PATH directory for loading local media files; files can be accessed via file:// URLs using relative paths (default: disabled) --models-dir PATH directory containing models for the router server (default: disabled) (env: LLAMA_ARG_MODELS_DIR) --models-preset PATH path to INI file containing model presets for the router server (default: disabled) (env: LLAMA_ARG_MODELS_PRESET) --models-max N for router server, maximum number of models to load simultaneously (default: 4, 0 = unlimited) (env: LLAMA_ARG_MODELS_MAX) --models-autoload, --no-models-autoload for router server, whether to automatically load models (default: enabled) (env: LLAMA_ARG_MODELS_AUTOLOAD) --jinja, --no-jinja whether to use jinja template engine for chat (default: enabled) (env: LLAMA_ARG_JINJA) --reasoning-format FORMAT controls whether thought tags are allowed and/or extracted from the response, and in which format they're returned; one of: - none: leaves thoughts unparsed in `message.content` - deepseek: puts thoughts in `message.reasoning_content` - deepseek-legacy: keeps `<think>` tags in `message.content` while also populating `message.reasoning_content` (default: auto) (env: LLAMA_ARG_THINK) -rea, --reasoning [on|off|auto] Use reasoning/thinking in the chat ('on', 'off', or 'auto', default: 'auto' (detect from template)) (env: LLAMA_ARG_REASONING) --reasoning-budget N token budget for thinking: -1 for unrestricted, 0 for immediate end, N>0 for token budget (default: -1) (env: LLAMA_ARG_THINK_BUDGET) --reasoning-budget-message MESSAGE message injected before the end-of-thinking tag when reasoning budget is exhausted (default: none) (env: LLAMA_ARG_THINK_BUDGET_MESSAGE) --reasoning-preserve, --no-reasoning-preserve preserve reasoning trace in the full history, not just the last assistant message (default: template default) compatible with certain templates having 'supports_preserve_reasoning' capability example: https://docs.z.ai/guides/capabilities/thinking-mode#preserved-thinking (env: LLAMA_ARG_REASONING_PRESERVE) --chat-template JINJA_TEMPLATE set custom jinja chat template (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE) --chat-template-file JINJA_TEMPLATE_FILE set custom jinja chat template file (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE_FILE) --skip-chat-parsing, --no-skip-chat-parsing force a pure content parser, even if a Jinja template is specified; model will output everything in the content section, including any reasoning and/or tool calls (default: disabled) (env: LLAMA_ARG_SKIP_CHAT_PARSING) --prefill-assistant, --no-prefill-assistant whether to prefill the assistant's response if the last message is an assistant message (default: prefill enabled) when this flag is set, if the last message is an assistant message then it will be treated as a full message and not prefilled (env: LLAMA_ARG_PREFILL_ASSISTANT) -sps, --slot-prompt-similarity SIMILARITY how much the prompt of a request must match the prompt of a slot in order to use that slot (default: 0.10, 0.0 = disabled) --lora-init-without-apply load LoRA adapters without applying them (apply later via POST /lora-adapters) (default: disabled) --sleep-idle-seconds SECONDS number of seconds of idleness after which the server will sleep (default: -1; -1 = disabled) --log-prompts-dir PATH Log prompts to directory (auto-created if not present; only used for debugging, default: disabled) -mv, --model-vocoder FNAME vocoder model for audio generation (default: unused) --tts-use-guide-tokens Use guide tokens to improve TTS word recall --embd-gemma-default use default EmbeddingGemma model (note: can download weights from the internet) --fim-qwen-1.5b-default use default Qwen 2.5 Coder 1.5B (note: can download weights from the internet) --fim-qwen-3b-default use default Qwen 2.5 Coder 3B (note: can download weights from the internet) --fim-qwen-7b-default use default Qwen 2.5 Coder 7B (note: can download weights from the internet) --fim-qwen-7b-spec use Qwen 2.5 Coder 7B + 0.5B draft for speculative decoding (note: can download weights from the internet) --fim-qwen-14b-spec use Qwen 2.5 Coder 14B + 0.5B draft for speculative decoding (note: can download weights from the internet) --fim-qwen-30b-default use default Qwen 3 Coder 30B A3B Instruct (note: can download weights from the internet) --gpt-oss-20b-default use gpt-oss-20b (note: can download weights from the internet) --gpt-oss-120b-default use gpt-oss-120b (note: can download weights from the internet) --vision-gemma-4b-default use Gemma 3 4B QAT (note: can download weights from the internet) --vision-gemma-12b-default use Gemma 3 12B QAT (note: can download weights from the internet) --spec-default enable default speculative decoding config |
오호.. 여기서 초기화시에 뜨는구나
| $ ./llama-b10145/llama-server --host 0.0.0.0 --port 8081 -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf 0.00.420.157 I cmn common_param: common_params_print_info: verbosity = 3 (adjust with the `-lv N` CLI arg) 0.00.420.880 W srv llama_server: ----------------- 0.00.420.884 W srv llama_server: CORS is set to allow all origins ('*') and no API key is set 0.00.420.884 W srv llama_server: this can be a security risk (cross-origin attacks) 0.00.420.884 W srv llama_server: more info: https://github.com/ggml-org/llama.cpp/pull/25655 0.00.420.885 W srv llama_server: ----------------- 0.00.422.219 I srv load_model: loading model 'model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf' 0.04.105.768 I srv load_model: initializing, n_slots = 4, n_ctx_slot = 262144, kv_unified = 'true' 0.04.123.306 I srv init: chat template supports preserving reasoning, consider enabling it via --reasoning-preserve 0.04.123.354 I srv llama_server: model loaded 0.04.123.359 I srv llama_server: listening on http://0.0.0.0:8081 |
| $ ./llama-b10145/llama-server --host 0.0.0.0 --port 8081 -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -np 1 0.00.146.608 I cmn common_param: common_params_print_info: verbosity = 3 (adjust with the `-lv N` CLI arg) 0.00.147.059 W srv llama_server: ----------------- 0.00.147.062 W srv llama_server: CORS is set to allow all origins ('*') and no API key is set 0.00.147.062 W srv llama_server: this can be a security risk (cross-origin attacks) 0.00.147.063 W srv llama_server: more info: https://github.com/ggml-org/llama.cpp/pull/25655 0.00.147.063 W srv llama_server: ----------------- 0.00.148.332 I srv load_model: loading model 'model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf' 0.03.930.586 I srv load_model: initializing, n_slots = 1, n_ctx_slot = 262144, kv_unified = 'false' 0.03.948.234 I srv init: chat template supports preserving reasoning, consider enabling it via --reasoning-preserve 0.03.948.286 I srv llama_server: model loaded 0.03.948.292 I srv llama_server: listening on http://0.0.0.0:8081 |
| $ ./llama-b10145/llama-server --host 0.0.0.0 --port 8081 -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -np 8 0.00.294.633 I cmn common_param: common_params_print_info: verbosity = 3 (adjust with the `-lv N` CLI arg) 0.00.295.199 W srv llama_server: ----------------- 0.00.295.203 W srv llama_server: CORS is set to allow all origins ('*') and no API key is set 0.00.295.203 W srv llama_server: this can be a security risk (cross-origin attacks) 0.00.295.203 W srv llama_server: more info: https://github.com/ggml-org/llama.cpp/pull/25655 0.00.295.203 W srv llama_server: ----------------- 0.00.296.551 I srv load_model: loading model 'model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf' 0.10.613.365 I srv load_model: initializing, n_slots = 8, n_ctx_slot = 32768, kv_unified = 'false' 0.10.634.191 I srv init: chat template supports preserving reasoning, consider enabling it via --reasoning-preserve 0.10.634.243 I srv llama_server: model loaded 0.10.634.251 I srv llama_server: listening on http://0.0.0.0:8081 |
+
1080ti 11GB * 2 에다가 멀티로 괴롭혀 보기
3개 동시에는 27.03+28.21+28.21 = 77.45
1 개 단독에는 60.29
4개 동시에는 23.33+23.39+23.40+23.40 = 93.52
개인당 성능은 낮아져도 전체 출력량은 늘어나는 마법(!)
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -np 8 -sm layer --host 0.0.0.0 0.00.585.225 I log_info: verbosity = 3 (adjust with the `-lv N` CLI arg) 0.00.585.228 I device_info: 0.00.591.290 I - Vulkan0 : Intel(R) UHD Graphics 630 (CFL GT2) (23816 MiB, 23816 MiB free) 0.00.597.326 I - Vulkan1 : NVIDIA GeForce GTX 1080 Ti (11510 MiB, 11248 MiB free) 0.00.603.380 I - Vulkan2 : NVIDIA GeForce GTX 1080 Ti (11510 MiB, 11390 MiB free) 0.00.603.384 I - CPU : Intel(R) Core(TM) i5-8500 CPU @ 3.00GHz (31754 MiB, 31754 MiB free) 0.00.603.455 I system_info: n_threads = 6 (n_threads_batch = 6) / 6 | CPU : SSE3 = 1 | SSSE3 = 1 | AVX = 1 | AVX2 = 1 | F16C = 1 | FMA = 1 | BMI2 = 1 | LLAMAFILE = 1 | OPENMP = 1 | REPACK = 1 | 0.00.603.859 I srv init: running without SSL 0.00.605.375 I srv init: using 12 threads for HTTP server 0.00.605.651 I srv start: binding port with default address family 0.00.606.857 I srv llama_server: loading model 0.00.606.866 I srv load_model: loading model 'model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf' 0.00.606.906 I common_init_result: fitting params to device memory ... 0.00.606.906 I common_init_result: (for bugs during this step try to reproduce them with -fit off, or provide --verbose logs if the bug only occurs with -fit on) 0.29.465.233 W llama_context: n_ctx_seq (32768) < n_ctx_train (262144) -- the full capacity of the model will not be utilized 0.29.859.072 I common_init_from_params: warming up the model with an empty run - please wait ... (--no-warmup to disable) 0.30.807.769 I srv load_model: initializing slots, n_slots = 8 0.31.132.316 W srv load_model: speculative decoding will use checkpoints 0.31.132.491 W common_speculative_init: no implementations specified for speculative decoding 0.31.132.503 I slot load_model: id 0 | task -1 | new slot, n_ctx = 32768 0.31.132.514 I slot load_model: id 1 | task -1 | new slot, n_ctx = 32768 0.31.132.516 I slot load_model: id 2 | task -1 | new slot, n_ctx = 32768 0.31.132.518 I slot load_model: id 3 | task -1 | new slot, n_ctx = 32768 0.31.132.519 I slot load_model: id 4 | task -1 | new slot, n_ctx = 32768 0.31.132.521 I slot load_model: id 5 | task -1 | new slot, n_ctx = 32768 0.31.132.522 I slot load_model: id 6 | task -1 | new slot, n_ctx = 32768 0.31.132.524 I slot load_model: id 7 | task -1 | new slot, n_ctx = 32768 0.31.132.789 I srv load_model: prompt cache is enabled, size limit: 8192 MiB 0.31.132.797 I srv load_model: use `--cache-ram 0` to disable the prompt cache 0.31.132.799 I srv load_model: for more info see https://github.com/ggml-org/llama.cpp/pull/16391 0.31.132.800 I srv load_model: context checkpoints enabled, max = 32, min spacing = 256 0.31.132.857 I srv init: idle slots will be saved to prompt cache upon starting a new task 0.31.193.165 I init: chat template, example_format: '<|im_start|>system You are a helpful assistant<|im_end|> <|im_start|>user Hello<|im_end|> <|im_start|>assistant Hi there<|im_end|> <|im_start|>user How are you?<|im_end|> <|im_start|>assistant <think> ' 0.31.210.696 I srv init: init: chat template, thinking = 1 0.31.210.739 I srv llama_server: model loaded 0.31.210.743 I srv llama_server: server is listening on http://0.0.0.0:8080 0.31.210.748 I srv update_slots: all slots are idle 1.33.205.501 I srv params_from_: Chat format: peg-native 1.33.205.716 I slot get_availabl: id 7 | task -1 | selected slot by LRU, t_last = -1 1.33.205.718 I srv get_availabl: updating prompt cache 1.33.205.734 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 1.33.205.738 I srv update: - cache state: 0 prompts, 0.000 MiB (limits: 8192.000 MiB, 262144 tokens, 8589934592 est) 1.33.205.738 I srv get_availabl: prompt cache update took 0.02 ms 1.33.205.785 I reasoning-budget: activated, budget=2147483647 tokens 1.33.205.786 I reasoning-budget: deactivated (natural end) 1.33.205.807 I slot launch_slot_: id 7 | task 0 | processing task, is_child = 0 1.33.205.810 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 1.33.205.810 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 1.33.205.811 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 1.33.205.811 I slot process_sing: id 3 | task -1 | saving idle slot to prompt cache 1.33.205.811 I slot process_sing: id 4 | task -1 | saving idle slot to prompt cache 1.33.205.811 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 1.33.205.812 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 1.33.735.604 I srv params_from_: Chat format: peg-native 1.34.598.059 I srv params_from_: Chat format: peg-native 1.34.696.573 I slot get_availabl: id 6 | task -1 | selected slot by LRU, t_last = -1 1.34.696.575 I srv get_availabl: updating prompt cache 1.34.696.578 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 1.34.696.581 I srv update: - cache state: 0 prompts, 0.000 MiB (limits: 8192.000 MiB, 262144 tokens, 8589934592 est) 1.34.696.581 I srv get_availabl: prompt cache update took 0.01 ms 1.34.696.664 I reasoning-budget: activated, budget=2147483647 tokens 1.34.696.664 I reasoning-budget: deactivated (natural end) 1.34.696.675 I slot launch_slot_: id 6 | task 2 | processing task, is_child = 0 1.34.696.676 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 1.34.696.676 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 1.34.696.677 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 1.34.696.677 I slot process_sing: id 3 | task -1 | saving idle slot to prompt cache 1.34.696.677 I slot process_sing: id 4 | task -1 | saving idle slot to prompt cache 1.34.696.678 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 1.34.696.680 I slot get_availabl: id 5 | task -1 | selected slot by LRU, t_last = -1 1.34.696.680 I srv get_availabl: updating prompt cache 1.34.696.681 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 1.34.696.682 I srv update: - cache state: 0 prompts, 0.000 MiB (limits: 8192.000 MiB, 262144 tokens, 8589934592 est) 1.34.696.683 I srv get_availabl: prompt cache update took 0.00 ms 1.34.696.719 I reasoning-budget: activated, budget=2147483647 tokens 1.34.696.719 I reasoning-budget: deactivated (natural end) 1.34.696.726 I slot launch_slot_: id 5 | task 3 | processing task, is_child = 0 1.34.696.727 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 1.34.696.727 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 1.34.696.727 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 1.34.696.728 I slot process_sing: id 3 | task -1 | saving idle slot to prompt cache 1.34.696.728 I slot process_sing: id 4 | task -1 | saving idle slot to prompt cache 1.34.988.803 I slot create_check: id 7 | task 0 | created context checkpoint 1 of 32 (pos_min = 28, pos_max = 28, n_tokens = 29, size = 62.813 MiB) 1.36.425.849 I slot create_check: id 5 | task 3 | created context checkpoint 1 of 32 (pos_min = 29, pos_max = 29, n_tokens = 30, size = 62.813 MiB) 1.36.474.645 I slot create_check: id 6 | task 2 | created context checkpoint 1 of 32 (pos_min = 28, pos_max = 28, n_tokens = 29, size = 62.813 MiB) 1.40.908.116 I slot print_timing: id 7 | task 0 | n_decoded = 100, tg = 22.03 t/s 1.40.941.055 I slot print_timing: id 5 | task 3 | n_decoded = 100, tg = 25.99 t/s 1.40.942.209 I slot print_timing: id 6 | task 2 | n_decoded = 100, tg = 25.99 t/s 1.43.931.725 I slot print_timing: id 7 | task 0 | n_decoded = 187, tg = 24.72 t/s 1.43.964.981 I slot print_timing: id 5 | task 3 | n_decoded = 187, tg = 27.21 t/s 1.43.967.199 I slot print_timing: id 6 | task 2 | n_decoded = 187, tg = 27.21 t/s 1.46.946.263 I slot print_timing: id 7 | task 0 | n_decoded = 273, tg = 25.81 t/s 1.46.977.938 I slot print_timing: id 5 | task 3 | n_decoded = 273, tg = 27.62 t/s 1.46.978.729 I slot print_timing: id 6 | task 2 | n_decoded = 273, tg = 27.62 t/s 1.49.960.552 I slot print_timing: id 7 | task 0 | n_decoded = 360, tg = 26.48 t/s 1.49.991.687 I slot print_timing: id 5 | task 3 | n_decoded = 360, tg = 27.91 t/s 1.49.992.249 I slot print_timing: id 6 | task 2 | n_decoded = 360, tg = 27.91 t/s 1.52.980.539 I slot print_timing: id 7 | task 0 | n_decoded = 449, tg = 27.03 t/s 1.53.012.245 I slot print_timing: id 5 | task 3 | n_decoded = 449, tg = 28.21 t/s 1.53.013.043 I slot print_timing: id 6 | task 2 | n_decoded = 449, tg = 28.21 t/s 1.55.990.978 I slot print_timing: id 7 | task 0 | n_decoded = 534, tg = 27.21 t/s 1.56.022.948 I slot print_timing: id 5 | task 3 | n_decoded = 534, tg = 28.21 t/s 1.56.023.747 I slot print_timing: id 6 | task 2 | n_decoded = 534, tg = 28.21 t/s 1.58.999.665 I slot print_timing: id 7 | task 0 | n_decoded = 620, tg = 27.40 t/s 1.59.031.691 I slot print_timing: id 5 | task 3 | n_decoded = 620, tg = 28.26 t/s 1.59.032.485 I slot print_timing: id 6 | task 2 | n_decoded = 620, tg = 28.26 t/s 2.01.148.186 I slot print_timing: id 5 | task 3 | prompt eval time = 2396.66 ms / 34 tokens ( 70.49 ms per token, 14.19 tokens per second) 2.01.148.202 I slot print_timing: id 5 | task 3 | eval time = 24054.74 ms / 680 tokens ( 35.37 ms per token, 28.27 tokens per second) 2.01.148.206 I slot print_timing: id 5 | task 3 | total time = 26451.40 ms / 714 tokens 2.01.148.217 I slot print_timing: id 5 | task 3 | graphs reused = 677 2.01.148.299 I slot release: id 5 | task 3 | stop processing: n_tokens = 713, truncated = 0 2.02.015.614 I slot print_timing: id 7 | task 0 | n_decoded = 714, tg = 27.84 t/s 2.02.041.674 I slot print_timing: id 6 | task 2 | n_decoded = 714, tg = 28.62 t/s 2.05.026.800 I slot print_timing: id 7 | task 0 | n_decoded = 832, tg = 29.03 t/s 2.05.050.825 I slot print_timing: id 6 | task 2 | n_decoded = 832, tg = 29.76 t/s 2.08.043.277 I slot print_timing: id 7 | task 0 | n_decoded = 948, tg = 29.93 t/s 2.08.066.873 I slot print_timing: id 6 | task 2 | n_decoded = 948, tg = 30.61 t/s 2.11.052.970 I slot print_timing: id 7 | task 0 | n_decoded = 1066, tg = 30.73 t/s 2.11.076.619 I slot print_timing: id 6 | task 2 | n_decoded = 1066, tg = 31.37 t/s 2.14.057.716 I slot print_timing: id 7 | task 0 | n_decoded = 1185, tg = 31.44 t/s 2.14.082.063 I slot print_timing: id 6 | task 2 | n_decoded = 1185, tg = 32.04 t/s 2.16.506.427 I slot print_timing: id 6 | task 2 | prompt eval time = 2398.32 ms / 33 tokens ( 72.68 ms per token, 13.76 tokens per second) 2.16.506.431 I slot print_timing: id 6 | task 2 | eval time = 39411.32 ms / 1280 tokens ( 30.79 ms per token, 32.48 tokens per second) 2.16.506.432 I slot print_timing: id 6 | task 2 | total time = 41809.64 ms / 1313 tokens 2.16.506.433 I slot print_timing: id 6 | task 2 | graphs reused = 1273 2.16.506.446 I slot release: id 6 | task 2 | stop processing: n_tokens = 1312, truncated = 0 2.17.062.598 I slot print_timing: id 7 | task 0 | n_decoded = 1314, tg = 32.29 t/s 2.18.497.615 I slot print_timing: id 7 | task 0 | prompt eval time = 3162.02 ms / 33 tokens ( 95.82 ms per token, 10.44 tokens per second) 2.18.497.630 I slot print_timing: id 7 | task 0 | eval time = 42129.72 ms / 1400 tokens ( 30.09 ms per token, 33.23 tokens per second) 2.18.497.635 I slot print_timing: id 7 | task 0 | total time = 45291.75 ms / 1433 tokens 2.18.497.638 I slot print_timing: id 7 | task 0 | graphs reused = 1391 2.18.497.686 I slot release: id 7 | task 0 | stop processing: n_tokens = 1432, truncated = 0 2.18.497.719 I srv update_slots: all slots are idle 2.19.344.323 I srv params_from_: Chat format: peg-native 2.19.344.536 I slot get_availabl: id 5 | task -1 | selected slot by LCP similarity, sim_best = 0.136 (> 0.100 thold), f_keep = 0.004 2.19.344.538 I srv get_availabl: updating prompt cache 2.19.344.818 W srv prompt_save: - saving prompt with length 713, total state size = 76.753 MiB (draft: 0.000 MiB) 2.19.439.982 I srv load: - looking for better prompt, base f_keep = 0.004, sim = 0.136 2.19.439.988 I srv update: - cache state: 1 prompts, 139.566 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 2.19.439.989 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 2.19.439.990 I srv get_availabl: prompt cache update took 95.45 ms 2.19.440.036 I reasoning-budget: activated, budget=2147483647 tokens 2.19.440.037 I reasoning-budget: deactivated (natural end) 2.19.440.063 I slot launch_slot_: id 5 | task 1404 | processing task, is_child = 0 2.19.440.065 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 2.19.440.066 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 2.19.440.066 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 2.19.440.066 I slot process_sing: id 3 | task -1 | saving idle slot to prompt cache 2.19.440.067 I slot process_sing: id 4 | task -1 | saving idle slot to prompt cache 2.19.440.067 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 2.19.440.296 W srv prompt_save: - saving prompt with length 1312, total state size = 88.464 MiB (draft: 0.000 MiB) 2.19.542.996 I srv update: - cache state: 2 prompts, 290.843 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 2.19.543.000 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 2.19.543.001 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 2.19.543.002 I slot process_sing: id 7 | task -1 | saving idle slot to prompt cache 2.19.543.233 W srv prompt_save: - saving prompt with length 1432, total state size = 90.810 MiB (draft: 0.000 MiB) 2.19.647.786 I srv update: - cache state: 3 prompts, 444.466 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 2.19.647.790 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 2.19.647.791 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 2.19.647.792 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 2.19.647.803 I slot update_slots: id 5 | task 1404 | Checking checkpoint with [29, 29] against 3... 2.19.647.804 W slot update_slots: id 5 | task 1404 | forcing full prompt re-processing due to lack of cache data (likely due to SWA or hybrid/recurrent memory, see https://github.com/ggml-org/llama.cpp/pull/13194#issuecomment-2868343055) 2.19.647.805 W slot update_slots: id 5 | task 1404 | erased invalidated context checkpoint (pos_min = 29, pos_max = 29, n_tokens = 30, n_swa = 0, pos_next = 0, size = 62.813 MiB) 2.19.989.405 I slot create_check: id 5 | task 1404 | created context checkpoint 1 of 32 (pos_min = 17, pos_max = 17, n_tokens = 18, size = 62.813 MiB) 2.21.697.009 I slot print_timing: id 5 | task 1404 | n_decoded = 100, tg = 60.29 t/s 2.24.702.800 I slot print_timing: id 5 | task 1404 | n_decoded = 279, tg = 59.81 t/s 2.27.704.614 I slot print_timing: id 5 | task 1404 | n_decoded = 458, tg = 59.74 t/s 2.30.718.633 I slot print_timing: id 5 | task 1404 | n_decoded = 637, tg = 59.64 t/s 2.33.731.532 I slot print_timing: id 5 | task 1404 | n_decoded = 818, tg = 59.74 t/s 2.36.742.598 I slot print_timing: id 5 | task 1404 | n_decoded = 999, tg = 59.80 t/s 2.36.970.561 I slot print_timing: id 5 | task 1404 | prompt eval time = 390.49 ms / 22 tokens ( 17.75 ms per token, 56.34 tokens per second) 2.36.970.565 I slot print_timing: id 5 | task 1404 | eval time = 16932.25 ms / 1012 tokens ( 16.73 ms per token, 59.77 tokens per second) 2.36.970.566 I slot print_timing: id 5 | task 1404 | total time = 17322.75 ms / 1034 tokens 2.36.970.566 I slot print_timing: id 5 | task 1404 | graphs reused = 2397 2.36.970.580 I slot release: id 5 | task 1404 | stop processing: n_tokens = 1033, truncated = 0 2.36.970.594 I srv update_slots: all slots are idle 3.07.804.596 I srv params_from_: Chat format: peg-native 3.07.807.070 I slot get_availabl: id 4 | task -1 | selected slot by LRU, t_last = -1 3.07.807.073 I srv get_availabl: updating prompt cache 3.07.807.087 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 3.07.807.091 I srv update: - cache state: 3 prompts, 444.466 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 3.07.807.092 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 3.07.807.093 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 3.07.807.094 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 3.07.807.094 I srv get_availabl: prompt cache update took 0.02 ms 3.07.807.137 I reasoning-budget: activated, budget=2147483647 tokens 3.07.807.138 I reasoning-budget: deactivated (natural end) 3.07.807.154 I slot launch_slot_: id 4 | task 2418 | processing task, is_child = 0 3.07.807.154 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 3.07.807.155 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 3.07.807.155 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 3.07.807.155 I slot process_sing: id 3 | task -1 | saving idle slot to prompt cache 3.07.807.155 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 3.07.807.453 W srv prompt_save: - saving prompt with length 1033, total state size = 83.009 MiB (draft: 0.000 MiB) 3.07.960.564 I srv update: - cache state: 4 prompts, 590.288 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 3.07.960.573 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 3.07.960.576 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 3.07.960.578 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 3.07.960.579 I srv update: - prompt 0x648afefdd6f0: 1033 tokens, checkpoints: 1, 145.822 MiB 3.07.960.582 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 3.07.961.122 W srv prompt_save: - saving prompt with length 1312, total state size = 88.464 MiB (draft: 0.000 MiB) 3.07.961.130 I srv alloc: - prompt is already in the cache, skipping 3.07.961.131 I slot process_sing: id 7 | task -1 | saving idle slot to prompt cache 3.07.961.670 W srv prompt_save: - saving prompt with length 1432, total state size = 90.810 MiB (draft: 0.000 MiB) 3.07.961.676 I srv alloc: - prompt is already in the cache, skipping 3.10.000.356 I srv params_from_: Chat format: peg-native 3.11.362.101 I srv params_from_: Chat format: peg-native 3.12.721.534 I srv params_from_: Chat format: peg-native 3.15.096.173 I slot get_availabl: id 3 | task -1 | selected slot by LRU, t_last = -1 3.15.096.176 I srv get_availabl: updating prompt cache 3.15.096.179 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 3.15.096.200 I srv update: - cache state: 4 prompts, 590.288 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 3.15.096.201 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 3.15.096.202 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 3.15.096.203 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 3.15.096.204 I srv update: - prompt 0x648afefdd6f0: 1033 tokens, checkpoints: 1, 145.822 MiB 3.15.096.204 I srv get_availabl: prompt cache update took 0.03 ms 3.15.096.272 I reasoning-budget: activated, budget=2147483647 tokens 3.15.096.273 I reasoning-budget: deactivated (natural end) 3.15.096.285 I slot launch_slot_: id 3 | task 2420 | processing task, is_child = 0 3.15.096.286 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 3.15.096.286 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 3.15.096.287 I slot process_sing: id 2 | task -1 | saving idle slot to prompt cache 3.15.096.287 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 3.15.096.568 W srv prompt_save: - saving prompt with length 1033, total state size = 83.009 MiB (draft: 0.000 MiB) 3.15.096.571 I srv alloc: - prompt is already in the cache, skipping 3.15.096.572 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 3.15.096.815 W srv prompt_save: - saving prompt with length 1312, total state size = 88.464 MiB (draft: 0.000 MiB) 3.15.096.818 I srv alloc: - prompt is already in the cache, skipping 3.15.096.818 I slot process_sing: id 7 | task -1 | saving idle slot to prompt cache 3.15.097.050 W srv prompt_save: - saving prompt with length 1432, total state size = 90.810 MiB (draft: 0.000 MiB) 3.15.097.053 I srv alloc: - prompt is already in the cache, skipping 3.15.097.054 I slot get_availabl: id 2 | task -1 | selected slot by LRU, t_last = -1 3.15.097.054 I srv get_availabl: updating prompt cache 3.15.097.070 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 3.15.097.072 I srv update: - cache state: 4 prompts, 590.288 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 3.15.097.073 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 3.15.097.073 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 3.15.097.074 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 3.15.097.075 I srv update: - prompt 0x648afefdd6f0: 1033 tokens, checkpoints: 1, 145.822 MiB 3.15.097.076 I srv get_availabl: prompt cache update took 0.02 ms 3.15.097.097 I reasoning-budget: activated, budget=2147483647 tokens 3.15.097.097 I reasoning-budget: deactivated (natural end) 3.15.097.114 I slot launch_slot_: id 2 | task 2421 | processing task, is_child = 0 3.15.097.114 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 3.15.097.114 I slot process_sing: id 1 | task -1 | saving idle slot to prompt cache 3.15.097.115 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 3.15.097.391 W srv prompt_save: - saving prompt with length 1033, total state size = 83.009 MiB (draft: 0.000 MiB) 3.15.097.394 I srv alloc: - prompt is already in the cache, skipping 3.15.097.394 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 3.15.097.610 W srv prompt_save: - saving prompt with length 1312, total state size = 88.464 MiB (draft: 0.000 MiB) 3.15.097.612 I srv alloc: - prompt is already in the cache, skipping 3.15.097.612 I slot process_sing: id 7 | task -1 | saving idle slot to prompt cache 3.15.097.854 W srv prompt_save: - saving prompt with length 1432, total state size = 90.810 MiB (draft: 0.000 MiB) 3.15.097.856 I srv alloc: - prompt is already in the cache, skipping 3.15.097.858 I slot get_availabl: id 1 | task -1 | selected slot by LRU, t_last = -1 3.15.097.858 I srv get_availabl: updating prompt cache 3.15.097.873 I srv load: - looking for better prompt, base f_keep = -1.000, sim = 0.000 3.15.097.875 I srv update: - cache state: 4 prompts, 590.288 MiB (limits: 8192.000 MiB, 262144 tokens, 262144 est) 3.15.097.876 I srv update: - prompt 0x648aff24a1d0: 713 tokens, checkpoints: 1, 139.566 MiB 3.15.097.876 I srv update: - prompt 0x648aff2470a0: 1312 tokens, checkpoints: 1, 151.277 MiB 3.15.097.877 I srv update: - prompt 0x648aff24b750: 1432 tokens, checkpoints: 1, 153.623 MiB 3.15.097.878 I srv update: - prompt 0x648afefdd6f0: 1033 tokens, checkpoints: 1, 145.822 MiB 3.15.097.878 I srv get_availabl: prompt cache update took 0.02 ms 3.15.097.894 I reasoning-budget: activated, budget=2147483647 tokens 3.15.097.894 I reasoning-budget: deactivated (natural end) 3.15.097.901 I slot launch_slot_: id 1 | task 2422 | processing task, is_child = 0 3.15.097.901 I slot process_sing: id 0 | task -1 | saving idle slot to prompt cache 3.15.097.902 I slot process_sing: id 5 | task -1 | saving idle slot to prompt cache 3.15.098.156 W srv prompt_save: - saving prompt with length 1033, total state size = 83.009 MiB (draft: 0.000 MiB) 3.15.098.158 I srv alloc: - prompt is already in the cache, skipping 3.15.098.159 I slot process_sing: id 6 | task -1 | saving idle slot to prompt cache 3.15.098.362 W srv prompt_save: - saving prompt with length 1312, total state size = 88.464 MiB (draft: 0.000 MiB) 3.15.098.383 I srv alloc: - prompt is already in the cache, skipping 3.15.098.383 I slot process_sing: id 7 | task -1 | saving idle slot to prompt cache 3.15.098.613 W srv prompt_save: - saving prompt with length 1432, total state size = 90.810 MiB (draft: 0.000 MiB) 3.15.098.615 I srv alloc: - prompt is already in the cache, skipping 3.15.098.810 I slot print_timing: id 4 | task 2418 | prompt processing, n_tokens = 817, progress = 0.61, t = 7.14 s / 114.47 tokens per second 3.23.731.318 I slot print_timing: id 1 | task 2422 | prompt processing, n_tokens = 218, progress = 0.30, t = 8.63 s / 25.25 tokens per second 3.23.731.376 I slot print_timing: id 2 | task 2421 | prompt processing, n_tokens = 537, progress = 0.51, t = 8.63 s / 62.21 tokens per second 3.23.731.418 I slot print_timing: id 3 | task 2420 | prompt processing, n_tokens = 936, progress = 0.64, t = 8.63 s / 108.43 tokens per second 3.23.731.472 I slot print_timing: id 4 | task 2418 | prompt processing, n_tokens = 1174, progress = 0.88, t = 15.77 s / 74.45 tokens per second 3.30.615.240 I slot print_timing: id 1 | task 2422 | prompt processing, n_tokens = 711, progress = 0.97, t = 15.52 s / 45.82 tokens per second 3.31.453.006 I slot create_check: id 1 | task 2422 | created context checkpoint 1 of 32 (pos_min = 710, pos_max = 710, n_tokens = 711, size = 62.813 MiB) 3.31.453.012 I slot print_timing: id 2 | task 2421 | prompt processing, n_tokens = 1030, progress = 0.98, t = 16.35 s / 62.98 tokens per second 3.31.503.501 I slot create_check: id 2 | task 2421 | created context checkpoint 1 of 32 (pos_min = 1029, pos_max = 1029, n_tokens = 1030, size = 62.813 MiB) 3.31.503.507 I slot print_timing: id 3 | task 2420 | prompt processing, n_tokens = 1428, progress = 0.98, t = 16.40 s / 87.05 tokens per second 3.31.554.228 I slot create_check: id 3 | task 2420 | created context checkpoint 1 of 32 (pos_min = 1427, pos_max = 1427, n_tokens = 1428, size = 62.813 MiB) 3.31.554.234 I slot print_timing: id 4 | task 2418 | prompt processing, n_tokens = 1310, progress = 0.98, t = 23.59 s / 55.53 tokens per second 3.31.604.973 I slot create_check: id 4 | task 2418 | created context checkpoint 1 of 32 (pos_min = 1309, pos_max = 1309, n_tokens = 1310, size = 62.813 MiB) 3.32.350.167 I slot print_timing: id 1 | task 2422 | prompt processing, n_tokens = 730, progress = 0.99, t = 17.25 s / 42.32 tokens per second 3.32.350.287 I slot print_timing: id 2 | task 2421 | prompt processing, n_tokens = 1049, progress = 1.00, t = 17.25 s / 60.81 tokens per second 3.32.350.446 I slot print_timing: id 3 | task 2420 | prompt processing, n_tokens = 1448, progress = 1.00, t = 17.25 s / 83.93 tokens per second 3.32.350.632 I slot print_timing: id 4 | task 2418 | prompt processing, n_tokens = 1329, progress = 1.00, t = 24.39 s / 54.49 tokens per second 3.37.375.672 I slot print_timing: id 1 | task 2422 | n_decoded = 100, tg = 23.32 t/s 3.37.377.034 I slot print_timing: id 2 | task 2421 | n_decoded = 100, tg = 23.32 t/s 3.37.378.398 I slot print_timing: id 3 | task 2420 | n_decoded = 100, tg = 23.33 t/s 3.37.379.825 I slot print_timing: id 4 | task 2418 | n_decoded = 100, tg = 23.33 t/s 3.40.397.975 I slot print_timing: id 1 | task 2422 | n_decoded = 171, tg = 23.39 t/s 3.40.398.611 I slot print_timing: id 2 | task 2421 | n_decoded = 171, tg = 23.40 t/s 3.40.399.236 I slot print_timing: id 3 | task 2420 | n_decoded = 171, tg = 23.40 t/s 3.40.399.864 I slot print_timing: id 4 | task 2418 | n_decoded = 171, tg = 23.40 t/s 3.43.403.430 I slot print_timing: id 1 | task 2422 | n_decoded = 243, tg = 23.56 t/s 3.43.404.042 I slot print_timing: id 2 | task 2421 | n_decoded = 243, tg = 23.56 t/s 3.43.404.654 I slot print_timing: id 3 | task 2420 | n_decoded = 243, tg = 23.56 t/s 3.43.405.259 I slot print_timing: id 4 | task 2418 | n_decoded = 243, tg = 23.57 t/s 3.46.427.117 I slot print_timing: id 1 | task 2422 | n_decoded = 316, tg = 23.69 t/s 3.46.427.750 I slot print_timing: id 2 | task 2421 | n_decoded = 316, tg = 23.69 t/s 3.46.428.383 I slot print_timing: id 3 | task 2420 | n_decoded = 316, tg = 23.69 t/s 3.46.429.014 I slot print_timing: id 4 | task 2418 | n_decoded = 316, tg = 23.70 t/s 3.49.443.255 I slot print_timing: id 1 | task 2422 | n_decoded = 389, tg = 23.78 t/s 3.49.443.911 I slot print_timing: id 2 | task 2421 | n_decoded = 389, tg = 23.79 t/s 3.49.444.560 I slot print_timing: id 3 | task 2420 | n_decoded = 389, tg = 23.79 t/s 3.49.445.210 I slot print_timing: id 4 | task 2418 | n_decoded = 389, tg = 23.79 t/s 3.52.451.340 I slot print_timing: id 1 | task 2422 | n_decoded = 462, tg = 23.86 t/s 3.52.451.973 I slot print_timing: id 2 | task 2421 | n_decoded = 462, tg = 23.86 t/s 3.52.452.605 I slot print_timing: id 3 | task 2420 | n_decoded = 462, tg = 23.86 t/s 3.52.453.238 I slot print_timing: id 4 | task 2418 | n_decoded = 462, tg = 23.86 t/s 3.53.525.843 I slot print_timing: id 1 | task 2422 | prompt eval time = 17989.33 ms / 734 tokens ( 24.51 ms per token, 40.80 tokens per second) 3.53.525.847 I slot print_timing: id 1 | task 2422 | eval time = 20437.87 ms / 488 tokens ( 41.88 ms per token, 23.88 tokens per second) 3.53.525.848 I slot print_timing: id 1 | task 2422 | total time = 38427.19 ms / 1222 tokens 3.53.525.849 I slot print_timing: id 1 | task 2422 | graphs reused = 2881 3.53.525.902 I slot release: id 1 | task 2422 | stop processing: n_tokens = 1221, truncated = 0 3.53.865.447 I slot print_timing: id 4 | task 2418 | prompt eval time = 25131.75 ms / 1333 tokens ( 18.85 ms per token, 53.04 tokens per second) 3.53.865.451 I slot print_timing: id 4 | task 2418 | eval time = 20772.00 ms / 498 tokens ( 41.71 ms per token, 23.97 tokens per second) 3.53.865.452 I slot print_timing: id 4 | task 2418 | total time = 45903.75 ms / 1831 tokens 3.53.865.452 I slot print_timing: id 4 | task 2418 | graphs reused = 2890 3.53.865.567 I slot release: id 4 | task 2418 | stop processing: n_tokens = 1830, truncated = 0 3.55.473.255 I slot print_timing: id 2 | task 2421 | n_decoded = 561, tg = 25.06 t/s 3.55.474.053 I slot print_timing: id 3 | task 2420 | n_decoded = 561, tg = 25.06 t/s 3.58.477.121 I slot print_timing: id 2 | task 2421 | n_decoded = 681, tg = 26.82 t/s 3.58.477.702 I slot print_timing: id 3 | task 2420 | n_decoded = 681, tg = 26.83 t/s 4.01.479.346 I slot print_timing: id 2 | task 2421 | n_decoded = 801, tg = 28.21 t/s 4.01.480.148 I slot print_timing: id 3 | task 2420 | n_decoded = 801, tg = 28.22 t/s 4.04.490.872 I slot print_timing: id 2 | task 2421 | n_decoded = 921, tg = 29.33 t/s 4.04.491.520 I slot print_timing: id 3 | task 2420 | n_decoded = 921, tg = 29.33 t/s 4.05.363.400 I slot print_timing: id 2 | task 2421 | prompt eval time = 17991.09 ms / 1053 tokens ( 17.09 ms per token, 58.53 tokens per second) 4.05.363.404 I slot print_timing: id 2 | task 2421 | eval time = 32273.60 ms / 956 tokens ( 33.76 ms per token, 29.62 tokens per second) 4.05.363.405 I slot print_timing: id 2 | task 2421 | total time = 50264.69 ms / 2009 tokens 4.05.363.406 I slot print_timing: id 2 | task 2421 | graphs reused = 3345 4.05.363.473 I slot release: id 2 | task 2421 | stop processing: n_tokens = 2008, truncated = 0 4.07.498.689 I slot print_timing: id 3 | task 2420 | n_decoded = 1086, tg = 31.56 t/s 4.10.510.974 I slot print_timing: id 3 | task 2420 | n_decoded = 1271, tg = 33.97 t/s 4.11.128.366 I slot print_timing: id 3 | task 2420 | prompt eval time = 17992.87 ms / 1452 tokens ( 12.39 ms per token, 80.70 tokens per second) 4.11.128.369 I slot print_timing: id 3 | task 2420 | eval time = 38036.73 ms / 1309 tokens ( 29.06 ms per token, 34.41 tokens per second) 4.11.128.370 I slot print_timing: id 3 | task 2420 | total time = 56029.60 ms / 2761 tokens 4.11.128.371 I slot print_timing: id 3 | task 2420 | graphs reused = 3696 4.11.128.488 I slot release: id 3 | task 2420 | stop processing: n_tokens = 2760, truncated = 0 4.11.128.498 I srv update_slots: all slots are idle |
+
최대 컨텍스트는 유지되고, 개인당 컨텍스트는 무조건 줄어드는건가?
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 1 0.08.367.856 W common_speculative_init: no implementations specified for speculative decoding 0.08.367.860 I slot load_model: id 0 | task -1 | new slot, n_ctx = 262144 0.08.368.336 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |

256k ctx len을 4이서 나눠서 64k씩
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 4 0.08.236.351 W common_speculative_init: no implementations specified for speculative decoding 0.08.236.356 I slot load_model: id 0 | task -1 | new slot, n_ctx = 65536 0.08.236.370 I slot load_model: id 1 | task -1 | new slot, n_ctx = 65536 0.08.236.372 I slot load_model: id 2 | task -1 | new slot, n_ctx = 65536 0.08.236.374 I slot load_model: id 3 | task -1 | new slot, n_ctx = 65536 0.08.236.795 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |
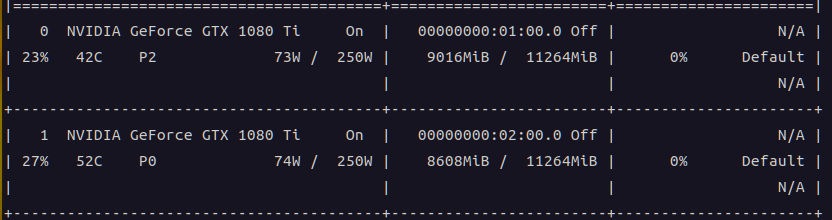
그걸 다시 ctx len을 4배 늘려서 하니 인당 256k 씩 할당 완료
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 4 -c 1048576 0.41.525.240 W common_speculative_init: no implementations specified for speculative decoding 0.41.525.241 I slot load_model: id 0 | task -1 | new slot, n_ctx = 262144 0.41.525.247 I slot load_model: id 1 | task -1 | new slot, n_ctx = 262144 0.41.525.247 I slot load_model: id 2 | task -1 | new slot, n_ctx = 262144 0.41.525.248 I slot load_model: id 3 | task -1 | new slot, n_ctx = 262144 0.41.525.326 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |
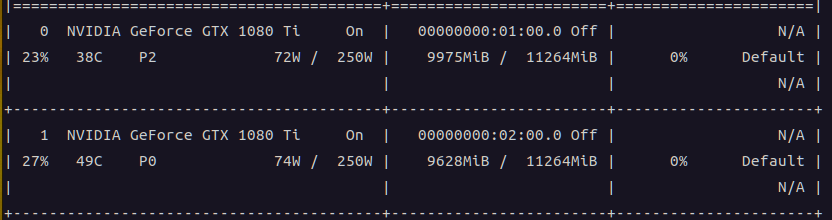
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 8 0.08.144.543 W common_speculative_init: no implementations specified for speculative decoding 0.08.144.547 I slot load_model: id 0 | task -1 | new slot, n_ctx = 32768 0.08.144.563 I slot load_model: id 1 | task -1 | new slot, n_ctx = 32768 0.08.144.565 I slot load_model: id 2 | task -1 | new slot, n_ctx = 32768 0.08.144.566 I slot load_model: id 3 | task -1 | new slot, n_ctx = 32768 0.08.144.568 I slot load_model: id 4 | task -1 | new slot, n_ctx = 32768 0.08.144.569 I slot load_model: id 5 | task -1 | new slot, n_ctx = 32768 0.08.144.571 I slot load_model: id 6 | task -1 | new slot, n_ctx = 32768 0.08.144.573 I slot load_model: id 7 | task -1 | new slot, n_ctx = 32768 0.08.145.051 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |
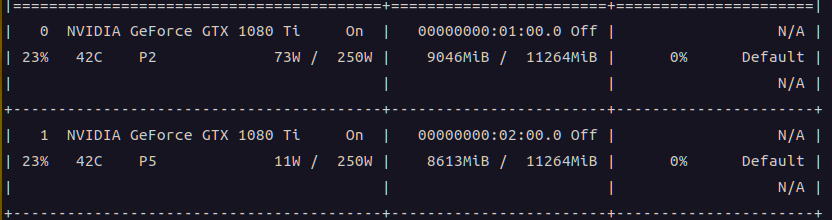
32*7168 =229376 < 262144
음? 최대 컨텍스트 보다 적어졌다?
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 32 0.20.248.497 W common_speculative_init: no implementations specified for speculative decoding 0.20.248.508 I slot load_model: id 0 | task -1 | new slot, n_ctx = 7168 0.20.248.523 I slot load_model: id 1 | task -1 | new slot, n_ctx = 7168 0.20.248.525 I slot load_model: id 2 | task -1 | new slot, n_ctx = 7168 0.20.248.527 I slot load_model: id 3 | task -1 | new slot, n_ctx = 7168 0.20.248.528 I slot load_model: id 4 | task -1 | new slot, n_ctx = 7168 0.20.248.530 I slot load_model: id 5 | task -1 | new slot, n_ctx = 7168 0.20.248.532 I slot load_model: id 6 | task -1 | new slot, n_ctx = 7168 0.20.248.533 I slot load_model: id 7 | task -1 | new slot, n_ctx = 7168 0.20.248.535 I slot load_model: id 8 | task -1 | new slot, n_ctx = 7168 0.20.248.536 I slot load_model: id 9 | task -1 | new slot, n_ctx = 7168 0.20.248.538 I slot load_model: id 10 | task -1 | new slot, n_ctx = 7168 0.20.248.539 I slot load_model: id 11 | task -1 | new slot, n_ctx = 7168 0.20.248.540 I slot load_model: id 12 | task -1 | new slot, n_ctx = 7168 0.20.248.542 I slot load_model: id 13 | task -1 | new slot, n_ctx = 7168 0.20.248.543 I slot load_model: id 14 | task -1 | new slot, n_ctx = 7168 0.20.248.545 I slot load_model: id 15 | task -1 | new slot, n_ctx = 7168 0.20.248.546 I slot load_model: id 16 | task -1 | new slot, n_ctx = 7168 0.20.248.548 I slot load_model: id 17 | task -1 | new slot, n_ctx = 7168 0.20.248.549 I slot load_model: id 18 | task -1 | new slot, n_ctx = 7168 0.20.248.551 I slot load_model: id 19 | task -1 | new slot, n_ctx = 7168 0.20.248.552 I slot load_model: id 20 | task -1 | new slot, n_ctx = 7168 0.20.248.553 I slot load_model: id 21 | task -1 | new slot, n_ctx = 7168 0.20.248.555 I slot load_model: id 22 | task -1 | new slot, n_ctx = 7168 0.20.248.556 I slot load_model: id 23 | task -1 | new slot, n_ctx = 7168 0.20.248.558 I slot load_model: id 24 | task -1 | new slot, n_ctx = 7168 0.20.248.559 I slot load_model: id 25 | task -1 | new slot, n_ctx = 7168 0.20.248.561 I slot load_model: id 26 | task -1 | new slot, n_ctx = 7168 0.20.248.562 I slot load_model: id 27 | task -1 | new slot, n_ctx = 7168 0.20.248.563 I slot load_model: id 28 | task -1 | new slot, n_ctx = 7168 0.20.248.565 I slot load_model: id 29 | task -1 | new slot, n_ctx = 7168 0.20.248.566 I slot load_model: id 30 | task -1 | new slot, n_ctx = 7168 0.20.248.568 I slot load_model: id 31 | task -1 | new slot, n_ctx = 7168 0.20.248.958 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |
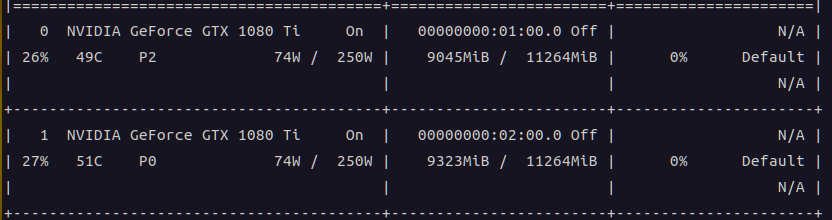
-c로 개인당 컨텍스트 늘리는데 예상한것 보다는 적어도 아까보단 늘어났다.
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 32 -c 1048576 0.29.550.307 W common_speculative_init: no implementations specified for speculative decoding 0.29.550.308 I slot load_model: id 0 | task -1 | new slot, n_ctx = 32768 0.29.550.314 I slot load_model: id 1 | task -1 | new slot, n_ctx = 32768 0.29.550.315 I slot load_model: id 2 | task -1 | new slot, n_ctx = 32768 0.29.550.315 I slot load_model: id 3 | task -1 | new slot, n_ctx = 32768 0.29.550.315 I slot load_model: id 4 | task -1 | new slot, n_ctx = 32768 0.29.550.316 I slot load_model: id 5 | task -1 | new slot, n_ctx = 32768 0.29.550.316 I slot load_model: id 6 | task -1 | new slot, n_ctx = 32768 0.29.550.316 I slot load_model: id 7 | task -1 | new slot, n_ctx = 32768 0.29.550.316 I slot load_model: id 8 | task -1 | new slot, n_ctx = 32768 0.29.550.317 I slot load_model: id 9 | task -1 | new slot, n_ctx = 32768 0.29.550.317 I slot load_model: id 10 | task -1 | new slot, n_ctx = 32768 0.29.550.317 I slot load_model: id 11 | task -1 | new slot, n_ctx = 32768 0.29.550.318 I slot load_model: id 12 | task -1 | new slot, n_ctx = 32768 0.29.550.318 I slot load_model: id 13 | task -1 | new slot, n_ctx = 32768 0.29.550.318 I slot load_model: id 14 | task -1 | new slot, n_ctx = 32768 0.29.550.318 I slot load_model: id 15 | task -1 | new slot, n_ctx = 32768 0.29.550.319 I slot load_model: id 16 | task -1 | new slot, n_ctx = 32768 0.29.550.319 I slot load_model: id 17 | task -1 | new slot, n_ctx = 32768 0.29.550.319 I slot load_model: id 18 | task -1 | new slot, n_ctx = 32768 0.29.550.320 I slot load_model: id 19 | task -1 | new slot, n_ctx = 32768 0.29.550.320 I slot load_model: id 20 | task -1 | new slot, n_ctx = 32768 0.29.550.320 I slot load_model: id 21 | task -1 | new slot, n_ctx = 32768 0.29.550.321 I slot load_model: id 22 | task -1 | new slot, n_ctx = 32768 0.29.550.321 I slot load_model: id 23 | task -1 | new slot, n_ctx = 32768 0.29.550.321 I slot load_model: id 24 | task -1 | new slot, n_ctx = 32768 0.29.550.321 I slot load_model: id 25 | task -1 | new slot, n_ctx = 32768 0.29.550.322 I slot load_model: id 26 | task -1 | new slot, n_ctx = 32768 0.29.550.322 I slot load_model: id 27 | task -1 | new slot, n_ctx = 32768 0.29.550.322 I slot load_model: id 28 | task -1 | new slot, n_ctx = 32768 0.29.550.323 I slot load_model: id 29 | task -1 | new slot, n_ctx = 32768 0.29.550.323 I slot load_model: id 30 | task -1 | new slot, n_ctx = 32768 0.29.550.323 I slot load_model: id 31 | task -1 | new slot, n_ctx = 32768 0.29.550.438 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |

여기 부터는 아마도 vram 초과해서 cpu ram으로 offloading된 듯
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 64 0.21.952.543 W common_speculative_init: no implementations specified for speculative decoding 0.21.952.553 I slot load_model: id 0 | task -1 | new slot, n_ctx = 256 0.21.952.568 I slot load_model: id 1 | task -1 | new slot, n_ctx = 256 0.21.952.570 I slot load_model: id 2 | task -1 | new slot, n_ctx = 256 0.21.952.571 I slot load_model: id 3 | task -1 | new slot, n_ctx = 256 0.21.952.573 I slot load_model: id 4 | task -1 | new slot, n_ctx = 256 0.21.952.574 I slot load_model: id 5 | task -1 | new slot, n_ctx = 256 0.21.952.576 I slot load_model: id 6 | task -1 | new slot, n_ctx = 256 0.21.952.578 I slot load_model: id 7 | task -1 | new slot, n_ctx = 256 0.21.952.579 I slot load_model: id 8 | task -1 | new slot, n_ctx = 256 0.21.952.581 I slot load_model: id 9 | task -1 | new slot, n_ctx = 256 0.21.952.582 I slot load_model: id 10 | task -1 | new slot, n_ctx = 256 0.21.952.584 I slot load_model: id 11 | task -1 | new slot, n_ctx = 256 0.21.952.585 I slot load_model: id 12 | task -1 | new slot, n_ctx = 256 0.21.952.587 I slot load_model: id 13 | task -1 | new slot, n_ctx = 256 0.21.952.589 I slot load_model: id 14 | task -1 | new slot, n_ctx = 256 0.21.952.590 I slot load_model: id 15 | task -1 | new slot, n_ctx = 256 0.21.952.591 I slot load_model: id 16 | task -1 | new slot, n_ctx = 256 0.21.952.593 I slot load_model: id 17 | task -1 | new slot, n_ctx = 256 0.21.952.595 I slot load_model: id 18 | task -1 | new slot, n_ctx = 256 0.21.952.596 I slot load_model: id 19 | task -1 | new slot, n_ctx = 256 0.21.952.597 I slot load_model: id 20 | task -1 | new slot, n_ctx = 256 0.21.952.599 I slot load_model: id 21 | task -1 | new slot, n_ctx = 256 0.21.952.600 I slot load_model: id 22 | task -1 | new slot, n_ctx = 256 0.21.952.602 I slot load_model: id 23 | task -1 | new slot, n_ctx = 256 0.21.952.603 I slot load_model: id 24 | task -1 | new slot, n_ctx = 256 0.21.952.605 I slot load_model: id 25 | task -1 | new slot, n_ctx = 256 0.21.952.611 I slot load_model: id 26 | task -1 | new slot, n_ctx = 256 0.21.952.616 I slot load_model: id 27 | task -1 | new slot, n_ctx = 256 0.21.952.617 I slot load_model: id 28 | task -1 | new slot, n_ctx = 256 0.21.952.619 I slot load_model: id 29 | task -1 | new slot, n_ctx = 256 0.21.952.620 I slot load_model: id 30 | task -1 | new slot, n_ctx = 256 0.21.952.622 I slot load_model: id 31 | task -1 | new slot, n_ctx = 256 0.21.952.623 I slot load_model: id 32 | task -1 | new slot, n_ctx = 256 0.21.952.625 I slot load_model: id 33 | task -1 | new slot, n_ctx = 256 0.21.952.626 I slot load_model: id 34 | task -1 | new slot, n_ctx = 256 0.21.952.627 I slot load_model: id 35 | task -1 | new slot, n_ctx = 256 0.21.952.629 I slot load_model: id 36 | task -1 | new slot, n_ctx = 256 0.21.952.630 I slot load_model: id 37 | task -1 | new slot, n_ctx = 256 0.21.952.632 I slot load_model: id 38 | task -1 | new slot, n_ctx = 256 0.21.952.633 I slot load_model: id 39 | task -1 | new slot, n_ctx = 256 0.21.952.635 I slot load_model: id 40 | task -1 | new slot, n_ctx = 256 0.21.952.636 I slot load_model: id 41 | task -1 | new slot, n_ctx = 256 0.21.952.638 I slot load_model: id 42 | task -1 | new slot, n_ctx = 256 0.21.952.639 I slot load_model: id 43 | task -1 | new slot, n_ctx = 256 0.21.952.640 I slot load_model: id 44 | task -1 | new slot, n_ctx = 256 0.21.952.642 I slot load_model: id 45 | task -1 | new slot, n_ctx = 256 0.21.952.643 I slot load_model: id 46 | task -1 | new slot, n_ctx = 256 0.21.952.645 I slot load_model: id 47 | task -1 | new slot, n_ctx = 256 0.21.952.646 I slot load_model: id 48 | task -1 | new slot, n_ctx = 256 0.21.952.648 I slot load_model: id 49 | task -1 | new slot, n_ctx = 256 0.21.952.649 I slot load_model: id 50 | task -1 | new slot, n_ctx = 256 0.21.952.650 I slot load_model: id 51 | task -1 | new slot, n_ctx = 256 0.21.952.652 I slot load_model: id 52 | task -1 | new slot, n_ctx = 256 0.21.952.653 I slot load_model: id 53 | task -1 | new slot, n_ctx = 256 0.21.952.655 I slot load_model: id 54 | task -1 | new slot, n_ctx = 256 0.21.952.656 I slot load_model: id 55 | task -1 | new slot, n_ctx = 256 0.21.952.658 I slot load_model: id 56 | task -1 | new slot, n_ctx = 256 0.21.952.659 I slot load_model: id 57 | task -1 | new slot, n_ctx = 256 0.21.952.661 I slot load_model: id 58 | task -1 | new slot, n_ctx = 256 0.21.952.662 I slot load_model: id 59 | task -1 | new slot, n_ctx = 256 0.21.952.663 I slot load_model: id 60 | task -1 | new slot, n_ctx = 256 0.21.952.665 I slot load_model: id 61 | task -1 | new slot, n_ctx = 256 0.21.952.666 I slot load_model: id 62 | task -1 | new slot, n_ctx = 256 0.21.952.668 I slot load_model: id 63 | task -1 | new slot, n_ctx = 256 0.21.953.026 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |
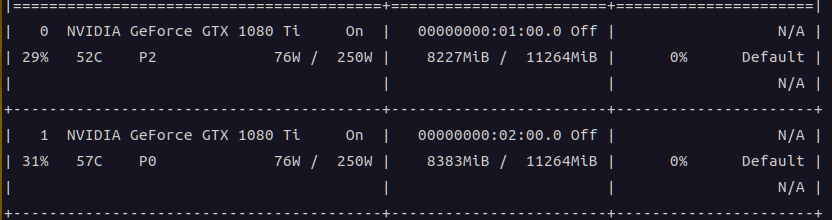
| $ ./llama-b9692/llama-server -m model/qwen3.6_35B/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf -sm layer --host 0.0.0.0 -np 128 0.43.993.646 W common_speculative_init: no implementations specified for speculative decoding 0.43.993.651 I slot load_model: id 0 | task -1 | new slot, n_ctx = 256 0.43.993.666 I slot load_model: id 1 | task -1 | new slot, n_ctx = 256 0.43.993.669 I slot load_model: id 2 | task -1 | new slot, n_ctx = 256 0.43.993.670 I slot load_model: id 3 | task -1 | new slot, n_ctx = 256 0.43.993.672 I slot load_model: id 4 | task -1 | new slot, n_ctx = 256 0.43.993.673 I slot load_model: id 5 | task -1 | new slot, n_ctx = 256 0.43.993.675 I slot load_model: id 6 | task -1 | new slot, n_ctx = 256 0.43.993.676 I slot load_model: id 7 | task -1 | new slot, n_ctx = 256 0.43.993.678 I slot load_model: id 8 | task -1 | new slot, n_ctx = 256 0.43.993.679 I slot load_model: id 9 | task -1 | new slot, n_ctx = 256 0.43.993.681 I slot load_model: id 10 | task -1 | new slot, n_ctx = 256 0.43.993.682 I slot load_model: id 11 | task -1 | new slot, n_ctx = 256 0.43.993.684 I slot load_model: id 12 | task -1 | new slot, n_ctx = 256 0.43.993.685 I slot load_model: id 13 | task -1 | new slot, n_ctx = 256 0.43.993.687 I slot load_model: id 14 | task -1 | new slot, n_ctx = 256 0.43.993.688 I slot load_model: id 15 | task -1 | new slot, n_ctx = 256 0.43.993.689 I slot load_model: id 16 | task -1 | new slot, n_ctx = 256 0.43.993.691 I slot load_model: id 17 | task -1 | new slot, n_ctx = 256 0.43.993.692 I slot load_model: id 18 | task -1 | new slot, n_ctx = 256 0.43.993.694 I slot load_model: id 19 | task -1 | new slot, n_ctx = 256 0.43.993.695 I slot load_model: id 20 | task -1 | new slot, n_ctx = 256 0.43.993.697 I slot load_model: id 21 | task -1 | new slot, n_ctx = 256 0.43.993.698 I slot load_model: id 22 | task -1 | new slot, n_ctx = 256 0.43.993.700 I slot load_model: id 23 | task -1 | new slot, n_ctx = 256 0.43.993.701 I slot load_model: id 24 | task -1 | new slot, n_ctx = 256 0.43.993.703 I slot load_model: id 25 | task -1 | new slot, n_ctx = 256 0.43.993.704 I slot load_model: id 26 | task -1 | new slot, n_ctx = 256 0.43.993.705 I slot load_model: id 27 | task -1 | new slot, n_ctx = 256 0.43.993.707 I slot load_model: id 28 | task -1 | new slot, n_ctx = 256 0.43.993.708 I slot load_model: id 29 | task -1 | new slot, n_ctx = 256 0.43.993.710 I slot load_model: id 30 | task -1 | new slot, n_ctx = 256 0.43.993.711 I slot load_model: id 31 | task -1 | new slot, n_ctx = 256 0.43.993.714 I slot load_model: id 32 | task -1 | new slot, n_ctx = 256 0.43.993.715 I slot load_model: id 33 | task -1 | new slot, n_ctx = 256 0.43.993.717 I slot load_model: id 34 | task -1 | new slot, n_ctx = 256 0.43.993.719 I slot load_model: id 35 | task -1 | new slot, n_ctx = 256 0.43.993.720 I slot load_model: id 36 | task -1 | new slot, n_ctx = 256 0.43.993.722 I slot load_model: id 37 | task -1 | new slot, n_ctx = 256 0.43.993.723 I slot load_model: id 38 | task -1 | new slot, n_ctx = 256 0.43.993.724 I slot load_model: id 39 | task -1 | new slot, n_ctx = 256 0.43.993.726 I slot load_model: id 40 | task -1 | new slot, n_ctx = 256 0.43.993.727 I slot load_model: id 41 | task -1 | new slot, n_ctx = 256 0.43.993.729 I slot load_model: id 42 | task -1 | new slot, n_ctx = 256 0.43.993.730 I slot load_model: id 43 | task -1 | new slot, n_ctx = 256 0.43.993.731 I slot load_model: id 44 | task -1 | new slot, n_ctx = 256 0.43.993.733 I slot load_model: id 45 | task -1 | new slot, n_ctx = 256 0.43.993.734 I slot load_model: id 46 | task -1 | new slot, n_ctx = 256 0.43.993.736 I slot load_model: id 47 | task -1 | new slot, n_ctx = 256 0.43.993.737 I slot load_model: id 48 | task -1 | new slot, n_ctx = 256 0.43.993.739 I slot load_model: id 49 | task -1 | new slot, n_ctx = 256 0.43.993.740 I slot load_model: id 50 | task -1 | new slot, n_ctx = 256 0.43.993.742 I slot load_model: id 51 | task -1 | new slot, n_ctx = 256 0.43.993.743 I slot load_model: id 52 | task -1 | new slot, n_ctx = 256 0.43.993.745 I slot load_model: id 53 | task -1 | new slot, n_ctx = 256 0.43.993.746 I slot load_model: id 54 | task -1 | new slot, n_ctx = 256 0.43.993.748 I slot load_model: id 55 | task -1 | new slot, n_ctx = 256 0.43.993.749 I slot load_model: id 56 | task -1 | new slot, n_ctx = 256 0.43.993.750 I slot load_model: id 57 | task -1 | new slot, n_ctx = 256 0.43.993.752 I slot load_model: id 58 | task -1 | new slot, n_ctx = 256 0.43.993.753 I slot load_model: id 59 | task -1 | new slot, n_ctx = 256 0.43.993.755 I slot load_model: id 60 | task -1 | new slot, n_ctx = 256 0.43.993.756 I slot load_model: id 61 | task -1 | new slot, n_ctx = 256 0.43.993.758 I slot load_model: id 62 | task -1 | new slot, n_ctx = 256 0.43.993.759 I slot load_model: id 63 | task -1 | new slot, n_ctx = 256 0.43.993.761 I slot load_model: id 64 | task -1 | new slot, n_ctx = 256 0.43.993.762 I slot load_model: id 65 | task -1 | new slot, n_ctx = 256 0.43.993.763 I slot load_model: id 66 | task -1 | new slot, n_ctx = 256 0.43.993.765 I slot load_model: id 67 | task -1 | new slot, n_ctx = 256 0.43.993.766 I slot load_model: id 68 | task -1 | new slot, n_ctx = 256 0.43.993.768 I slot load_model: id 69 | task -1 | new slot, n_ctx = 256 0.43.993.769 I slot load_model: id 70 | task -1 | new slot, n_ctx = 256 0.43.993.771 I slot load_model: id 71 | task -1 | new slot, n_ctx = 256 0.43.993.772 I slot load_model: id 72 | task -1 | new slot, n_ctx = 256 0.43.993.774 I slot load_model: id 73 | task -1 | new slot, n_ctx = 256 0.43.993.775 I slot load_model: id 74 | task -1 | new slot, n_ctx = 256 0.43.993.776 I slot load_model: id 75 | task -1 | new slot, n_ctx = 256 0.43.993.778 I slot load_model: id 76 | task -1 | new slot, n_ctx = 256 0.43.993.779 I slot load_model: id 77 | task -1 | new slot, n_ctx = 256 0.43.993.781 I slot load_model: id 78 | task -1 | new slot, n_ctx = 256 0.43.993.782 I slot load_model: id 79 | task -1 | new slot, n_ctx = 256 0.43.993.784 I slot load_model: id 80 | task -1 | new slot, n_ctx = 256 0.43.993.785 I slot load_model: id 81 | task -1 | new slot, n_ctx = 256 0.43.993.787 I slot load_model: id 82 | task -1 | new slot, n_ctx = 256 0.43.993.788 I slot load_model: id 83 | task -1 | new slot, n_ctx = 256 0.43.993.789 I slot load_model: id 84 | task -1 | new slot, n_ctx = 256 0.43.993.791 I slot load_model: id 85 | task -1 | new slot, n_ctx = 256 0.43.993.792 I slot load_model: id 86 | task -1 | new slot, n_ctx = 256 0.43.993.794 I slot load_model: id 87 | task -1 | new slot, n_ctx = 256 0.43.993.795 I slot load_model: id 88 | task -1 | new slot, n_ctx = 256 0.43.993.797 I slot load_model: id 89 | task -1 | new slot, n_ctx = 256 0.43.993.798 I slot load_model: id 90 | task -1 | new slot, n_ctx = 256 0.43.993.800 I slot load_model: id 91 | task -1 | new slot, n_ctx = 256 0.43.993.801 I slot load_model: id 92 | task -1 | new slot, n_ctx = 256 0.43.993.802 I slot load_model: id 93 | task -1 | new slot, n_ctx = 256 0.43.993.804 I slot load_model: id 94 | task -1 | new slot, n_ctx = 256 0.43.993.805 I slot load_model: id 95 | task -1 | new slot, n_ctx = 256 0.43.993.807 I slot load_model: id 96 | task -1 | new slot, n_ctx = 256 0.43.993.808 I slot load_model: id 97 | task -1 | new slot, n_ctx = 256 0.43.993.810 I slot load_model: id 98 | task -1 | new slot, n_ctx = 256 0.43.993.811 I slot load_model: id 99 | task -1 | new slot, n_ctx = 256 0.43.993.813 I slot load_model: id 100 | task -1 | new slot, n_ctx = 256 0.43.993.814 I slot load_model: id 101 | task -1 | new slot, n_ctx = 256 0.43.993.816 I slot load_model: id 102 | task -1 | new slot, n_ctx = 256 0.43.993.817 I slot load_model: id 103 | task -1 | new slot, n_ctx = 256 0.43.993.819 I slot load_model: id 104 | task -1 | new slot, n_ctx = 256 0.43.993.820 I slot load_model: id 105 | task -1 | new slot, n_ctx = 256 0.43.993.822 I slot load_model: id 106 | task -1 | new slot, n_ctx = 256 0.43.993.823 I slot load_model: id 107 | task -1 | new slot, n_ctx = 256 0.43.993.824 I slot load_model: id 108 | task -1 | new slot, n_ctx = 256 0.43.993.826 I slot load_model: id 109 | task -1 | new slot, n_ctx = 256 0.43.993.827 I slot load_model: id 110 | task -1 | new slot, n_ctx = 256 0.43.993.829 I slot load_model: id 111 | task -1 | new slot, n_ctx = 256 0.43.993.830 I slot load_model: id 112 | task -1 | new slot, n_ctx = 256 0.43.993.832 I slot load_model: id 113 | task -1 | new slot, n_ctx = 256 0.43.993.833 I slot load_model: id 114 | task -1 | new slot, n_ctx = 256 0.43.993.835 I slot load_model: id 115 | task -1 | new slot, n_ctx = 256 0.43.993.836 I slot load_model: id 116 | task -1 | new slot, n_ctx = 256 0.43.993.838 I slot load_model: id 117 | task -1 | new slot, n_ctx = 256 0.43.993.839 I slot load_model: id 118 | task -1 | new slot, n_ctx = 256 0.43.993.840 I slot load_model: id 119 | task -1 | new slot, n_ctx = 256 0.43.993.842 I slot load_model: id 120 | task -1 | new slot, n_ctx = 256 0.43.993.843 I slot load_model: id 121 | task -1 | new slot, n_ctx = 256 0.43.993.845 I slot load_model: id 122 | task -1 | new slot, n_ctx = 256 0.43.993.846 I slot load_model: id 123 | task -1 | new slot, n_ctx = 256 0.43.993.848 I slot load_model: id 124 | task -1 | new slot, n_ctx = 256 0.43.993.849 I slot load_model: id 125 | task -1 | new slot, n_ctx = 256 0.43.993.851 I slot load_model: id 126 | task -1 | new slot, n_ctx = 256 0.43.993.852 I slot load_model: id 127 | task -1 | new slot, n_ctx = 256 0.43.994.142 I srv load_model: prompt cache is enabled, size limit: 8192 MiB |

'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| llama.cpp / 1080 ti 11GB * 2/ gemma4-31B (0) | 2026.07.30 |
|---|---|
| llama.cpp / jetson thor gemma-4-31B mmproj F16, BF16 (0) | 2026.07.30 |
| vllm concurrent test/benchmark (0) | 2026.07.29 |
| vllm parallelism - concurrency (0) | 2026.07.28 |
| nvidia thor - llama.cpp LLM (0) | 2026.07.24 |
멀루 인식되나 궁금해서 한 번 꽂아봄
| [418902.776178] usb 1-1: new full-speed USB device number 14 using xhci_hcd [418902.904536] usb 1-1: not running at top speed; connect to a high speed hub [418902.906304] usb 1-1: New USB device found, idVendor=001f, idProduct=0b21, bcdDevice= 1.00 [418902.906311] usb 1-1: New USB device strings: Mfr=1, Product=2, SerialNumber=3 [418902.906313] usb 1-1: Product: AB13X USB Audio [418902.906315] usb 1-1: Manufacturer: Generic [418902.906317] usb 1-1: SerialNumber: 20210926172016 [418902.916215] input: Generic AB13X USB Audio as /devices/pci0000:00/0000:00:14.0/usb1/1-1/1-1:1.3/0003:001F:0B21.000C/input/input34 [418902.968313] hid-generic 0003:001F:0B21.000C: input,hidraw5: USB HID v2.01 Device [Generic AB13X USB Audio] on usb-0000:00:14.0-1/input3 |
| $ lsusb -t -v /: Bus 01.Port 1: Dev 1, Class=root_hub, Driver=xhci_hcd/12p, 480M ID 1d6b:0002 Linux Foundation 2.0 root hub |__ Port 1: Dev 14, If 3, Class=Human Interface Device, Driver=usbhid, 12M ID 001f:0b21 |__ Port 1: Dev 14, If 1, Class=Audio, Driver=snd-usb-audio, 12M ID 001f:0b21 |__ Port 1: Dev 14, If 2, Class=Audio, Driver=snd-usb-audio, 12M ID 001f:0b21 |__ Port 1: Dev 14, If 0, Class=Audio, Driver=snd-usb-audio, 12M ID 001f:0b21 |
| $ lsusb -v -d 001f:0b21 Bus 001 Device 014: ID 001f:0b21 Generic AB13X USB Audio Couldn't open device, some information will be missing Device Descriptor: bLength 18 bDescriptorType 1 bcdUSB 2.00 bDeviceClass 0 bDeviceSubClass 0 bDeviceProtocol 0 bMaxPacketSize0 64 idVendor 0x001f idProduct 0x0b21 bcdDevice 1.00 iManufacturer 1 Generic iProduct 2 AB13X USB Audio iSerial 3 20210926172016 bNumConfigurations 1 Configuration Descriptor: bLength 9 bDescriptorType 2 wTotalLength 0x00da bNumInterfaces 4 bConfigurationValue 1 iConfiguration 0 bmAttributes 0x80 (Bus Powered) MaxPower 100mA Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 0 bAlternateSetting 0 bNumEndpoints 0 bInterfaceClass 1 Audio bInterfaceSubClass 1 Control Device bInterfaceProtocol 0 iInterface 0 AudioControl Interface Descriptor: bLength 10 bDescriptorType 36 bDescriptorSubtype 1 (HEADER) bcdADC 1.00 wTotalLength 0x0047 bInCollection 2 baInterfaceNr(0) 1 baInterfaceNr(1) 2 AudioControl Interface Descriptor: bLength 12 bDescriptorType 36 bDescriptorSubtype 2 (INPUT_TERMINAL) bTerminalID 1 wTerminalType 0x0101 USB Streaming bAssocTerminal 0 bNrChannels 2 wChannelConfig 0x0003 Left Front (L) Right Front (R) iChannelNames 0 iTerminal 0 AudioControl Interface Descriptor: bLength 10 bDescriptorType 36 bDescriptorSubtype 6 (FEATURE_UNIT) bUnitID 2 bSourceID 1 bControlSize 1 bmaControls(0) 0x03 Mute Control Volume Control bmaControls(1) 0x00 bmaControls(2) 0x00 iFeature 0 AudioControl Interface Descriptor: bLength 9 bDescriptorType 36 bDescriptorSubtype 3 (OUTPUT_TERMINAL) bTerminalID 3 wTerminalType 0x0301 Speaker bAssocTerminal 0 bSourceID 2 iTerminal 0 AudioControl Interface Descriptor: bLength 12 bDescriptorType 36 bDescriptorSubtype 2 (INPUT_TERMINAL) bTerminalID 4 wTerminalType 0x0201 Microphone bAssocTerminal 0 bNrChannels 1 wChannelConfig 0x0000 iChannelNames 0 iTerminal 0 AudioControl Interface Descriptor: bLength 9 bDescriptorType 36 bDescriptorSubtype 6 (FEATURE_UNIT) bUnitID 5 bSourceID 4 bControlSize 1 bmaControls(0) 0x03 Mute Control Volume Control bmaControls(1) 0x00 iFeature 0 AudioControl Interface Descriptor: bLength 9 bDescriptorType 36 bDescriptorSubtype 3 (OUTPUT_TERMINAL) bTerminalID 6 wTerminalType 0x0101 USB Streaming bAssocTerminal 0 bSourceID 5 iTerminal 0 Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 1 bAlternateSetting 0 bNumEndpoints 0 bInterfaceClass 1 Audio bInterfaceSubClass 2 Streaming bInterfaceProtocol 0 iInterface 0 Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 1 bAlternateSetting 1 bNumEndpoints 1 bInterfaceClass 1 Audio bInterfaceSubClass 2 Streaming bInterfaceProtocol 0 iInterface 0 AudioStreaming Interface Descriptor: bLength 7 bDescriptorType 36 bDescriptorSubtype 1 (AS_GENERAL) bTerminalLink 1 bDelay 1 frames wFormatTag 0x0001 PCM AudioStreaming Interface Descriptor: bLength 11 bDescriptorType 36 bDescriptorSubtype 2 (FORMAT_TYPE) bFormatType 1 (FORMAT_TYPE_I) bNrChannels 2 bSubframeSize 2 bBitResolution 16 bSamFreqType 1 Discrete tSamFreq[ 0] 48000 Endpoint Descriptor: bLength 9 bDescriptorType 5 bEndpointAddress 0x03 EP 3 OUT bmAttributes 9 Transfer Type Isochronous Synch Type Adaptive Usage Type Data wMaxPacketSize 0x0180 1x 384 bytes bInterval 1 bRefresh 0 bSynchAddress 0 AudioStreaming Endpoint Descriptor: bLength 7 bDescriptorType 37 bDescriptorSubtype 1 (EP_GENERAL) bmAttributes 0x01 Sampling Frequency bLockDelayUnits 1 Milliseconds wLockDelay 0x0001 Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 2 bAlternateSetting 0 bNumEndpoints 0 bInterfaceClass 1 Audio bInterfaceSubClass 2 Streaming bInterfaceProtocol 0 iInterface 0 Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 2 bAlternateSetting 1 bNumEndpoints 1 bInterfaceClass 1 Audio bInterfaceSubClass 2 Streaming bInterfaceProtocol 0 iInterface 0 AudioStreaming Interface Descriptor: bLength 7 bDescriptorType 36 bDescriptorSubtype 1 (AS_GENERAL) bTerminalLink 6 bDelay 1 frames wFormatTag 0x0001 PCM AudioStreaming Interface Descriptor: bLength 11 bDescriptorType 36 bDescriptorSubtype 2 (FORMAT_TYPE) bFormatType 1 (FORMAT_TYPE_I) bNrChannels 1 bSubframeSize 2 bBitResolution 16 bSamFreqType 1 Discrete tSamFreq[ 0] 48000 Endpoint Descriptor: bLength 9 bDescriptorType 5 bEndpointAddress 0x83 EP 3 IN bmAttributes 5 Transfer Type Isochronous Synch Type Asynchronous Usage Type Data wMaxPacketSize 0x00d0 1x 208 bytes bInterval 1 bRefresh 0 bSynchAddress 0 AudioStreaming Endpoint Descriptor: bLength 7 bDescriptorType 37 bDescriptorSubtype 1 (EP_GENERAL) bmAttributes 0x01 Sampling Frequency bLockDelayUnits 0 Undefined wLockDelay 0x0000 Interface Descriptor: bLength 9 bDescriptorType 4 bInterfaceNumber 3 bAlternateSetting 0 bNumEndpoints 1 bInterfaceClass 3 Human Interface Device bInterfaceSubClass 0 bInterfaceProtocol 0 iInterface 0 HID Device Descriptor: bLength 9 bDescriptorType 33 bcdHID 2.01 bCountryCode 0 Not supported bNumDescriptors 1 bDescriptorType 34 Report wDescriptorLength 33 Report Descriptors: ** UNAVAILABLE ** Endpoint Descriptor: bLength 7 bDescriptorType 5 bEndpointAddress 0x82 EP 2 IN bmAttributes 3 Transfer Type Interrupt Synch Type None Usage Type Data wMaxPacketSize 0x0010 1x 16 bytes bInterval 1 |
'개소리 왈왈 > 컴퓨터' 카테고리의 다른 글
| 질러? (2) | 2026.08.07 |
|---|---|
| rk-b30 한손 키보드 메뉴얼 획득! (4) | 2026.07.29 |
| 음.. 쓰레기를 샀나? rk-b30 한손 키보드 (2) | 2026.07.26 |
| usb-c 가 있다고 dp alt가 되는건 아니다 (0) | 2026.07.14 |
| 반도체 수급불량이 sd 카드에도.. (0) | 2026.07.08 |
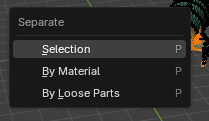
'프로그램 사용 > Blender' 카테고리의 다른 글
| blender 5.x sculpting (0) | 2026.07.29 |
|---|---|
| blender export render/viewport (0) | 2026.07.29 |
| blender 보이지 않는 면까지 선택하기 (0) | 2026.07.29 |
| blnder 포즈 바꾸면서 렌더하기 (0) | 2026.07.28 |
| blender weight paint (0) | 2026.07.28 |
alt-z를 누르면 x-ray 모드가 되는데
그러면 뒤에 면까지 선택된다.
즉, 직관적으로 우리가 선택하는 영역내에 모든 vertex가 선택된다고 해야하나?
기본값인 x-ray off
선택하고 보면 먼가 검은 선이 보인다
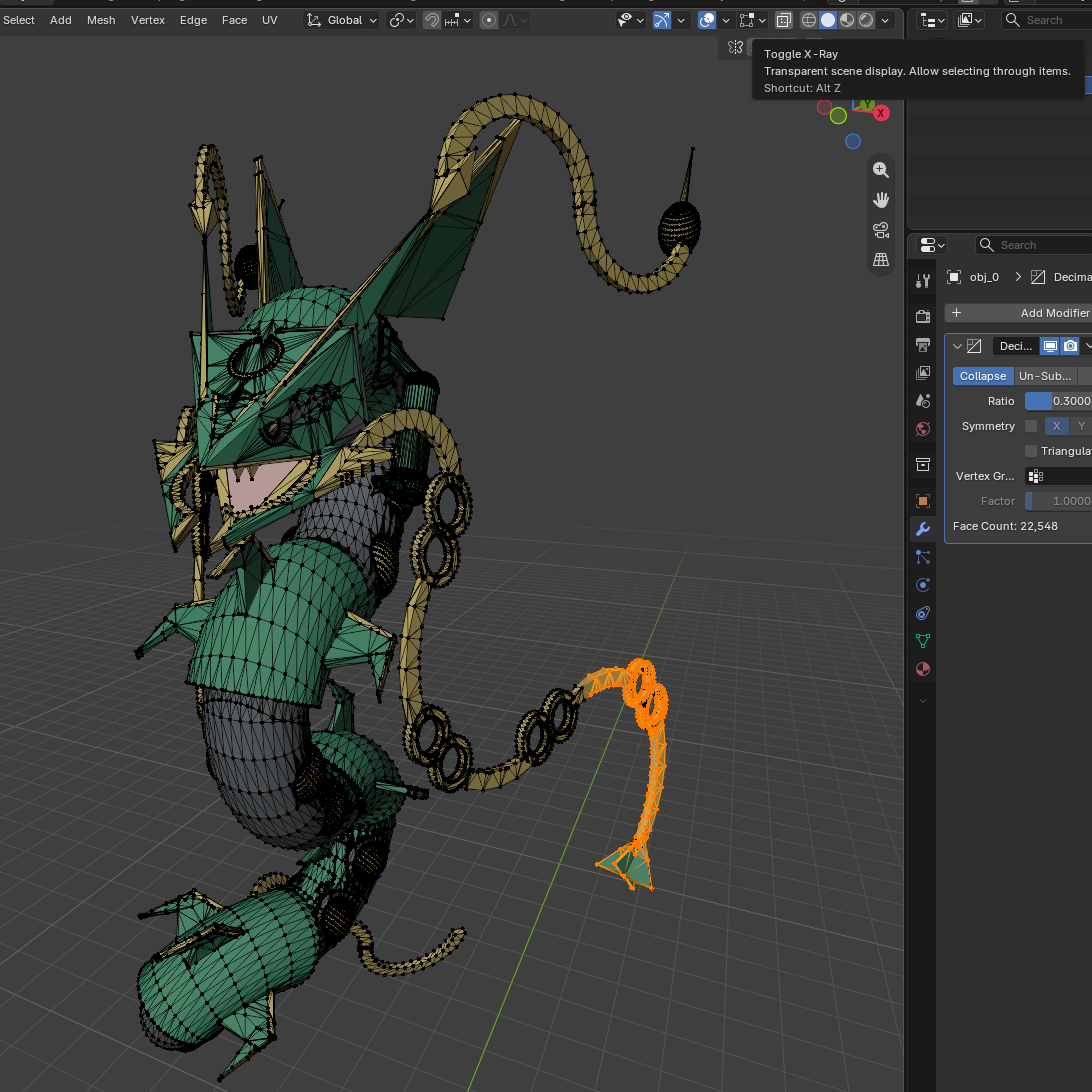

alt-z 눌러서 x-ray 켜고 선택하면 산뜻한 오렌지로 선택되고
돌려보면 뒤에까지 잘되어있다.
[링크 : https://gall.dcinside.com/mgallery/board/view/?id=blender&no=5106]
'프로그램 사용 > Blender' 카테고리의 다른 글
| blender export render/viewport (0) | 2026.07.29 |
|---|---|
| blender 떼어내기, 때우기 (0) | 2026.07.29 |
| blnder 포즈 바꾸면서 렌더하기 (0) | 2026.07.28 |
| blender weight paint (0) | 2026.07.28 |
| blender 먼가 숨기기 단축키 (0) | 2026.07.22 |
vllm 에서 퍼포먼스 테스트 하는 스크립트가 들어깄다고 하는데..
[링크 : https://blog.scatterlab.co.kr/vllm-implementation-details]
[링크 : https://devocean.sk.com/blog/techBoardDetail.do?ID=167138]
[링크 : https://discuss.vllm.ai/t/how-to-benchmark-concurrency/1611]
[링크 : https://www.sktenterprise.com/bizInsight/blogDetail/dev/14546]
'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| llama.cpp / jetson thor gemma-4-31B mmproj F16, BF16 (0) | 2026.07.30 |
|---|---|
| llama.cpp 동시에 응답하게 하기 (0) | 2026.07.29 |
| vllm parallelism - concurrency (0) | 2026.07.28 |
| nvidia thor - llama.cpp LLM (0) | 2026.07.24 |
| llama.cpp for arm64 (0) | 2026.07.20 |
검색하다 보니 이상한(?) C1 C8 이라는 문구 발견, concurrent request 라고 되어있는데
결국은 동시에 응답을 해줄수 있게 돌리냐 아니냐의 차이인듯.
| Modes: C1 (single request) C8 (8 concurrent requests) |
| --max-concurrency¶ Maximum number of concurrent requests. This can be used to help simulate an environment where a higher level component is enforcing a maximum number of concurrent requests. While the --request-rate argument controls the rate at which requests are initiated, this argument will control how many are actually allowed to execute at a time. This means that when used in combination, the actual request rate may be lower than specified with --request-rate, if the server is not processing requests fast enough to keep up |
[링크 : https://docs.vllm.ai/en/stable/cli/bench/serve/#arguments]
| Multi-node multi-GPU using tensor parallel and pipeline parallel inference: if the model is too large for a single node, combine tensor parallelism with pipeline parallelism. Set tensor_parallel_size to the number of GPUs per node and pipeline_parallel_size to the number of nodes. For example, set tensor_parallel_size=8 and pipeline_parallel_size=2 when using 2 nodes with 8 GPUs per node. |
[링크 : https://docs.vllm.ai/en/stable/serving/parallelism_scaling/#single-node-deployment]
'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| llama.cpp 동시에 응답하게 하기 (0) | 2026.07.29 |
|---|---|
| vllm concurrent test/benchmark (0) | 2026.07.29 |
| nvidia thor - llama.cpp LLM (0) | 2026.07.24 |
| llama.cpp for arm64 (0) | 2026.07.20 |
| llama.cpp / qwen3.5 0.8B / 1060, 1080 ti (0) | 2026.07.19 |


