'잡동사니'에 해당되는 글 14653건
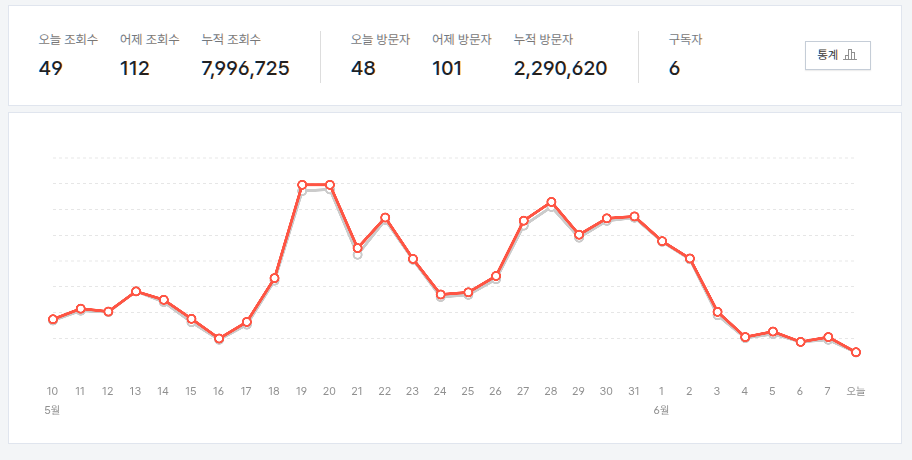
- 2026.06.08 잠깐의 행복했던 방문자 수
- 2026.06.07 doom eternal ancient god part 2 끝!
- 2026.06.06 doom eternal , ancient god part 2 최종장
- 2026.06.05 microhttpd
- 2026.06.05 QGraphicsProxyWidget
- 2026.06.05 sigLIP, CLIP
- 2026.06.05 QT 다국어 언어 설정 전파
- 2026.06.05 QT 자식 위젯으로 생성 / 부모 위젯 연결
- 2026.06.04 doom eternal ancient god part 2
- 2026.06.04 chatML
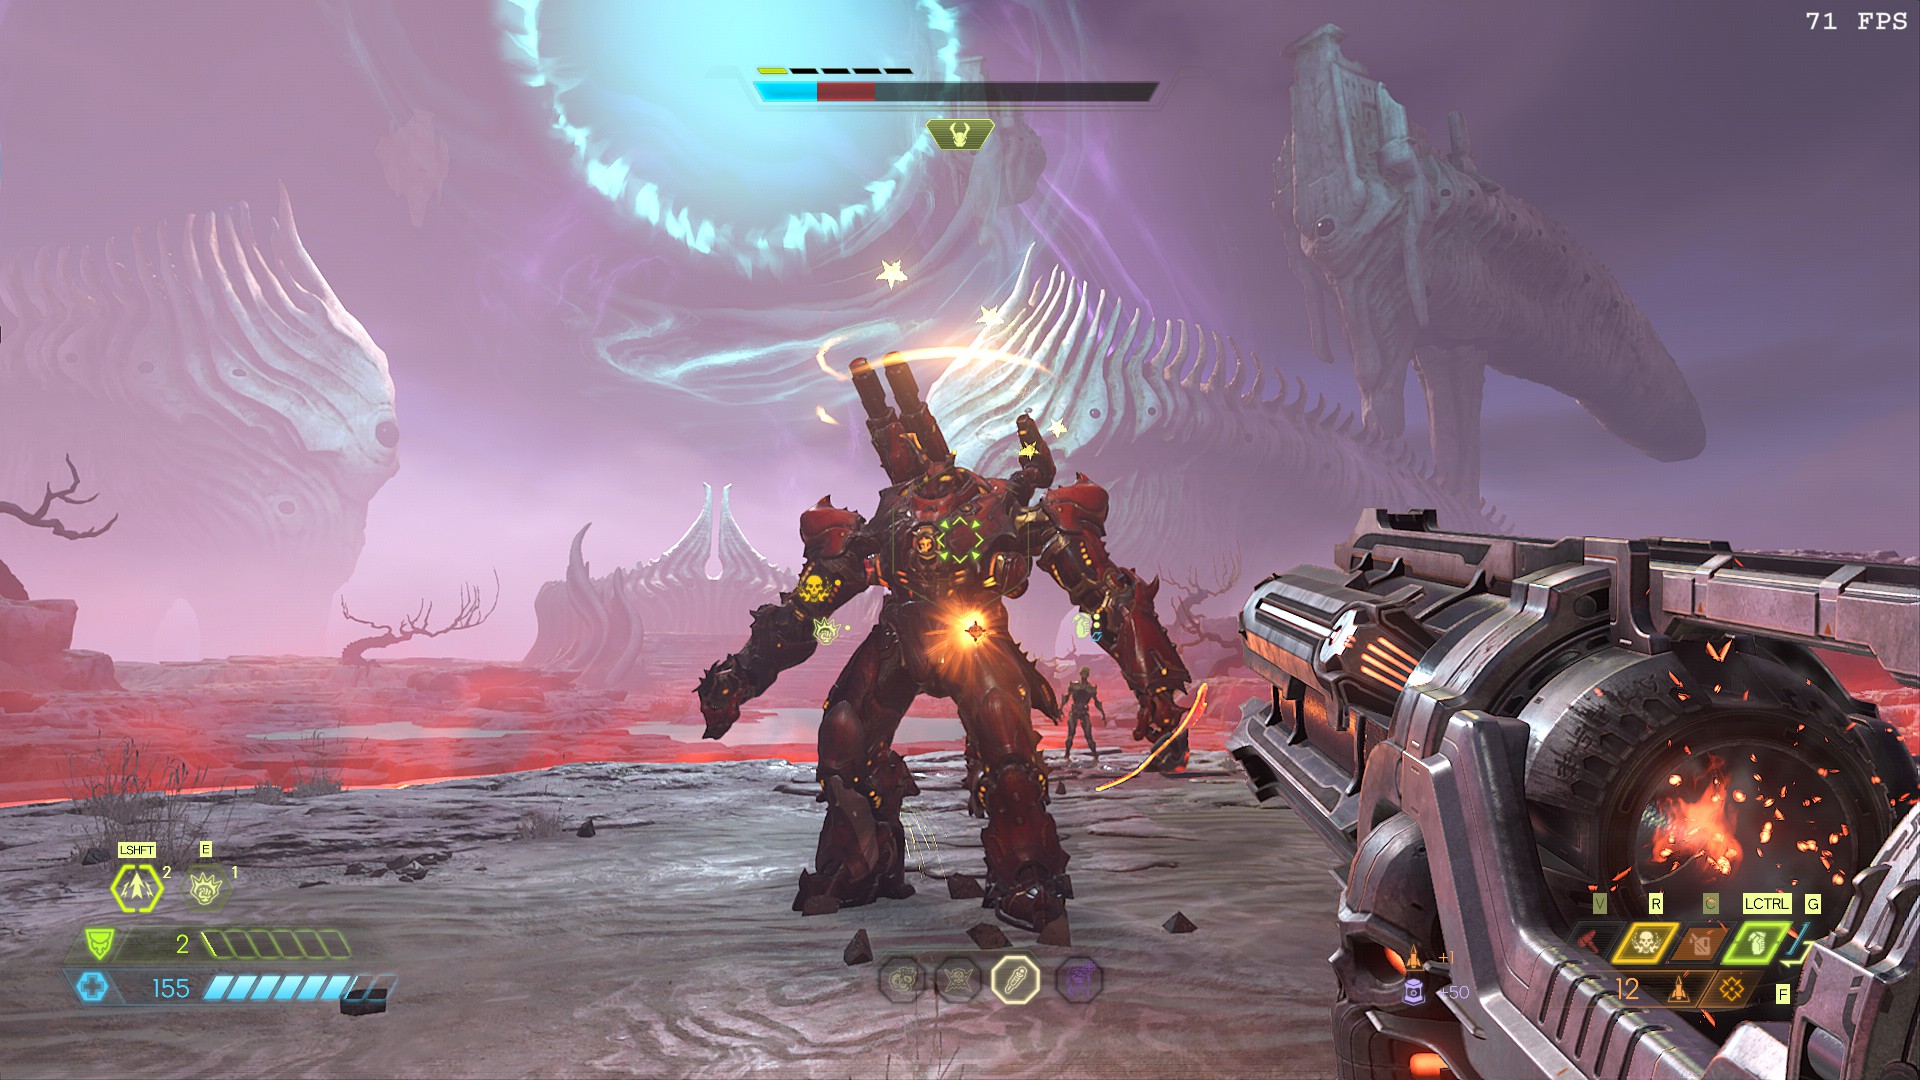
"함께해서 드러웠고 다시는 보지말자" 가 저절로 떠오르는 보스
괜히 암흑공주라고 욕 먹는게 아닌듯
사실상(?) 퀵 스왑 아니면 깰수가 없다.
실수로 한번 몰려서 얻어 맞으면 피 전부 회복해버리는데
퀵 스왑해서 발리스타랑 로켓런처 번갈아 가면서 쏴야지 1/3~1/2 갂을까 말까라 극딜만이 살길 ㅠㅠ

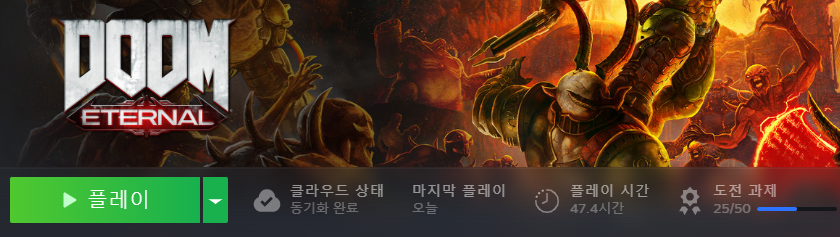
DLC 2개 까지 해서 47.4 시간. 올림해서 48시간 흐음..
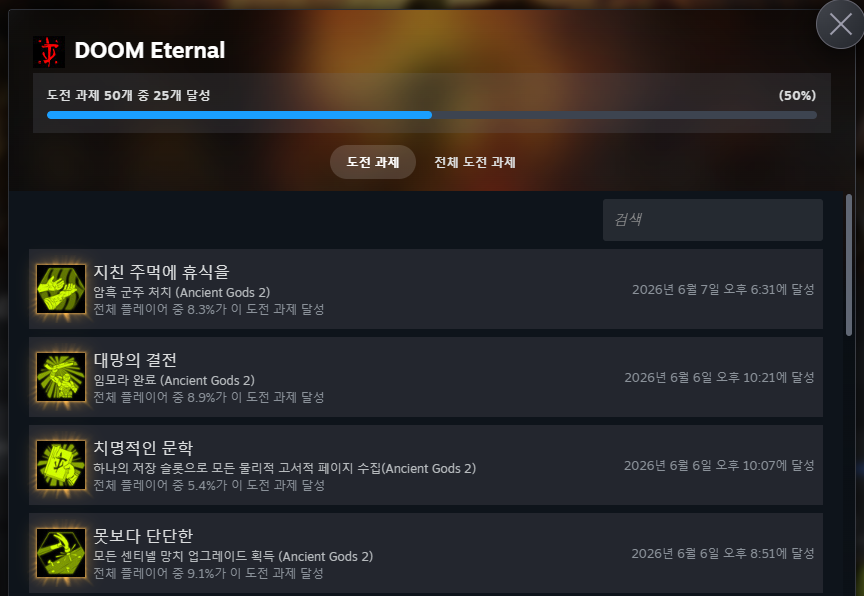
어우 8.3%
'게임 > doom' 카테고리의 다른 글
| doom eternal , ancient god part 2 최종장 (0) | 2026.06.06 |
|---|---|
| doom eternal ancient god part 2 (0) | 2026.06.04 |
| doom eternal / dlc 1편 완료 (0) | 2026.05.28 |
| 둠 이터널 dlc / ancient god part 1 (0) | 2026.05.11 |
| 둠 이터널 노말 난이도 끝 (2) | 2026.01.24 |
어우. 왜 욕먹었은지 알 것 같네
보스가 왜케 쪼잔해
타이밍 이외에 쏘면 지 체력 회복하고
보스급 들 막 소환하지 않나 너무하네
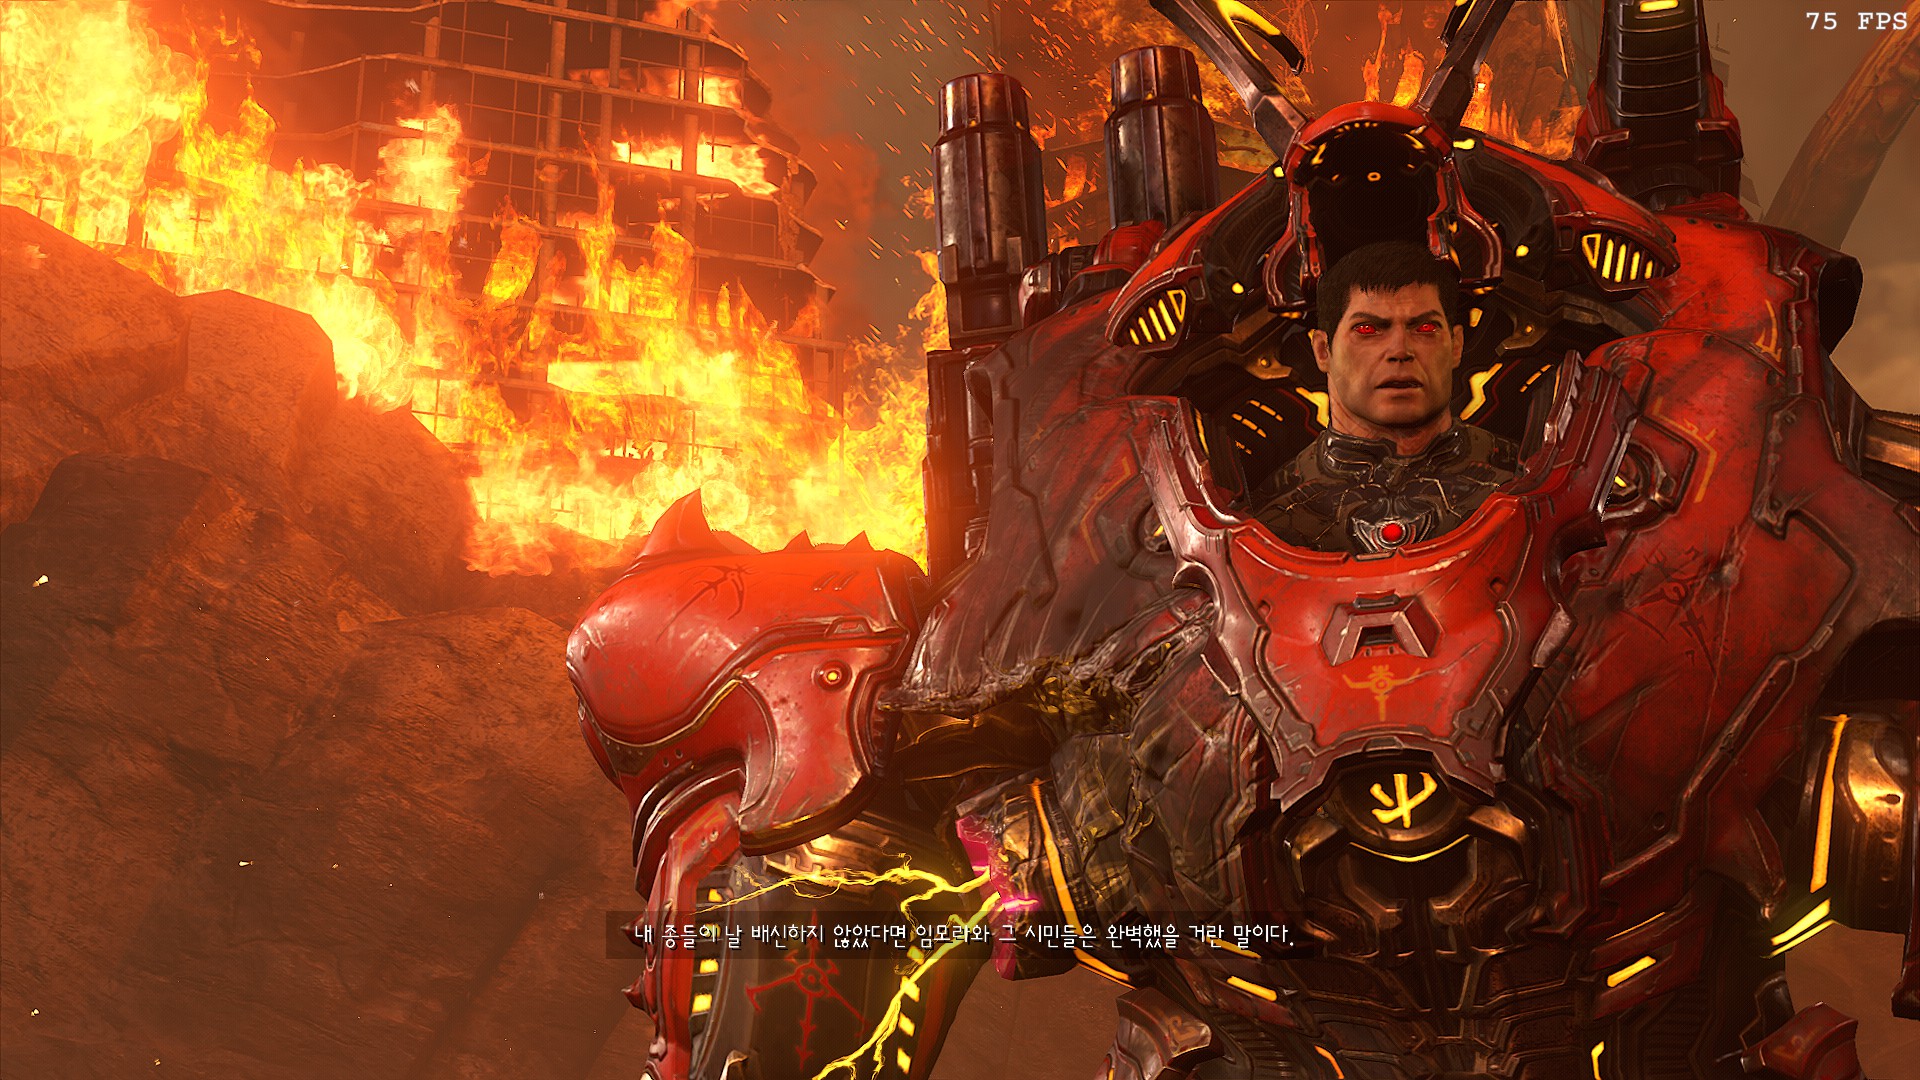
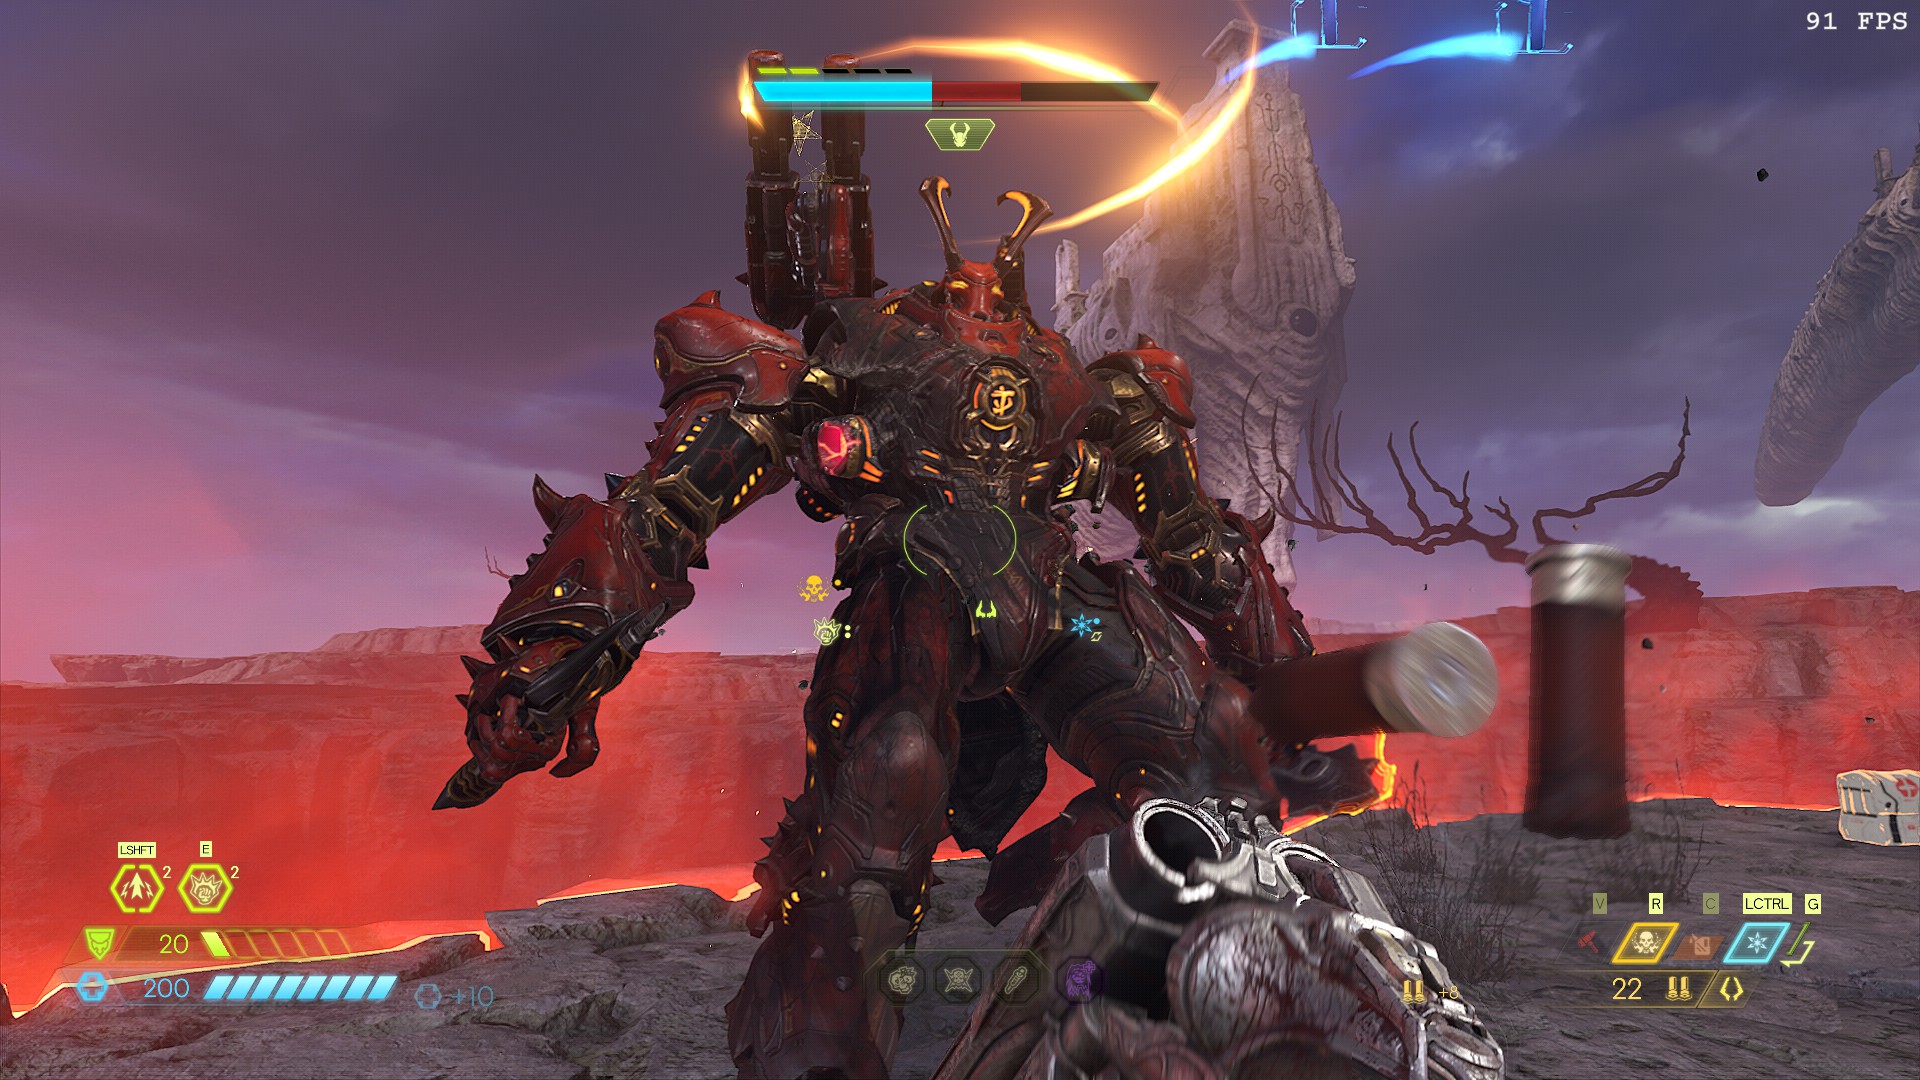
하다하다 빡쳐서 일단 공략보고 고민중
'게임 > doom' 카테고리의 다른 글
| doom eternal ancient god part 2 끝! (0) | 2026.06.07 |
|---|---|
| doom eternal ancient god part 2 (0) | 2026.06.04 |
| doom eternal / dlc 1편 완료 (0) | 2026.05.28 |
| 둠 이터널 dlc / ancient god part 1 (0) | 2026.05.11 |
| 둠 이터널 노말 난이도 끝 (2) | 2026.01.24 |
lighthttpd 보다 얼마나 더 가볍길래 micro를 붙인걸까?
C로 작성된 웹서버. rest 까지 지원은 무리겠지? ㅜㅠ
'파일방' 카테고리의 다른 글
| gary's mod - 게리모드 (0) | 2026.06.24 |
|---|---|
| ventoy 업그레이드 (0) | 2026.06.23 |
| tmux (0) | 2026.05.11 |
| appimage , AppImageLauncher (0) | 2026.04.20 |
| usb device tree viewer (0) | 2026.02.22 |
전체 화면을 scaling 하는 방법. 일장일단이 있겠지만
화면 비율이 다르면 답없는 건 매한가지 ㅠㅠ
[링크 : https://doc.qt.io/archives/qt-5.15/qgraphicsproxywidget.html]
'Programming > qt' 카테고리의 다른 글
| qt 동적 해상도 대응 (0) | 2026.06.29 |
|---|---|
| QT 다국어 지원, qm 만 교체 할수 있도록 변경 (0) | 2026.06.29 |
| QT 다국어 언어 설정 전파 (0) | 2026.06.05 |
| QT 자식 위젯으로 생성 / 부모 위젯 연결 (0) | 2026.06.05 |
| qt QTabWidget 사용 (0) | 2026.06.04 |
간단하게 영상을 분석해서 그걸 text로 매칭시켜주는 녀석이 바로 CLIP / sigLIP 같은 비전 인코더다
그럼 반대로 비전 디코더도 있을것 같은데
[링크 : https://huggingface.co/docs/transformers/v4.15.0/model_doc/visionencoderdecoder]
bert도 어디서 주워들은것 같은데 아무튼 얘도 비전 인코더 인듯.
| LDM에선 BERT Encoder로 사용하였지만 Stable Diffusion에선 OpenAI에서 공개한 CLIP Text Encoder를 사용함 |
[링크 : https://velog.io/@hskhyl/Generative-AI4-imagestable-Diffusion-평가]
| SigLIP 같은 비전 인코더 |
[링크 : https://wikidocs.net/blog/@jaehong/17175/]
| Sigmoid Loss for Language Image Pre-Training SigLIP은 CLIP에서 사용된 손실 함수를 간단한 쌍별 시그모이드 손실(pairwise sigmoid loss)로 대체할 것을 제안합니다. 이는 ImageNet에서 제로샷 분류 정확도 측면에서 더 나은 성능을 보입니다. |
[링크 : https://huggingface.co/papers/2303.15343]
[링크 : https://huggingface.co/docs/transformers/ko/model_doc/siglip]
| CLIP(Contrastive Language-Image Pre-Training)은 다양한 이미지와 텍스트 쌍으로 훈련된 신경망 입니다. |
[링크 : https://huggingface.co/papers/2103.00020]
[링크 : https://huggingface.co/docs/transformers/ko/model_doc/clip]
[링크 : https://huggingface.co/mhbkb/stable-diffusion-base-2.0-clip_1]
[링크 : https://dy120.tistory.com/15]
아무튼 정리하자면..
stable diffusion 에서 txt2img를 할 경우
txt2img로 사용할 임베딩 벡터를 뱉어내는 녀석이 CLIP 이고
그 이후에 노이즈를 지워가면서 그려가는게 전체 작동원리인듯 하다.
'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| gemma4-e4b it qat / gemma4-12b mtp on 1080 ti 11GB (0) | 2026.06.08 |
|---|---|
| nvidia 3070 8GB 테스트 gemma4-e4b (0) | 2026.06.08 |
| chatML (0) | 2026.06.04 |
| gemma 12b, tesla t4 16GB / 1080 ti 11GB * 2 / 3070 8GB (0) | 2026.06.04 |
| nvidia tesla t4 16GB (0) | 2026.06.02 |
QComboBox 등으로 언어를 선택하고 app.installTranslator()를 호출하면
모든 위젯들에게 자동으로 changeLanguage()가 발송된다 (즉, 수동으로 언어 변경 메시지를 전체에 뿌릴 필요가 없다)
| int main(int argc, char *argv[]) { QApplication app(argc, argv); QTranslator myappTranslator; if (myappTranslator.load(QLocale::system(), u"myapp"_s, u"_"_s, u":/i18n"_s)) app.installTranslator(&myappTranslator); return app.exec(); } |
위젯들에게 각각 아래의 이벤트 핸들러를 추가해주면 되는데
헤더에는 protected: 에 override 해서 해주면되고
| protected: void resizeEvent(QResizeEvent *event) override; void changeEvent(QEvent *event) override; |
함수에서는 별거 없이 retranslateUi()를 호출해주면된다.
| void MyWidget::changeEvent(QEvent *event) { if (event->type() == QEvent::LanguageChange) { ui.retranslateUi(this); } else QWidget::changeEvent(event); } |
[링크 : https://doc.qt.io/qt-6/ko/i18n-source-translation.html#prepare-for-dynamic-language-changes]
확실히 이렇게 하니 시그널들 서로 연결한다고 고생안해도 되서 개꿀
'Programming > qt' 카테고리의 다른 글
| QT 다국어 지원, qm 만 교체 할수 있도록 변경 (0) | 2026.06.29 |
|---|---|
| QGraphicsProxyWidget (0) | 2026.06.05 |
| QT 자식 위젯으로 생성 / 부모 위젯 연결 (0) | 2026.06.05 |
| qt QTabWidget 사용 (0) | 2026.06.04 |
| qt 다국어지원 - 보이지 않는 메시지 추가하기 (0) | 2026.06.02 |
위젯 생성시 this를 넣어서 하면, 자식으로 생성되어 별도의 창으로 뜨지 않는다.
| QWidget test = new QWidget(); // 독립된 창으로 뜸 test.show(); QWidget test2 = new QWidget(this); // Mainwindow 안에 뜸 test2.show(); |
간단하게(?) parent를 지정해주냐 안해주냐의 차이인듯.
| class test : public QWidget { Q_OBJECT public: explicit test(QWidget *parent = nullptr); ~test(); } |
'Programming > qt' 카테고리의 다른 글
| QGraphicsProxyWidget (0) | 2026.06.05 |
|---|---|
| QT 다국어 언어 설정 전파 (0) | 2026.06.05 |
| qt QTabWidget 사용 (0) | 2026.06.04 |
| qt 다국어지원 - 보이지 않는 메시지 추가하기 (0) | 2026.06.02 |
| QCombobox + 다국어 (0) | 2026.05.21 |
휴. 빡세고만 ㅠㅠ

'게임 > doom' 카테고리의 다른 글
| doom eternal ancient god part 2 끝! (0) | 2026.06.07 |
|---|---|
| doom eternal , ancient god part 2 최종장 (0) | 2026.06.06 |
| doom eternal / dlc 1편 완료 (0) | 2026.05.28 |
| 둠 이터널 dlc / ancient god part 1 (0) | 2026.05.11 |
| 둠 이터널 노말 난이도 끝 (2) | 2026.01.24 |
| chat template 강제 지정 (가장 흔한 해결책) bash ./llama-cli -m model.gguf \ --chat-template chatml \ # 또는 llama3, qwen, mistral 등 -p "<|im_start|>system\n너는 친절한 AI야<|im_end|>" GGUF 변환 시 chat template 명시적으로 넣기 (최신 llama.cpp) bash python convert_hf_to_gguf.py ./MyModel \ --outfile mymodel.gguf \ --chat-template chatml # 또는 llama3-1 등 |
[링크 : https://x.com/i/grok/share/1f9e9bbccc264a9cbde32f7a95fdb601]
변환 스크립트에서 도움말을 봐도 이렇다할게 없다. 빠졌나?(b9500)
| $ python3 convert_hf_to_gguf.py --help usage: convert_hf_to_gguf.py [-h] [--vocab-only] [--outfile OUTFILE] [--outtype {f32,f16,bf16,q8_0,tq1_0,tq2_0,auto}] [--bigendian] [--use-temp-file] [--no-lazy] [--model-name MODEL_NAME] [--verbose] [--split-max-tensors SPLIT_MAX_TENSORS] [--split-max-size SPLIT_MAX_SIZE] [--dry-run] [--no-tensor-first-split] [--metadata METADATA] [--print-supported-models] [--remote] [--mmproj] [--mtp] [--no-mtp] [--mistral-format] [--disable-mistral-community-chat-template] [--sentence-transformers-dense-modules] [--fuse-gate-up-exps] [--fp8-as-q8] [model] Convert a huggingface model to a GGML compatible file positional arguments: model directory containing model file or huggingface repository ID (if --remote) options: -h, --help show this help message and exit --vocab-only extract only the vocab --outfile OUTFILE path to write to; default: based on input. {ftype} will be replaced by the outtype. --outtype {f32,f16,bf16,q8_0,tq1_0,tq2_0,auto} output format - use f32 for float32, f16 for float16, bf16 for bfloat16, q8_0 for Q8_0, tq1_0 or tq2_0 for ternary, and auto for the highest-fidelity 16-bit float type --bigendian model is executed on big endian machine --use-temp-file use the tempfile library while processing (helpful when running out of memory, process killed) --no-lazy use more RAM by computing all outputs before writing (use in case lazy evaluation is broken) --model-name MODEL_NAME name of the model --verbose increase output verbosity --split-max-tensors SPLIT_MAX_TENSORS max tensors in each split --split-max-size SPLIT_MAX_SIZE max size per split N(M|G) --dry-run only print out a split plan and exit, without writing any new files --no-tensor-first-split do not add tensors to the first split (disabled by default) --metadata METADATA Specify the path for an authorship metadata override file --print-supported-models Print the supported models --remote (Experimental) Read safetensors file remotely without downloading to disk. Config and tokenizer files will still be downloaded. To use this feature, you need to specify Hugging Face model repo name instead of a local directory. For example: 'HuggingFaceTB/SmolLM2-1.7B-Instruct'. Note: To access gated repo, set HF_TOKEN environment variable to your Hugging Face token. --mmproj Export multimodal projector (mmproj) for vision models. This will only work on some vision models. An 'mmproj-' prefix will be added to the output file name. --mtp Export only the multi-token prediction (MTP) head as a separate GGUF, suitable for use as a speculative draft. An 'mtp-' prefix will be added to the output file name. --no-mtp Exclude the multi-token prediction (MTP) head from the converted GGUF. Pair with --mtp on a second run to publish trunk and MTP as two files. Note: the split form duplicates embeddings, but even though the bundled default is more space-efficient overall, this allows differing quantization which may be more performant. --mistral-format Whether the model is stored following the Mistral format. --disable-mistral-community-chat-template Whether to disable usage of Mistral community chat templates. If set, use the Mistral official `mistral-common` library for tokenization and detokenization of Mistral models. Using `mistral-common` ensure correctness and zero-day support of tokenization for models converted from the Mistral format but requires to manually setup the tokenization server. --sentence-transformers-dense-modules Whether to include sentence-transformers dense modules. It can be used for sentence-transformers models, like google/embeddinggemma-300m. Default these modules are not included. --fuse-gate-up-exps Fuse gate_exps and up_exps tensors into a single gate_up_exps tensor for MoE models. --fp8-as-q8 Store tensors dequantized from FP8 as Q8_0 instead of BF16/F16. |
cli 에서는 --chat-template로 어떻게 될 것 같긴한데.. 다시 해봐야겠다.
| $ ./llama-cli --help ----- common params ----- -h, --help, --usage print usage and exit --version show version and build info -cl, --cache-list show list of models in cache --completion-bash print source-able bash completion script for llama.cpp -t, --threads N number of CPU threads to use during generation (default: -1) (env: LLAMA_ARG_THREADS) -tb, --threads-batch N number of threads to use during batch and prompt processing (default: same as --threads) -C, --cpu-mask M CPU affinity mask: arbitrarily long hex. Complements cpu-range (default: "") -Cr, --cpu-range lo-hi range of CPUs for affinity. Complements --cpu-mask --cpu-strict <0|1> use strict CPU placement (default: 0) --prio N set process/thread priority : low(-1), normal(0), medium(1), high(2), realtime(3) (default: 0) --poll <0...100> use polling level to wait for work (0 - no polling, default: 50) -Cb, --cpu-mask-batch M CPU affinity mask: arbitrarily long hex. Complements cpu-range-batch (default: same as --cpu-mask) -Crb, --cpu-range-batch lo-hi ranges of CPUs for affinity. Complements --cpu-mask-batch --cpu-strict-batch <0|1> use strict CPU placement (default: same as --cpu-strict) --prio-batch N set process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --poll-batch <0|1> use polling to wait for work (default: same as --poll) -c, --ctx-size N size of the prompt context (default: 0, 0 = loaded from model) (env: LLAMA_ARG_CTX_SIZE) -n, --predict, --n-predict N number of tokens to predict (default: -1, -1 = infinity) (env: LLAMA_ARG_N_PREDICT) -b, --batch-size N logical maximum batch size (default: 2048) (env: LLAMA_ARG_BATCH) -ub, --ubatch-size N physical maximum batch size (default: 512) (env: LLAMA_ARG_UBATCH) --keep N number of tokens to keep from the initial prompt (default: 0, -1 = all) --swa-full use full-size SWA cache (default: false) [(more info)](https://github.com/ggml-org/llama.cpp/pull/13194#issuecomment-2868343055) (env: LLAMA_ARG_SWA_FULL) -fa, --flash-attn [on|off|auto] set Flash Attention use ('on', 'off', or 'auto', default: 'auto') (env: LLAMA_ARG_FLASH_ATTN) -p, --prompt PROMPT prompt to start generation with; for system message, use -sys --perf, --no-perf whether to enable internal libllama performance timings (default: false) (env: LLAMA_ARG_PERF) -f, --file FNAME a file containing the prompt (default: none) -bf, --binary-file FNAME binary file containing the prompt (default: none) -e, --escape, --no-escape whether to process escapes sequences (\n, \r, \t, \', \", \\) (default: true) --rope-scaling {none,linear,yarn} RoPE frequency scaling method, defaults to linear unless specified by the model (env: LLAMA_ARG_ROPE_SCALING_TYPE) --rope-scale N RoPE context scaling factor, expands context by a factor of N (env: LLAMA_ARG_ROPE_SCALE) --rope-freq-base N RoPE base frequency, used by NTK-aware scaling (default: loaded from model) (env: LLAMA_ARG_ROPE_FREQ_BASE) --rope-freq-scale N RoPE frequency scaling factor, expands context by a factor of 1/N (env: LLAMA_ARG_ROPE_FREQ_SCALE) --yarn-orig-ctx N YaRN: original context size of model (default: 0 = model training context size) (env: LLAMA_ARG_YARN_ORIG_CTX) --yarn-ext-factor N YaRN: extrapolation mix factor (default: -1.00, 0.0 = full interpolation) (env: LLAMA_ARG_YARN_EXT_FACTOR) --yarn-attn-factor N YaRN: scale sqrt(t) or attention magnitude (default: -1.00) (env: LLAMA_ARG_YARN_ATTN_FACTOR) --yarn-beta-slow N YaRN: high correction dim or alpha (default: -1.00) (env: LLAMA_ARG_YARN_BETA_SLOW) --yarn-beta-fast N YaRN: low correction dim or beta (default: -1.00) (env: LLAMA_ARG_YARN_BETA_FAST) -kvo, --kv-offload, -nkvo, --no-kv-offload whether to enable KV cache offloading (default: enabled) (env: LLAMA_ARG_KV_OFFLOAD) --repack, -nr, --no-repack whether to enable weight repacking (default: enabled) (env: LLAMA_ARG_REPACK) --no-host bypass host buffer allowing extra buffers to be used (env: LLAMA_ARG_NO_HOST) -ctk, --cache-type-k TYPE KV cache data type for K allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_K) -ctv, --cache-type-v TYPE KV cache data type for V allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_V) -dt, --defrag-thold N KV cache defragmentation threshold (DEPRECATED) (env: LLAMA_ARG_DEFRAG_THOLD) -np, --parallel N number of parallel sequences to decode (default: 1) (env: LLAMA_ARG_N_PARALLEL) --rpc SERVERS comma-separated list of RPC servers (host:port) (env: LLAMA_ARG_RPC) --mlock force system to keep model in RAM rather than swapping or compressing (env: LLAMA_ARG_MLOCK) --mmap, --no-mmap whether to memory-map model. (if mmap disabled, slower load but may reduce pageouts if not using mlock) (default: enabled) (env: LLAMA_ARG_MMAP) -dio, --direct-io, -ndio, --no-direct-io use DirectIO if available. (default: disabled) (env: LLAMA_ARG_DIO) --numa TYPE attempt optimizations that help on some NUMA systems - distribute: spread execution evenly over all nodes - isolate: only spawn threads on CPUs on the node that execution started on - numactl: use the CPU map provided by numactl if run without this previously, it is recommended to drop the system page cache before using this see https://github.com/ggml-org/llama.cpp/issues/1437 (env: LLAMA_ARG_NUMA) -dev, --device <dev1,dev2,..> comma-separated list of devices to use for offloading (none = don't offload) use --list-devices to see a list of available devices (env: LLAMA_ARG_DEVICE) --list-devices print list of available devices and exit -ot, --override-tensor <tensor name pattern>=<buffer type>,... override tensor buffer type (env: LLAMA_ARG_OVERRIDE_TENSOR) -cmoe, --cpu-moe keep all Mixture of Experts (MoE) weights in the CPU (env: LLAMA_ARG_CPU_MOE) -ncmoe, --n-cpu-moe N keep the Mixture of Experts (MoE) weights of the first N layers in the CPU (env: LLAMA_ARG_N_CPU_MOE) -ngl, --gpu-layers, --n-gpu-layers N max. number of layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS) -sm, --split-mode {none,layer,row,tensor} how to split the model across multiple GPUs, one of: - none: use one GPU only - layer (default): split layers and KV across GPUs (pipelined) - row: split weight across GPUs by rows (parallelized) - tensor: split weights and KV across GPUs (parallelized, EXPERIMENTAL) (env: LLAMA_ARG_SPLIT_MODE) -ts, --tensor-split N0,N1,N2,... fraction of the model to offload to each GPU, comma-separated list of proportions, e.g. 3,1 (env: LLAMA_ARG_TENSOR_SPLIT) -mg, --main-gpu INDEX the GPU to use for the model (with split-mode = none), or for intermediate results and KV (with split-mode = row) (default: 0) (env: LLAMA_ARG_MAIN_GPU) -fit, --fit [on|off] whether to adjust unset arguments to fit in device memory ('on' or 'off', default: 'on') (env: LLAMA_ARG_FIT) -fitt, --fit-target MiB0,MiB1,MiB2,... target margin per device for --fit, comma-separated list of values, single value is broadcast across all devices, default: 1024 (env: LLAMA_ARG_FIT_TARGET) -fitc, --fit-ctx N minimum ctx size that can be set by --fit option, default: 4096 (env: LLAMA_ARG_FIT_CTX) --check-tensors check model tensor data for invalid values (default: false) --override-kv KEY=TYPE:VALUE,... advanced option to override model metadata by key. to specify multiple overrides, either use comma-separated values. types: int, float, bool, str. example: --override-kv tokenizer.ggml.add_bos_token=bool:false,tokenizer.ggml.add_eos_token=bool:false --op-offload, --no-op-offload whether to offload host tensor operations to device (default: true) --lora FNAME path to LoRA adapter (use comma-separated values to load multiple adapters) --lora-scaled FNAME:SCALE,... path to LoRA adapter with user defined scaling (format: FNAME:SCALE,...) note: use comma-separated values --control-vector FNAME add a control vector note: use comma-separated values to add multiple control vectors --control-vector-scaled FNAME:SCALE,... add a control vector with user defined scaling SCALE note: use comma-separated values (format: FNAME:SCALE,...) --control-vector-layer-range START END layer range to apply the control vector(s) to, start and end inclusive -m, --model FNAME model path to load (env: LLAMA_ARG_MODEL) -mu, --model-url MODEL_URL model download url (default: unused) (env: LLAMA_ARG_MODEL_URL) -dr, --docker-repo [<repo>/]<model>[:quant] Docker Hub model repository. repo is optional, default to ai/. quant is optional, default to :latest. example: gemma3 (default: unused) (env: LLAMA_ARG_DOCKER_REPO) -hf, -hfr, --hf-repo <user>/<model>[:quant] Hugging Face model repository; quant is optional, case-insensitive, default to Q4_K_M, or falls back to the first file in the repo if Q4_K_M doesn't exist. mmproj is also downloaded automatically if available. to disable, add --no-mmproj example: ggml-org/GLM-4.7-Flash-GGUF:Q4_K_M (default: unused) (env: LLAMA_ARG_HF_REPO) -hff, --hf-file FILE Hugging Face model file. If specified, it will override the quant in --hf-repo (default: unused) (env: LLAMA_ARG_HF_FILE) -hfv, -hfrv, --hf-repo-v <user>/<model>[:quant] Hugging Face model repository for the vocoder model (default: unused) (env: LLAMA_ARG_HF_REPO_V) -hffv, --hf-file-v FILE Hugging Face model file for the vocoder model (default: unused) (env: LLAMA_ARG_HF_FILE_V) -hft, --hf-token TOKEN Hugging Face access token (default: value from HF_TOKEN environment variable) (env: HF_TOKEN) --log-disable Log disable --log-file FNAME Log to file (env: LLAMA_ARG_LOG_FILE) --log-colors [on|off|auto] Set colored logging ('on', 'off', or 'auto', default: 'auto') 'auto' enables colors when output is to a terminal (env: LLAMA_ARG_LOG_COLORS) -v, --verbose, --log-verbose Set verbosity level to infinity (i.e. log all messages, useful for debugging) --offline Offline mode: forces use of cache, prevents network access (env: LLAMA_ARG_OFFLINE) -lv, --verbosity, --log-verbosity N Set the verbosity threshold. Messages with a higher verbosity will be ignored. Values: - 0: generic output - 1: error - 2: warning - 3: info - 4: trace (more info) - 5: debug (default: 1) (env: LLAMA_ARG_LOG_VERBOSITY) --log-prefix, --no-log-prefix Enable prefix in log messages (env: LLAMA_ARG_LOG_PREFIX) --log-timestamps, --no-log-timestamps Enable timestamps in log messages (env: LLAMA_ARG_LOG_TIMESTAMPS) --spec-draft-type-k, -ctkd, --cache-type-k-draft TYPE KV cache data type for K for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_K) --spec-draft-type-v, -ctvd, --cache-type-v-draft TYPE KV cache data type for V for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_V) ----- sampling params ----- --samplers SAMPLERS samplers that will be used for generation in the order, separated by ';' (default: penalties;dry;top_n_sigma;top_k;typ_p;top_p;min_p;xtc;temperature) -s, --seed SEED RNG seed (default: -1, use random seed for -1) --sampler-seq, --sampling-seq SEQUENCE simplified sequence for samplers that will be used (default: edskypmxt) --ignore-eos ignore end of stream token and continue generating (implies --logit-bias EOS-inf) --temp, --temperature N temperature (default: 0.80) --top-k N top-k sampling (default: 40, 0 = disabled) (env: LLAMA_ARG_TOP_K) --top-p N top-p sampling (default: 0.95, 1.0 = disabled) --min-p N min-p sampling (default: 0.05, 0.0 = disabled) --top-nsigma, --top-n-sigma N top-n-sigma sampling (default: -1.00, -1.0 = disabled) --xtc-probability N xtc probability (default: 0.00, 0.0 = disabled) --xtc-threshold N xtc threshold (default: 0.10, 1.0 = disabled) --typical, --typical-p N locally typical sampling, parameter p (default: 1.00, 1.0 = disabled) --repeat-last-n N last n tokens to consider for penalize (default: 64, 0 = disabled, -1 = ctx_size) --repeat-penalty N penalize repeat sequence of tokens (default: 1.00, 1.0 = disabled) --presence-penalty N repeat alpha presence penalty (default: 0.00, 0.0 = disabled) --frequency-penalty N repeat alpha frequency penalty (default: 0.00, 0.0 = disabled) --dry-multiplier N set DRY sampling multiplier (default: 0.00, 0.0 = disabled) --dry-base N set DRY sampling base value (default: 1.75) --dry-allowed-length N set allowed length for DRY sampling (default: 2) --dry-penalty-last-n N set DRY penalty for the last n tokens (default: -1, 0 = disable, -1 = context size) --dry-sequence-breaker STRING add sequence breaker for DRY sampling, clearing out default breakers ('\n', ':', '"', '*') in the process; use "none" to not use any sequence breakers --adaptive-target N adaptive-p: select tokens near this probability (valid range 0.0 to 1.0; negative = disabled) (default: -1.00) [(more info)](https://github.com/ggml-org/llama.cpp/pull/17927) --adaptive-decay N adaptive-p: decay rate for target adaptation over time. lower values are more reactive, higher values are more stable. (valid range 0.0 to 0.99) (default: 0.90) --dynatemp-range N dynamic temperature range (default: 0.00, 0.0 = disabled) --dynatemp-exp N dynamic temperature exponent (default: 1.00) --mirostat N use Mirostat sampling. Top K, Nucleus and Locally Typical samplers are ignored if used. (default: 0, 0 = disabled, 1 = Mirostat, 2 = Mirostat 2.0) --mirostat-lr N Mirostat learning rate, parameter eta (default: 0.10) --mirostat-ent N Mirostat target entropy, parameter tau (default: 5.00) -l, --logit-bias TOKEN_ID(+/-)BIAS modifies the likelihood of token appearing in the completion, i.e. `--logit-bias 15043+1` to increase likelihood of token ' Hello', or `--logit-bias 15043-1` to decrease likelihood of token ' Hello' --grammar GRAMMAR BNF-like grammar to constrain generations (see samples in grammars/ dir) --grammar-file FNAME file to read grammar from -j, --json-schema SCHEMA JSON schema to constrain generations (https://json-schema.org/), e.g. `{}` for any JSON object For schemas w/ external $refs, use --grammar + example/json_schema_to_grammar.py instead -jf, --json-schema-file FILE File containing a JSON schema to constrain generations (https://json-schema.org/), e.g. `{}` for any JSON object For schemas w/ external $refs, use --grammar + example/json_schema_to_grammar.py instead -bs, --backend-sampling enable backend sampling (experimental) (default: disabled) (env: LLAMA_ARG_BACKEND_SAMPLING) ----- speculative params ----- --spec-draft-hf, -hfd, -hfrd, --hf-repo-draft <user>/<model>[:quant] Same as --hf-repo, but for the draft model (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_HF_REPO) --spec-draft-threads, -td, --threads-draft N number of threads to use during generation (default: same as --threads) --spec-draft-threads-batch, -tbd, --threads-batch-draft N number of threads to use during batch and prompt processing (default: same as --threads-draft) --spec-draft-cpu-mask, -Cd, --cpu-mask-draft M Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) --spec-draft-cpu-range, -Crd, --cpu-range-draft lo-hi Ranges of CPUs for affinity. Complements --cpu-mask-draft --spec-draft-cpu-strict, --cpu-strict-draft <0|1> Use strict CPU placement for draft model (default: same as --cpu-strict) --spec-draft-prio, --prio-draft N set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --spec-draft-poll, --poll-draft <0|1> Use polling to wait for draft model work (default: same as --poll) --spec-draft-cpu-mask-batch, -Cbd, --cpu-mask-batch-draft M Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) --spec-draft-cpu-strict-batch, --cpu-strict-batch-draft <0|1> Use strict CPU placement for draft model (default: --cpu-strict-draft) --spec-draft-prio-batch, --prio-batch-draft N set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) --spec-draft-poll-batch, --poll-batch-draft <0|1> Use polling to wait for draft model work (default: --poll-draft) --spec-draft-override-tensor, -otd, --override-tensor-draft <tensor name pattern>=<buffer type>,... override tensor buffer type for draft model --spec-draft-cpu-moe, -cmoed, --cpu-moe-draft keep all Mixture of Experts (MoE) weights in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_CPU_MOE) --spec-draft-n-cpu-moe, --spec-draft-ncmoe, -ncmoed, --n-cpu-moe-draft N keep the Mixture of Experts (MoE) weights of the first N layers in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_N_CPU_MOE) --spec-draft-n-max N number of tokens to draft for speculative decoding (default: 3) (env: LLAMA_ARG_SPEC_DRAFT_N_MAX) --spec-draft-n-min N minimum number of draft tokens to use for speculative decoding (default: 0) (env: LLAMA_ARG_SPEC_DRAFT_N_MIN) --spec-draft-p-split, --draft-p-split P speculative decoding split probability (default: 0.10) (env: LLAMA_ARG_SPEC_DRAFT_P_SPLIT) --spec-draft-p-min, --draft-p-min P minimum speculative decoding probability (greedy) (default: 0.00) (env: LLAMA_ARG_SPEC_DRAFT_P_MIN) --spec-draft-backend-sampling, --no-spec-draft-backend-sampling offload draft sampling to the backend (default: enabled) (env: LLAMA_ARG_SPEC_DRAFT_BACKEND_SAMPLING) --spec-draft-device, -devd, --device-draft <dev1,dev2,..> comma-separated list of devices to use for offloading the draft model (none = don't offload) use --list-devices to see a list of available devices --spec-draft-ngl, -ngld, --gpu-layers-draft, --n-gpu-layers-draft N max. number of draft model layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS_DRAFT) --spec-draft-model, -md, --model-draft FNAME draft model for speculative decoding (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_MODEL) --spec-type none,draft-simple,draft-eagle3,draft-mtp,ngram-simple,ngram-map-k,ngram-map-k4v,ngram-mod,ngram-cache comma-separated list of types of speculative decoding to use (default: none) (env: LLAMA_ARG_SPEC_TYPE) --spec-ngram-mod-n-min N minimum number of ngram tokens to use for ngram-based speculative decoding (default: 48) --spec-ngram-mod-n-max N maximum number of ngram tokens to use for ngram-based speculative decoding (default: 64) --spec-ngram-mod-n-match N ngram-mod lookup length (default: 24) --spec-ngram-simple-size-n N ngram size N for ngram-simple speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-simple-size-m N ngram size M for ngram-simple speculative decoding, length of draft m-gram (default: 48) --spec-ngram-simple-min-hits N minimum hits for ngram-simple speculative decoding (default: 1) --spec-ngram-map-k-size-n N ngram size N for ngram-map-k speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-map-k-size-m N ngram size M for ngram-map-k speculative decoding, length of draft m-gram (default: 48) --spec-ngram-map-k-min-hits N minimum hits for ngram-map-k speculative decoding (default: 1) --spec-ngram-map-k4v-size-n N ngram size N for ngram-map-k4v speculative decoding, length of lookup n-gram (default: 12) --spec-ngram-map-k4v-size-m N ngram size M for ngram-map-k4v speculative decoding, length of draft m-gram (default: 48) --spec-ngram-map-k4v-min-hits N minimum hits for ngram-map-k4v speculative decoding (default: 1) --draft, --draft-n, --draft-max N the argument has been removed. use --spec-draft-n-max or --spec-ngram-mod-n-max (env: LLAMA_ARG_DRAFT_MAX) --draft-min, --draft-n-min N the argument has been removed. use --spec-draft-n-min or --spec-ngram-mod-n-min (env: LLAMA_ARG_DRAFT_MIN) ----- example-specific params ----- --verbose-prompt print a verbose prompt before generation (default: false) --display-prompt, --no-display-prompt whether to print prompt at generation (default: true) -co, --color [on|off|auto] Colorize output to distinguish prompt and user input from generations ('on', 'off', or 'auto', default: 'auto') 'auto' enables colors when output is to a terminal -ctxcp, --ctx-checkpoints, --swa-checkpoints N max number of context checkpoints to create per slot (default: 32)[(more info)](https://github.com/ggml-org/llama.cpp/pull/15293) (env: LLAMA_ARG_CTX_CHECKPOINTS) -cram, --cache-ram N set the maximum cache size in MiB (default: 8192, -1 - no limit, 0 - disable)[(more info)](https://github.com/ggml-org/llama.cpp/pull/16391) (env: LLAMA_ARG_CACHE_RAM) --context-shift, --no-context-shift whether to use context shift on infinite text generation (default: disabled) (env: LLAMA_ARG_CONTEXT_SHIFT) -sys, --system-prompt PROMPT system prompt to use with model (if applicable, depending on chat template) --show-timings, --no-show-timings whether to show timing information after each response (default: true) (env: LLAMA_ARG_SHOW_TIMINGS) -sysf, --system-prompt-file FNAME a file containing the system prompt (default: none) -r, --reverse-prompt PROMPT halt generation at PROMPT, return control in interactive mode -sp, --special special tokens output enabled (default: false) -cnv, --conversation, -no-cnv, --no-conversation whether to run in conversation mode: - does not print special tokens and suffix/prefix - interactive mode is also enabled (default: auto enabled if chat template is available) -st, --single-turn run conversation for a single turn only, then exit when done will not be interactive if first turn is predefined with --prompt (default: false) -mli, --multiline-input allows you to write or paste multiple lines without ending each in '\' --warmup, --no-warmup whether to perform warmup with an empty run (default: enabled) -mm, --mmproj FILE path to a multimodal projector file. see tools/mtmd/README.md note: if -hf is used, this argument can be omitted (env: LLAMA_ARG_MMPROJ) -mmu, --mmproj-url URL URL to a multimodal projector file. see tools/mtmd/README.md (env: LLAMA_ARG_MMPROJ_URL) --mmproj-auto, --no-mmproj, --no-mmproj-auto whether to use multimodal projector file (if available), useful when using -hf (default: enabled) (env: LLAMA_ARG_MMPROJ_AUTO) --mmproj-offload, --no-mmproj-offload whether to enable GPU offloading for multimodal projector (default: enabled) (env: LLAMA_ARG_MMPROJ_OFFLOAD) --image, --audio FILE path to an image or audio file. use with multimodal models, use comma-separated values for multiple files --image-min-tokens N minimum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MIN_TOKENS) --image-max-tokens N maximum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MAX_TOKENS) --chat-template-kwargs STRING sets additional params for the json template parser, must be a valid json object string, e.g. '{"key1":"value1","key2":"value2"}' (env: LLAMA_ARG_CHAT_TEMPLATE_KWARGS) --jinja, --no-jinja whether to use jinja template engine for chat (default: enabled) (env: LLAMA_ARG_JINJA) --reasoning-format FORMAT controls whether thought tags are allowed and/or extracted from the response, and in which format they're returned; one of: - none: leaves thoughts unparsed in `message.content` - deepseek: puts thoughts in `message.reasoning_content` - deepseek-legacy: keeps `<think>` tags in `message.content` while also populating `message.reasoning_content` (default: auto) (env: LLAMA_ARG_THINK) -rea, --reasoning [on|off|auto] Use reasoning/thinking in the chat ('on', 'off', or 'auto', default: 'auto' (detect from template)) (env: LLAMA_ARG_REASONING) --reasoning-budget N token budget for thinking: -1 for unrestricted, 0 for immediate end, N>0 for token budget (default: -1) (env: LLAMA_ARG_THINK_BUDGET) --reasoning-budget-message MESSAGE message injected before the end-of-thinking tag when reasoning budget is exhausted (default: none) (env: LLAMA_ARG_THINK_BUDGET_MESSAGE) --chat-template JINJA_TEMPLATE set custom jinja chat template (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE) --chat-template-file JINJA_TEMPLATE_FILE set custom jinja chat template file (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE_FILE) --skip-chat-parsing, --no-skip-chat-parsing force a pure content parser, even if a Jinja template is specified; model will output everything in the content section, including any reasoning and/or tool calls (default: disabled) (env: LLAMA_ARG_SKIP_CHAT_PARSING) --simple-io use basic IO for better compatibility in subprocesses and limited consoles --gpt-oss-20b-default use gpt-oss-20b (note: can download weights from the internet) --gpt-oss-120b-default use gpt-oss-120b (note: can download weights from the internet) --vision-gemma-4b-default use Gemma 3 4B QAT (note: can download weights from the internet) --vision-gemma-12b-default use Gemma 3 12B QAT (note: can download weights from the internet) --spec-default enable default speculative decoding config |
[링크 : https://www.sktenterprise.com/bizInsight/blogDetail/dev/10236]
[링크 : https://huggingface.co/google/gemma-1.1-2b-it]
'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| nvidia 3070 8GB 테스트 gemma4-e4b (0) | 2026.06.08 |
|---|---|
| sigLIP, CLIP (0) | 2026.06.05 |
| gemma 12b, tesla t4 16GB / 1080 ti 11GB * 2 / 3070 8GB (0) | 2026.06.04 |
| nvidia tesla t4 16GB (0) | 2026.06.02 |
| llama.cpp reasoning 옵션 (0) | 2026.06.01 |


