요즘 가장 핫한 녀석
llama.cpp 처럼 ai 모델을 돌리는 프로그램인데
qwen3.8 flash next를 돌리는데 목적이 있는 것 같다.
| Qwen3.8-Flash-Next on any consumer hardware: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input. |
[링크 : https://github.com/niko1221/strata]
대충 계산해보면.. 최악의 경우(?) 131 * 3.3G = 432.3GB 정도 되는 모델이고
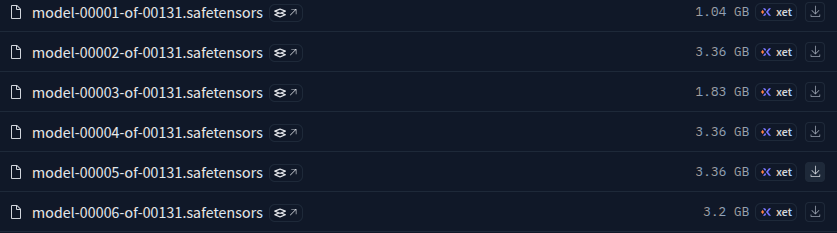
[링크 : https://huggingface.co/Qwen/Qwen3.8-Flash-Next/tree/main]
Q2 양자화로도 80기가.. 아니 이걸 어떻게 돌리라고 -_-
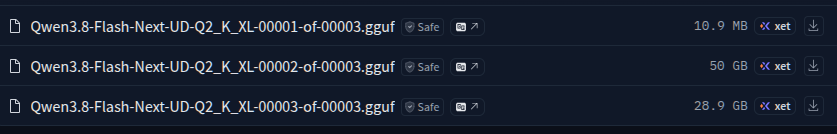
[링크 : https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/tree/main]
아무튼 VRAM을 최소화(?) 하고 RAM을 미친듯이 먹는걸 보면..
cpu offload는 하지 않고 아주 빈번하고 VRAM을 바꾸면서 연산을 하도록 하여, 대용량 모델을 돌릴수 있게 하나보다.
| Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter model that normally needs a server, on a normal PC. It chats, writes code, reads pictures and works with your apps and coding agents. Your chats and files stay on your PC. New here? Check what you need, then install the app. Runs on a gaming PC. 32 GB of RAM and graphics memory together is enough to start. Works with your tools. It speaks the OpenAI and Anthropic APIs, so Claude Code, Codex CLI, OpenCode and other agents connect to it. Reads pictures. They are on by default. Free. MIT license, no account, no cloud. Private. No telemetry. What Strata downloads, when it uses the internet and how it checks downloads is in docs/SAFETY.md. You need at least 32 GB of RAM and graphics memory (VRAM) together. On a Mac or a Ryzen AI Max, that is the unified memory. More memory gives a bigger model or a faster one. A 32 GB PC with a 12-16 GB card runs the Coder. 64 GB of RAM runs every size. |
'모종의 음모 > ai 프로그램' 카테고리의 다른 글
| 프로그래밍도 할 줄 아는 local LLM 만들기.. part 2? (0) | 2026.10.20 |
|---|---|
| 프로그래밍도 할 줄 아는 local LLM 만들기.. part 1? (0) | 2026.10.16 |
| cyc 프로젝트, dreamcoder (0) | 2026.10.16 |
| 클로드 코드, 루틴 좋네? (0) | 2026.10.06 |
| 클로드 사용량 재설정 (0) | 2026.09.29 |


