pytorch 껀진 모르겠는데 아무튼, 

torchvision에 model을 뒤지다 보니

mobilenet v3 관련 QAT 가 있어서 정리


[링크 : https://github.com/gdwang08/STFPM]

[링크 : https://github.com/gdwang08/STFPM/blob/main/main.py]

[링크 : https://docs.pytorch.org/vision/main/models/mobilenetv3_quant.html#model-builders]

[링크 : https://github.com/pytorch/vision/blob/main/torchvision/models/quantization/mobilenetv3.py]

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

nvidia tesla t4 16GB  (0) 2026.06.02
llama.cpp reasoning 옵션  (0) 2026.06.01
safetensors to gguf 일단 실패  (0) 2026.06.01
antigravity 2  (0) 2026.05.28
telegram bot api 로 기능 변경하기  (0) 2026.05.25
Posted by 구차니

한번 해봐야지. 그나저나 1080 에서 F16만 된다고 하면.. 그냥 직접 변환하는것도 방법이 될려나?

/llama.cpp$ ls convert_*
convert_hf_to_gguf.py  convert_hf_to_gguf_update.py  convert_llama_ggml_to_gguf.py  convert_lora_to_gguf.py


[링크 : https://huggingface.co/google/gemma-4-E4B/tree/main]

[링크 : https://velog.io/@choonsik_mom/llama.cpp로-gguf-모델-서빙하기-ul02hone]


+

실행해보면 다음과 같이 나오고

$ /home/minimonk/src/llama.cpp/convert_hf_to_gguf.py 
usage: convert_hf_to_gguf.py [-h] [--vocab-only] [--outfile OUTFILE] [--outtype {f32,f16,bf16,q8_0,tq1_0,tq2_0,auto}]
                             [--bigendian] [--use-temp-file] [--no-lazy] [--model-name MODEL_NAME] [--verbose]
                             [--split-max-tensors SPLIT_MAX_TENSORS] [--split-max-size SPLIT_MAX_SIZE] [--dry-run]
                             [--no-tensor-first-split] [--metadata METADATA] [--print-supported-models] [--remote]
                             [--mmproj] [--mistral-format] [--disable-mistral-community-chat-template]
                             [--sentence-transformers-dense-modules] [--fuse-gate-up-exps]
                             [model]
convert_hf_to_gguf.py: error: the following arguments are required: model


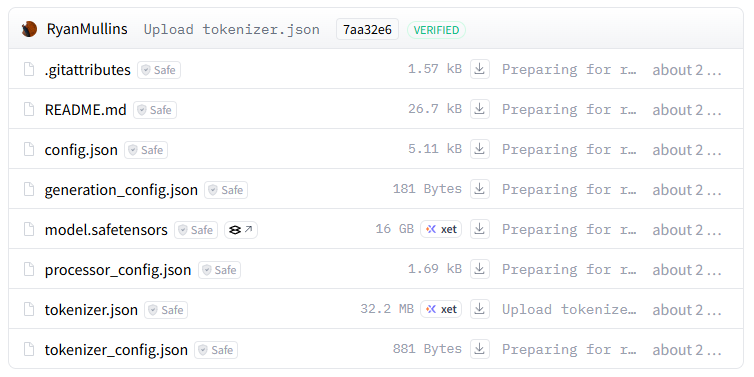
huggingface를 통해서 받아도 되고, 최소한의 파일 저 3개를 받아줘도 된다.

/mnt/Downloads/model/gemma4-e4b/google$ ls
config.json  model.safetensors  tokenizer.json


GPU를 사용하지 않고, 한번에 메모리에 전부 올려서 하는건지 메모리 터져서 한번 리부팅.. 크흡

그 와중에 옵션 안주니까 BF16 으로 설정해버리는 센스(!) 하지만 난 BF16 가속을 못받는 하드웨어.. ㅠ

$ /home/minimonk/src/llama.cpp/convert_hf_to_gguf.py ./google/ --outfile gguf.gguf
INFO:hf-to-gguf:Loading model: google
INFO:hf-to-gguf:Model architecture: Gemma4ForConditionalGeneration
INFO:hf-to-gguf:gguf: indexing model part 'model.safetensors'
INFO:hf-to-gguf:heuristics detected bfloat16 tensor dtype, setting --outtype bf16
INFO:gguf.gguf_writer:gguf: This GGUF file is for Little Endian only
INFO:hf-to-gguf:Exporting model...

Writing:   9%|██████▎                                                                | 1.34G/15.0G [00:20<01:16, 180Mbyte/s]

Writing: 100%|███████████████████████████████████████████████████████████████████████| 15.0G/15.0G [01:54<00:00, 131Mbyte/s]
INFO:hf-to-gguf:Model successfully exported to gguf.gguf


exporting model.. 과 wrting 사이 로그

더보기

INFO:hf-to-gguf:rope_freqs.weight,                 torch.float32 --> F32, shape = {256}
INFO:hf-to-gguf:token_embd.weight,                 torch.bfloat16 --> BF16, shape = {2560, 262144}
INFO:hf-to-gguf:per_layer_token_embd.weight,       torch.bfloat16 --> BF16, shape = {10752, 262144}
INFO:hf-to-gguf:blk.0.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.0.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.0.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.0.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.0.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.0.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.0.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.0.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.0.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.0.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.0.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.0.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.1.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.1.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.1.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.1.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.1.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.1.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.1.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.1.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.1.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.1.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.1.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.1.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.10.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.10.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.10.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.10.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.10.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.10.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.10.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.10.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.10.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.10.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.10.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.10.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.11.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.11.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.11.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.11.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.11.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.11.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.11.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.11.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.11.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.11.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.11.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.11.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.12.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.12.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.12.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.12.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.12.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.12.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.12.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.12.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.12.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.12.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.12.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.12.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.13.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.13.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.13.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.13.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.13.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.13.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.13.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.13.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.13.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.13.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.13.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.13.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.14.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.14.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.14.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.14.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.14.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.14.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.14.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.14.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.14.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.14.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.14.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.14.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.15.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.15.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.15.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.15.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.15.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.15.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.15.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.15.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.15.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.15.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.15.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.15.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.16.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.16.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.16.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.16.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.16.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.16.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.16.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.16.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.16.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.16.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.16.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.16.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.17.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.17.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.17.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.17.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.17.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.17.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.17.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.17.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.17.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.17.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.17.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.17.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.18.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.18.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.18.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.18.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.18.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.18.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.18.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.18.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.18.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.18.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.18.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.18.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.19.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.19.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.19.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.19.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.19.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.19.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.19.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.19.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.19.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.19.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.19.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.19.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.2.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.2.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.2.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.2.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.2.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.2.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.2.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.2.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.2.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.2.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.2.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.2.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.20.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.20.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.20.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.20.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.20.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.20.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.20.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.20.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.20.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.20.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.20.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.20.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.21.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.21.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.21.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.21.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.21.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.21.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.21.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.21.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.21.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.21.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.21.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.21.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.22.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.22.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.22.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.22.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.22.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.22.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.22.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.22.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.22.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.22.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.22.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.22.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.23.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.23.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.23.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.23.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.23.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.23.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.23.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.23.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.23.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.23.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.23.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.23.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.24.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.24.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.24.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.24.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.24.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.24.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.24.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.24.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.24.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.24.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.24.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.24.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.25.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.25.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.25.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.25.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.25.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.25.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.25.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.25.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.25.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.25.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.25.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.25.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.26.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.26.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.26.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.26.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.26.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.26.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.26.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.26.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.26.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.26.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.26.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.26.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.27.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.27.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.27.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.27.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.27.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.27.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.27.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.27.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.27.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.27.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.27.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.27.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.28.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.28.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.28.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.28.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.28.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.28.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.28.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.28.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.28.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.28.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.28.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.28.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.29.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.29.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.29.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.29.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.29.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.29.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.29.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.29.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.29.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.29.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.29.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.29.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.3.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.3.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.3.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.3.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.3.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.3.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.3.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.3.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.3.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.3.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.3.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.3.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.30.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.30.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.30.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.30.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.30.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.30.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.30.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.30.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.30.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.30.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.30.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.30.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.31.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.31.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.31.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.31.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.31.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.31.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.31.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.31.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.31.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.31.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.31.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.31.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.32.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.32.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.32.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.32.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.32.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.32.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.32.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.32.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.32.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.32.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.32.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.32.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.33.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.33.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.33.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.33.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.33.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.33.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.33.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.33.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.33.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.33.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.33.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.33.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.34.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.34.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.34.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.34.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.34.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.34.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.34.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.34.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.34.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.34.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.34.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.34.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.35.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.35.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.35.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.35.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.35.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.35.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.35.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.35.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.35.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.35.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.35.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.35.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.36.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.36.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.36.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.36.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.36.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.36.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.36.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.36.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.36.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.36.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.36.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.36.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.37.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.37.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.37.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.37.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.37.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.37.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.37.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.37.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.37.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.37.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.37.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.37.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.38.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.38.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.38.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.38.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.38.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.38.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.38.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.38.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.38.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.38.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.38.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.38.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.39.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.39.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.39.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.39.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.39.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.39.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.39.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.39.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.39.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.39.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.39.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.39.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.4.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.4.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.4.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.4.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.4.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.4.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.4.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.4.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.4.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.4.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.4.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.4.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.40.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.40.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.40.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.40.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.40.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.40.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.40.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.40.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.40.attn_output.weight,         torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.40.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.40.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.40.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.41.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.41.ffn_down.weight,            torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.41.ffn_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.41.ffn_up.weight,              torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.41.inp_gate.weight,            torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.41.proj.weight,                torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.41.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.41.attn_k.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.41.attn_output.weight,         torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.41.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.41.attn_q.weight,              torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.41.attn_v.weight,              torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.5.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.5.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.5.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.5.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.5.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.5.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.5.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.5.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.5.attn_output.weight,          torch.bfloat16 --> BF16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.5.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.5.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.5.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.6.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.6.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.6.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.6.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.6.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.6.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.6.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.6.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.6.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.6.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.6.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.6.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.7.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.7.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.7.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.7.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.7.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.7.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.7.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.7.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.7.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.7.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.7.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.7.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.8.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.8.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.8.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.8.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.8.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.8.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.8.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.8.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.8.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.8.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.8.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.8.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.9.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.9.ffn_down.weight,             torch.bfloat16 --> BF16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.9.ffn_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.9.ffn_up.weight,               torch.bfloat16 --> BF16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.9.inp_gate.weight,             torch.bfloat16 --> BF16, shape = {2560, 256}
INFO:hf-to-gguf:blk.9.proj.weight,                 torch.bfloat16 --> BF16, shape = {256, 2560}
INFO:hf-to-gguf:blk.9.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.9.attn_k.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:blk.9.attn_output.weight,          torch.bfloat16 --> BF16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.9.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.9.attn_q.weight,               torch.bfloat16 --> BF16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.9.attn_v.weight,               torch.bfloat16 --> BF16, shape = {2560, 512}
INFO:hf-to-gguf:output_norm.weight,                torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:per_layer_model_proj.weight,       torch.bfloat16 --> BF16, shape = {2560, 10752}
INFO:hf-to-gguf:per_layer_proj_norm.weight,        torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:Set meta model
INFO:hf-to-gguf:Set model parameters
INFO:hf-to-gguf:gguf: context length = 131072
INFO:hf-to-gguf:gguf: embedding length = 2560
INFO:hf-to-gguf:gguf: feed forward length = 10240
INFO:hf-to-gguf:gguf: head count = 8
INFO:hf-to-gguf:gguf: key-value head count = 2
WARNING:hf-to-gguf:Unknown RoPE type: proportional
INFO:hf-to-gguf:gguf: rope scaling type = NONE
INFO:hf-to-gguf:gguf: rope theta = 1000000.0
INFO:hf-to-gguf:gguf: rope theta swa = 10000.0
INFO:hf-to-gguf:gguf: rms norm epsilon = 1e-06
INFO:hf-to-gguf:gguf: file type = 32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.context_length', overwriting it with new value 131072 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.head_count', overwriting it with new value 8 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.layer_norm_rms_epsilon', overwriting it with new value 1e-06 of type FLOAT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.key_length', overwriting it with new value 256 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.value_length', overwriting it with new value 256 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.rope.freq_base', overwriting it with new value 1000000.0 of type FLOAT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.head_count_kv', overwriting it with new value 2 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.key_length', overwriting it with new value 512 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.value_length', overwriting it with new value 512 of type UINT32
INFO:hf-to-gguf:Set model quantization version
INFO:hf-to-gguf:Set model tokenizer
INFO:hf-to-gguf:Token '<|tool_call>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<tool_call|>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<|tool_response>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<tool_response|>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<|"|>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<|channel>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<channel|>' is set to USER_DEFINED
WARNING:gguf.vocab:Unknown separator token '<bos>' in TemplateProcessing<pair>
INFO:gguf.vocab:Adding 514906 merge(s).
INFO:gguf.vocab:Setting special token type bos to 2
INFO:gguf.vocab:Setting special token type eos to 1
INFO:gguf.vocab:Setting special token type pad to 0
INFO:gguf.vocab:Setting add_bos_token to True
INFO:gguf.vocab:Setting add_sep_token to False
WARNING:gguf.gguf_writer:Duplicated key name 'tokenizer.ggml.add_bos_token', overwriting it with new value True of type BOOL
INFO:gguf.gguf_writer:Writing the following files:
INFO:gguf.gguf_writer:gguf.gguf: n_tensors = 720, total_size = 15.0G


둘 다 머.. 거의 동일한 사이즈로 나왔다. 1기가도 안줄었네

drwxrwxr-x 2 minimonk minimonk        4096  6월  1 13:52 ./
drwxrwxr-x 3 minimonk minimonk        4096  6월  1 13:52 ../
-rw-rw-r-- 1 minimonk minimonk        5105  6월  1 13:51 config.json
-rw-rw-r-- 1 minimonk minimonk 15992595884  6월  1 13:03 model.safetensors
-rw-rw-r-- 1 minimonk minimonk    32170070  6월  1 13:51 tokenizer.json
-rw-rw-r-- 1 minimonk minimonk 15053078208  6월  1 14:01 gguf.gguf


그래서 F16 으로 하게 했더니  BF16 이나 F16 이나 용량은 바이트 단위 까지 동일!

-rw-rw-r-- 1 minimonk minimonk 15053078208  6월  1 14:05 gguf.gguf


일단 옵션은 outtype 으로 주면된다.

$ /home/minimonk/src/llama.cpp/convert_hf_to_gguf.py ./google/ --outfile gguf.gguf --outtype f16
INFO:hf-to-gguf:Loading model: google
INFO:hf-to-gguf:Model architecture: Gemma4ForConditionalGeneration
INFO:hf-to-gguf:gguf: indexing model part 'model.safetensors'
INFO:gguf.gguf_writer:gguf: This GGUF file is for Little Endian only
INFO:hf-to-gguf:Exporting model...

Writing:   9%|██████▎                                                                | 1.34G/15.0G [00:02<00:27, 503Mbyte/s]

Writing: 100%|███████████████████████████████████████████████████████████████████████| 15.0G/15.0G [00:49<00:00, 305Mbyte/s]
INFO:hf-to-gguf:Model successfully exported to gguf.gguf


exporting model.. 과 wrting 사이 로그

더보기

INFO:hf-to-gguf:rope_freqs.weight,                 torch.float32 --> F32, shape = {256}
INFO:hf-to-gguf:token_embd.weight,                 torch.bfloat16 --> F16, shape = {2560, 262144}
INFO:hf-to-gguf:per_layer_token_embd.weight,       torch.bfloat16 --> F16, shape = {10752, 262144}
INFO:hf-to-gguf:blk.0.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.0.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.0.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.0.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.0.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.0.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.0.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.0.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.0.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.0.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.0.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.0.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.0.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.1.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.1.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.1.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.1.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.1.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.1.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.1.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.1.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.1.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.1.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.1.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.1.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.1.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.10.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.10.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.10.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.10.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.10.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.10.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.10.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.10.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.10.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.10.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.10.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.10.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.10.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.11.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.11.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.11.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.11.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.11.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.11.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.11.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.11.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.11.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.11.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.11.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.11.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.11.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.12.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.12.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.12.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.12.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.12.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.12.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.12.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.12.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.12.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.12.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.12.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.12.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.12.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.13.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.13.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.13.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.13.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.13.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.13.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.13.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.13.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.13.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.13.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.13.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.13.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.13.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.14.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.14.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.14.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.14.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.14.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.14.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.14.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.14.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.14.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.14.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.14.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.14.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.14.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.15.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.15.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.15.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.15.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.15.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.15.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.15.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.15.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.15.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.15.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.15.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.15.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.15.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.16.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.16.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.16.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.16.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.16.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.16.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.16.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.16.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.16.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.16.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.16.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.16.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.16.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.17.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.17.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.17.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.17.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.17.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.17.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.17.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.17.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.17.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.17.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.17.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.17.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.17.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.18.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.18.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.18.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.18.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.18.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.18.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.18.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.18.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.18.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.18.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.18.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.18.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.18.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.19.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.19.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.19.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.19.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.19.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.19.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.19.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.19.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.19.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.19.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.19.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.19.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.19.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.2.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.2.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.2.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.2.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.2.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.2.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.2.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.2.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.2.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.2.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.2.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.2.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.2.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.20.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.20.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.20.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.20.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.20.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.20.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.20.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.20.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.20.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.20.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.20.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.20.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.20.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.21.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.21.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.21.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.21.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.21.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.21.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.21.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.21.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.21.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.21.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.21.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.21.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.21.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.22.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.22.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.22.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.22.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.22.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.22.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.22.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.22.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.22.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.22.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.22.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.22.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.22.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.23.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.23.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.23.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.23.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.23.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.23.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.23.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.23.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.23.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.23.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.23.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.23.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.23.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.24.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.24.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.24.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.24.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.24.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.24.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.24.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.24.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.24.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.24.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.24.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.24.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.24.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.25.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.25.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.25.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.25.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.25.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.25.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.25.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.25.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.25.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.25.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.25.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.25.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.25.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.26.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.26.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.26.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.26.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.26.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.26.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.26.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.26.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.26.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.26.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.26.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.26.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.26.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.27.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.27.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.27.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.27.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.27.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.27.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.27.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.27.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.27.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.27.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.27.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.27.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.27.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.28.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.28.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.28.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.28.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.28.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.28.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.28.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.28.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.28.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.28.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.28.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.28.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.28.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.29.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.29.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.29.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.29.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.29.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.29.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.29.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.29.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.29.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.29.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.29.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.29.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.29.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.3.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.3.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.3.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.3.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.3.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.3.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.3.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.3.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.3.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.3.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.3.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.3.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.3.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.30.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.30.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.30.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.30.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.30.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.30.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.30.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.30.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.30.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.30.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.30.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.30.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.30.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.31.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.31.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.31.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.31.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.31.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.31.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.31.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.31.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.31.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.31.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.31.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.31.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.31.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.32.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.32.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.32.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.32.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.32.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.32.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.32.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.32.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.32.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.32.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.32.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.32.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.32.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.33.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.33.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.33.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.33.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.33.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.33.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.33.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.33.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.33.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.33.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.33.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.33.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.33.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.34.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.34.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.34.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.34.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.34.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.34.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.34.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.34.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.34.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.34.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.34.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.34.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.34.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.35.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.35.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.35.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.35.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.35.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.35.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.35.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.35.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.35.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.35.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.35.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.35.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.35.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.36.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.36.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.36.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.36.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.36.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.36.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.36.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.36.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.36.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.36.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.36.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.36.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.36.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.37.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.37.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.37.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.37.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.37.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.37.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.37.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.37.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.37.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.37.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.37.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.37.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.37.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.38.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.38.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.38.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.38.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.38.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.38.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.38.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.38.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.38.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.38.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.38.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.38.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.38.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.39.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.39.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.39.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.39.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.39.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.39.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.39.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.39.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.39.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.39.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.39.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.39.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.39.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.4.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.4.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.4.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.4.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.4.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.4.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.4.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.4.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.4.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.4.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.4.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.4.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.4.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.40.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.40.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.40.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.40.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.40.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.40.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.40.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.40.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.40.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.40.attn_output.weight,         torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.40.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.40.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.40.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.41.attn_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.layer_output_scale.weight,  torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.41.ffn_down.weight,            torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.41.ffn_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.41.ffn_up.weight,              torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.41.inp_gate.weight,            torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.41.proj.weight,                torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.41.post_attention_norm.weight, torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.post_ffw_norm.weight,       torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.post_norm.weight,           torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.ffn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.41.attn_k_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.41.attn_k.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.41.attn_output.weight,         torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.41.attn_q_norm.weight,         torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.41.attn_q.weight,              torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.41.attn_v.weight,              torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.5.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.5.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.5.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.5.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.5.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.5.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.5.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.5.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.5.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.5.attn_output.weight,          torch.bfloat16 --> F16, shape = {4096, 2560}
INFO:hf-to-gguf:blk.5.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {512}
INFO:hf-to-gguf:blk.5.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 4096}
INFO:hf-to-gguf:blk.5.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 1024}
INFO:hf-to-gguf:blk.6.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.6.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.6.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.6.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.6.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.6.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.6.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.6.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.6.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.6.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.6.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.6.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.6.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.7.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.7.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.7.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.7.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.7.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.7.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.7.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.7.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.7.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.7.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.7.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.7.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.7.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.8.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.8.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.8.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.8.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.8.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.8.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.8.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.8.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.8.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.8.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.8.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.8.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.8.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.9.attn_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.layer_output_scale.weight,   torch.bfloat16 --> F32, shape = {1}
INFO:hf-to-gguf:blk.9.ffn_down.weight,             torch.bfloat16 --> F16, shape = {10240, 2560}
INFO:hf-to-gguf:blk.9.ffn_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.9.ffn_up.weight,               torch.bfloat16 --> F16, shape = {2560, 10240}
INFO:hf-to-gguf:blk.9.inp_gate.weight,             torch.bfloat16 --> F16, shape = {2560, 256}
INFO:hf-to-gguf:blk.9.proj.weight,                 torch.bfloat16 --> F16, shape = {256, 2560}
INFO:hf-to-gguf:blk.9.post_attention_norm.weight,  torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.post_ffw_norm.weight,        torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.post_norm.weight,            torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.ffn_norm.weight,             torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:blk.9.attn_k_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.9.attn_k.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:blk.9.attn_output.weight,          torch.bfloat16 --> F16, shape = {2048, 2560}
INFO:hf-to-gguf:blk.9.attn_q_norm.weight,          torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:blk.9.attn_q.weight,               torch.bfloat16 --> F16, shape = {2560, 2048}
INFO:hf-to-gguf:blk.9.attn_v.weight,               torch.bfloat16 --> F16, shape = {2560, 512}
INFO:hf-to-gguf:output_norm.weight,                torch.bfloat16 --> F32, shape = {2560}
INFO:hf-to-gguf:per_layer_model_proj.weight,       torch.bfloat16 --> F16, shape = {2560, 10752}
INFO:hf-to-gguf:per_layer_proj_norm.weight,        torch.bfloat16 --> F32, shape = {256}
INFO:hf-to-gguf:Set meta model
INFO:hf-to-gguf:Set model parameters
INFO:hf-to-gguf:gguf: context length = 131072
INFO:hf-to-gguf:gguf: embedding length = 2560
INFO:hf-to-gguf:gguf: feed forward length = 10240
INFO:hf-to-gguf:gguf: head count = 8
INFO:hf-to-gguf:gguf: key-value head count = 2
WARNING:hf-to-gguf:Unknown RoPE type: proportional
INFO:hf-to-gguf:gguf: rope scaling type = NONE
INFO:hf-to-gguf:gguf: rope theta = 1000000.0
INFO:hf-to-gguf:gguf: rope theta swa = 10000.0
INFO:hf-to-gguf:gguf: rms norm epsilon = 1e-06
INFO:hf-to-gguf:gguf: file type = 1
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.context_length', overwriting it with new value 131072 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.head_count', overwriting it with new value 8 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.layer_norm_rms_epsilon', overwriting it with new value 1e-06 of type FLOAT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.key_length', overwriting it with new value 256 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.value_length', overwriting it with new value 256 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.rope.freq_base', overwriting it with new value 1000000.0 of type FLOAT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.head_count_kv', overwriting it with new value 2 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.key_length', overwriting it with new value 512 of type UINT32
WARNING:gguf.gguf_writer:Duplicated key name 'gemma4.attention.value_length', overwriting it with new value 512 of type UINT32
INFO:hf-to-gguf:Set model quantization version
INFO:hf-to-gguf:Set model tokenizer
INFO:hf-to-gguf:Token '<|tool_call>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<tool_call|>' is set to USER_DEFINED</tool_call|>
INFO:hf-to-gguf:Token '<|tool_response>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<tool_response|>' is set to USER_DEFINED</tool_response|>
INFO:hf-to-gguf:Token '<|"|>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<|channel>' is set to USER_DEFINED
INFO:hf-to-gguf:Token '<channel|>' is set to USER_DEFINED</channel|>
WARNING:gguf.vocab:Unknown separator token '' in TemplateProcessing
INFO:gguf.vocab:Adding 514906 merge(s).
INFO:gguf.vocab:Setting special token type bos to 2
INFO:gguf.vocab:Setting special token type eos to 1
INFO:gguf.vocab:Setting special token type pad to 0
INFO:gguf.vocab:Setting add_bos_token to True
INFO:gguf.vocab:Setting add_sep_token to False
WARNING:gguf.gguf_writer:Duplicated key name 'tokenizer.ggml.add_bos_token', overwriting it with new value True of type BOOL
INFO:gguf.gguf_writer:Writing the following files:
INFO:gguf.gguf_writer:gguf.gguf: n_tensors = 720, total_size = 15.0G


양자화 F16 으로 했더니 14GB 정도 합산해서 먹고 있고


llama.cpp로 해보니 애가 오작동한다. 왜 저러니 ㅠㅠ


+

$ /mnt/Downloads/llama-b9305/llama-quantize 
usage: /mnt/Downloads/llama-b9305/llama-quantize [--help] [--allow-requantize] [--leave-output-tensor] [--pure] [--imatrix] [--include-weights]
       [--exclude-weights] [--output-tensor-type] [--token-embedding-type] [--tensor-type] [--tensor-type-file]
       [--prune-layers] [--keep-split] [--override-kv] [--dry-run]
       model-f32.gguf [model-quant.gguf] type [nthreads]

  --allow-requantize
                                      allow requantizing tensors that have already been quantized
                                      WARNING: this can severely reduce quality compared to quantizing
                                               from 16bit or 32bit!
  --leave-output-tensor
                                      leave output.weight un(re)quantized
                                      increases model size but may also increase quality, especially when requantizing
  --pure
                                      disable k-quant mixtures and quantize all tensors to the same type
  --imatrix file_name
                                      use data in file_name as importance matrix for quant optimizations
  --include-weights tensor_name
                                      use importance matrix for this/these tensor(s)
  --exclude-weights tensor_name
                                      do not use importance matrix for this/these tensor(s)
  --output-tensor-type ggml_type
                                      use this ggml_type for the output.weight tensor
  --token-embedding-type ggml_type
                                      use this ggml_type for the token embeddings tensor
  --tensor-type tensor_name=ggml_type
                                      quantize this tensor to this ggml_type
                                      this is an advanced option to selectively quantize tensors. may be specified multiple times.
                                      example: --tensor-type attn_q=q8_0
  --tensor-type-file tensor_types.txt
                                      list of tensors to quantize to a specific ggml_type
                                      this is an advanced option to selectively quantize a long list of tensors.
                                      the file should use the same format as above, separated by spaces or newlines.
  --prune-layers L0,L1,L2...
                                      comma-separated list of layer numbers to prune from the model
                                      WARNING: this is an advanced option, use with care.
  --keep-split
                                      generate quantized model in the same shards as input
  --override-kv KEY=TYPE:VALUE
                                      override model metadata by key in the quantized model. may be specified multiple times.
                                      WARNING: this is an advanced option, use with care.
  --dry-run
                                      calculate and show the final quantization size without performing quantization
                                      example: llama-quantize --dry-run model-f32.gguf Q4_K

note: --include-weights and --exclude-weights cannot be used together

-----------------------------------------------------------------------------
 allowed quantization types
-----------------------------------------------------------------------------

  40  or  Q1_0    :  1.125 bpw quantization
   2  or  Q4_0    :  4.34G, +0.4685 ppl @ Llama-3-8B
   3  or  Q4_1    :  4.78G, +0.4511 ppl @ Llama-3-8B
  38  or  MXFP4_MOE :  MXFP4 MoE
   8  or  Q5_0    :  5.21G, +0.1316 ppl @ Llama-3-8B
   9  or  Q5_1    :  5.65G, +0.1062 ppl @ Llama-3-8B
  19  or  IQ2_XXS :  2.06 bpw quantization
  20  or  IQ2_XS  :  2.31 bpw quantization
  28  or  IQ2_S   :  2.5  bpw quantization
  29  or  IQ2_M   :  2.7  bpw quantization
  24  or  IQ1_S   :  1.56 bpw quantization
  31  or  IQ1_M   :  1.75 bpw quantization
  36  or  TQ1_0   :  1.69 bpw ternarization
  37  or  TQ2_0   :  2.06 bpw ternarization
  10  or  Q2_K    :  2.96G, +3.5199 ppl @ Llama-3-8B
  21  or  Q2_K_S  :  2.96G, +3.1836 ppl @ Llama-3-8B
  23  or  IQ3_XXS :  3.06 bpw quantization
  26  or  IQ3_S   :  3.44 bpw quantization
  27  or  IQ3_M   :  3.66 bpw quantization mix
  12  or  Q3_K    : alias for Q3_K_M
  22  or  IQ3_XS  :  3.3 bpw quantization
  11  or  Q3_K_S  :  3.41G, +1.6321 ppl @ Llama-3-8B
  12  or  Q3_K_M  :  3.74G, +0.6569 ppl @ Llama-3-8B
  13  or  Q3_K_L  :  4.03G, +0.5562 ppl @ Llama-3-8B
  25  or  IQ4_NL  :  4.50 bpw non-linear quantization
  30  or  IQ4_XS  :  4.25 bpw non-linear quantization
  15  or  Q4_K    : alias for Q4_K_M
  14  or  Q4_K_S  :  4.37G, +0.2689 ppl @ Llama-3-8B
  15  or  Q4_K_M  :  4.58G, +0.1754 ppl @ Llama-3-8B
  17  or  Q5_K    : alias for Q5_K_M
  16  or  Q5_K_S  :  5.21G, +0.1049 ppl @ Llama-3-8B
  17  or  Q5_K_M  :  5.33G, +0.0569 ppl @ Llama-3-8B
  18  or  Q6_K    :  6.14G, +0.0217 ppl @ Llama-3-8B
   7  or  Q8_0    :  7.96G, +0.0026 ppl @ Llama-3-8B
   1  or  F16     : 14.00G, +0.0020 ppl @ Mistral-7B
  32  or  BF16    : 14.00G, -0.0050 ppl @ Mistral-7B
   0  or  F32     : 26.00G              @ 7B
          COPY    : only copy tensors, no quantizing 


F16 에서 Q8로 바꾸니 용량이 절반으로!

-rw-rw-r-- 1 minimonk minimonk  4977169088  4월 29 10:43 gemma-4-E4B-it-Q4_K_M.gguf

-rw-rw-r-- 1 minimonk minimonk 15053078208  6월  1 14:24 gguf.gguf
-rw-rw-r-- 1 minimonk minimonk  5335273152  6월  1 14:32 Q4_K_M.gguf
-rw-rw-r-- 1 minimonk minimonk  8031223488  6월  1 14:27 Q8.gguf


$ /mnt/Downloads/llama-b9305/llama-quantize  ./gguf.gguf ./Q8.gguf Q8_0
load_backend: loaded RPC backend from /mnt/Downloads/llama-b9305/libggml-rpc.so
ggml_vulkan: Found 3 Vulkan devices:
ggml_vulkan: 0 = Intel(R) UHD Graphics 630 (CFL GT2) (Intel open-source Mesa driver) | uma: 1 | fp16: 1 | bf16: 0 | warp size: 32 | shared memory: 65536 | int dot: 0 | matrix cores: none
ggml_vulkan: 1 = NVIDIA GeForce GTX 1080 Ti (NVIDIA) | uma: 0 | fp16: 0 | bf16: 0 | warp size: 32 | shared memory: 49152 | int dot: 1 | matrix cores: none
ggml_vulkan: 2 = NVIDIA GeForce GTX 1080 Ti (NVIDIA) | uma: 0 | fp16: 0 | bf16: 0 | warp size: 32 | shared memory: 49152 | int dot: 1 | matrix cores: none
load_backend: loaded Vulkan backend from /mnt/Downloads/llama-b9305/libggml-vulkan.so
load_backend: loaded CPU backend from /mnt/Downloads/llama-b9305/libggml-cpu-haswell.so
llama_print_build_info: build = 9305 (63248fc3e)
llama_print_build_info: built with GNU 11.4.0 for Linux x86_64
llama_quantize: quantizing './gguf.gguf' to './Q8.gguf' as Q8_0
llama_model_loader: loaded meta data with 37 key-value pairs and 720 tensors from ./gguf.gguf (version GGUF V3 (latest))
llama_model_loader: Dumping metadata keys/values. Note: KV overrides do not apply in this output.
llama_model_loader: - kv   0:                       general.architecture str              = gemma4
llama_model_loader: - kv   1:                               general.type str              = model
llama_model_loader: - kv   2:                               general.name str              = Google
llama_model_loader: - kv   3:                         general.size_label str              = 7.5B
llama_model_loader: - kv   4:                         gemma4.block_count u32              = 42
llama_model_loader: - kv   5:                      gemma4.context_length u32              = 131072
llama_model_loader: - kv   6:                    gemma4.embedding_length u32              = 2560
llama_model_loader: - kv   7:                 gemma4.feed_forward_length u32              = 10240
llama_model_loader: - kv   8:                gemma4.attention.head_count u32              = 8
llama_model_loader: - kv   9:             gemma4.attention.head_count_kv u32              = 2
llama_model_loader: - kv  10:                      gemma4.rope.freq_base f32              = 1000000.000000
llama_model_loader: - kv  11:                  gemma4.rope.freq_base_swa f32              = 10000.000000
llama_model_loader: - kv  12:    gemma4.attention.layer_norm_rms_epsilon f32              = 0.000001
llama_model_loader: - kv  13:                gemma4.attention.key_length u32              = 512
llama_model_loader: - kv  14:              gemma4.attention.value_length u32              = 512
llama_model_loader: - kv  15:                          general.file_type u32              = 1
llama_model_loader: - kv  16:             gemma4.final_logit_softcapping f32              = 30.000000
llama_model_loader: - kv  17:            gemma4.attention.sliding_window u32              = 512
llama_model_loader: - kv  18:          gemma4.attention.shared_kv_layers u32              = 18
llama_model_loader: - kv  19:    gemma4.embedding_length_per_layer_input u32              = 256
llama_model_loader: - kv  20:    gemma4.attention.sliding_window_pattern arr[bool,42]     = [true, true, true, true, true, false,...
llama_model_loader: - kv  21:            gemma4.attention.key_length_swa u32              = 256
llama_model_loader: - kv  22:          gemma4.attention.value_length_swa u32              = 256
llama_model_loader: - kv  23:                gemma4.rope.dimension_count u32              = 512
llama_model_loader: - kv  24:            gemma4.rope.dimension_count_swa u32              = 256
llama_model_loader: - kv  25:               general.quantization_version u32              = 2
llama_model_loader: - kv  26:                       tokenizer.ggml.model str              = gemma4
llama_model_loader: - kv  27:                      tokenizer.ggml.tokens arr[str,262144]  = ["<pad>", "<eos>", "<bos>", "<unk>", ...
llama_model_loader: - kv  28:                      tokenizer.ggml.scores arr[f32,262144]  = [-1000.000000, -1000.000000, -1000.00...
llama_model_loader: - kv  29:                  tokenizer.ggml.token_type arr[i32,262144]  = [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, ...
llama_model_loader: - kv  30:                      tokenizer.ggml.merges arr[str,514906]  = ["\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n \n", ...
llama_model_loader: - kv  31:                tokenizer.ggml.bos_token_id u32              = 2
llama_model_loader: - kv  32:                tokenizer.ggml.eos_token_id u32              = 1
llama_model_loader: - kv  33:            tokenizer.ggml.padding_token_id u32              = 0
llama_model_loader: - kv  34:               tokenizer.ggml.add_bos_token bool             = true
llama_model_loader: - kv  35:               tokenizer.ggml.add_sep_token bool             = false
llama_model_loader: - kv  36:            tokenizer.ggml.add_space_prefix bool             = false
llama_model_loader: - type  f32:  339 tensors
llama_model_loader: - type  f16:  381 tensors

/// 여기 생략됨 

llama_model_quantize_impl: model size  = 14340.66 MiB (16.00 BPW)
llama_model_quantize_impl: quant size  =  7644.10 MiB (8.53 BPW)

llama_quantize: quantize time = 99905.90 ms
llama_quantize:    total time = 99905.90 ms


더보기

[   1/ 720] output_norm.weight                   - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[   2/ 720] per_layer_model_proj.weight          - [  2560,  10752,      1,      1], type =    f16, size =   52.500 MiB
[   3/ 720] per_layer_proj_norm.weight           - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[   4/ 720] per_layer_token_embd.weight          - [ 10752, 262144,      1,      1], type =    f16, converting to q8_0 .. size =  5376.00 MiB ->  2856.00 MiB
[   5/ 720] rope_freqs.weight                    - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[   6/ 720] token_embd.weight                    - [  2560, 262144,      1,      1], type =    f16, converting to q8_0 .. size =  1280.00 MiB ->   680.00 MiB
[   7/ 720] blk.0.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[   8/ 720] blk.0.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[   9/ 720] blk.0.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  10/ 720] blk.0.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  11/ 720] blk.0.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  12/ 720] blk.0.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  13/ 720] blk.0.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  14/ 720] blk.0.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  15/ 720] blk.0.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  16/ 720] blk.0.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  17/ 720] blk.0.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  18/ 720] blk.0.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  19/ 720] blk.0.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[  20/ 720] blk.0.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  21/ 720] blk.0.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  22/ 720] blk.0.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  23/ 720] blk.0.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  24/ 720] blk.1.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  25/ 720] blk.1.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  26/ 720] blk.1.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  27/ 720] blk.1.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  28/ 720] blk.1.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  29/ 720] blk.1.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  30/ 720] blk.1.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  31/ 720] blk.1.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  32/ 720] blk.1.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  33/ 720] blk.1.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  34/ 720] blk.1.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  35/ 720] blk.1.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  36/ 720] blk.1.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[  37/ 720] blk.1.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  38/ 720] blk.1.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  39/ 720] blk.1.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  40/ 720] blk.1.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  41/ 720] blk.2.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  42/ 720] blk.2.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  43/ 720] blk.2.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  44/ 720] blk.2.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  45/ 720] blk.2.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  46/ 720] blk.2.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  47/ 720] blk.2.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  48/ 720] blk.2.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  49/ 720] blk.2.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  50/ 720] blk.2.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  51/ 720] blk.2.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  52/ 720] blk.2.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  53/ 720] blk.2.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[  54/ 720] blk.2.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  55/ 720] blk.2.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  56/ 720] blk.2.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  57/ 720] blk.2.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  58/ 720] blk.3.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  59/ 720] blk.3.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  60/ 720] blk.3.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  61/ 720] blk.3.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  62/ 720] blk.3.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  63/ 720] blk.3.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  64/ 720] blk.3.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  65/ 720] blk.3.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  66/ 720] blk.3.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  67/ 720] blk.3.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  68/ 720] blk.3.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  69/ 720] blk.3.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  70/ 720] blk.3.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[  71/ 720] blk.3.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  72/ 720] blk.3.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  73/ 720] blk.3.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  74/ 720] blk.3.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  75/ 720] blk.4.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  76/ 720] blk.4.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  77/ 720] blk.4.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  78/ 720] blk.4.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  79/ 720] blk.4.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[  80/ 720] blk.4.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[  81/ 720] blk.4.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[  82/ 720] blk.4.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  83/ 720] blk.4.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  84/ 720] blk.4.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  85/ 720] blk.4.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[  86/ 720] blk.4.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  87/ 720] blk.4.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[  88/ 720] blk.4.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  89/ 720] blk.4.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  90/ 720] blk.4.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  91/ 720] blk.4.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[  92/ 720] blk.5.attn_k.weight                  - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[  93/ 720] blk.5.attn_k_norm.weight             - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[  94/ 720] blk.5.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[  95/ 720] blk.5.attn_output.weight             - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[  96/ 720] blk.5.attn_q.weight                  - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[  97/ 720] blk.5.attn_q_norm.weight             - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[  98/ 720] blk.5.attn_v.weight                  - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[  99/ 720] blk.5.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 100/ 720] blk.5.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 101/ 720] blk.5.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 102/ 720] blk.5.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 103/ 720] blk.5.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 104/ 720] blk.5.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 105/ 720] blk.5.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 106/ 720] blk.5.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 107/ 720] blk.5.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 108/ 720] blk.5.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 109/ 720] blk.6.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 110/ 720] blk.6.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 111/ 720] blk.6.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 112/ 720] blk.6.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 113/ 720] blk.6.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 114/ 720] blk.6.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 115/ 720] blk.6.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 116/ 720] blk.6.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 117/ 720] blk.6.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 118/ 720] blk.6.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 119/ 720] blk.6.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 120/ 720] blk.6.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 121/ 720] blk.6.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 122/ 720] blk.6.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 123/ 720] blk.6.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 124/ 720] blk.6.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 125/ 720] blk.6.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 126/ 720] blk.7.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 127/ 720] blk.7.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 128/ 720] blk.7.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 129/ 720] blk.7.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 130/ 720] blk.7.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 131/ 720] blk.7.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 132/ 720] blk.7.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 133/ 720] blk.7.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 134/ 720] blk.7.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 135/ 720] blk.7.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 136/ 720] blk.7.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 137/ 720] blk.7.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 138/ 720] blk.7.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 139/ 720] blk.7.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 140/ 720] blk.7.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 141/ 720] blk.7.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 142/ 720] blk.7.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 143/ 720] blk.8.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 144/ 720] blk.8.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 145/ 720] blk.8.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 146/ 720] blk.8.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 147/ 720] blk.8.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 148/ 720] blk.8.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 149/ 720] blk.8.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 150/ 720] blk.8.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 151/ 720] blk.8.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 152/ 720] blk.8.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 153/ 720] blk.8.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 154/ 720] blk.8.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 155/ 720] blk.8.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 156/ 720] blk.8.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 157/ 720] blk.8.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 158/ 720] blk.8.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 159/ 720] blk.8.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 160/ 720] blk.9.attn_k.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 161/ 720] blk.9.attn_k_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 162/ 720] blk.9.attn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 163/ 720] blk.9.attn_output.weight             - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 164/ 720] blk.9.attn_q.weight                  - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 165/ 720] blk.9.attn_q_norm.weight             - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 166/ 720] blk.9.attn_v.weight                  - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 167/ 720] blk.9.ffn_down.weight                - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 168/ 720] blk.9.ffn_gate.weight                - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 169/ 720] blk.9.ffn_norm.weight                - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 170/ 720] blk.9.ffn_up.weight                  - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 171/ 720] blk.9.inp_gate.weight                - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 172/ 720] blk.9.layer_output_scale.weight      - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 173/ 720] blk.9.post_attention_norm.weight     - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 174/ 720] blk.9.post_ffw_norm.weight           - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 175/ 720] blk.9.post_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 176/ 720] blk.9.proj.weight                    - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 177/ 720] blk.10.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 178/ 720] blk.10.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 179/ 720] blk.10.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 180/ 720] blk.10.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 181/ 720] blk.10.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 182/ 720] blk.10.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 183/ 720] blk.10.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 184/ 720] blk.10.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 185/ 720] blk.10.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 186/ 720] blk.10.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 187/ 720] blk.10.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 188/ 720] blk.10.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 189/ 720] blk.10.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 190/ 720] blk.10.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 191/ 720] blk.10.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 192/ 720] blk.10.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 193/ 720] blk.10.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 194/ 720] blk.11.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 195/ 720] blk.11.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 196/ 720] blk.11.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 197/ 720] blk.11.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 198/ 720] blk.11.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 199/ 720] blk.11.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 200/ 720] blk.11.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 201/ 720] blk.11.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 202/ 720] blk.11.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 203/ 720] blk.11.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 204/ 720] blk.11.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 205/ 720] blk.11.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 206/ 720] blk.11.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 207/ 720] blk.11.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 208/ 720] blk.11.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 209/ 720] blk.11.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 210/ 720] blk.11.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 211/ 720] blk.12.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 212/ 720] blk.12.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 213/ 720] blk.12.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 214/ 720] blk.12.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 215/ 720] blk.12.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 216/ 720] blk.12.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 217/ 720] blk.12.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 218/ 720] blk.12.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 219/ 720] blk.12.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 220/ 720] blk.12.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 221/ 720] blk.12.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 222/ 720] blk.12.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 223/ 720] blk.12.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 224/ 720] blk.12.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 225/ 720] blk.12.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 226/ 720] blk.12.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 227/ 720] blk.12.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 228/ 720] blk.13.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 229/ 720] blk.13.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 230/ 720] blk.13.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 231/ 720] blk.13.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 232/ 720] blk.13.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 233/ 720] blk.13.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 234/ 720] blk.13.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 235/ 720] blk.13.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 236/ 720] blk.13.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 237/ 720] blk.13.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 238/ 720] blk.13.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 239/ 720] blk.13.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 240/ 720] blk.13.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 241/ 720] blk.13.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 242/ 720] blk.13.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 243/ 720] blk.13.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 244/ 720] blk.13.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 245/ 720] blk.14.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 246/ 720] blk.14.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 247/ 720] blk.14.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 248/ 720] blk.14.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 249/ 720] blk.14.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 250/ 720] blk.14.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 251/ 720] blk.14.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 252/ 720] blk.14.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 253/ 720] blk.14.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 254/ 720] blk.14.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 255/ 720] blk.14.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 256/ 720] blk.14.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 257/ 720] blk.14.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 258/ 720] blk.14.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 259/ 720] blk.14.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 260/ 720] blk.14.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 261/ 720] blk.14.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 262/ 720] blk.15.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 263/ 720] blk.15.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 264/ 720] blk.15.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 265/ 720] blk.15.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 266/ 720] blk.15.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 267/ 720] blk.15.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 268/ 720] blk.15.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 269/ 720] blk.15.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 270/ 720] blk.15.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 271/ 720] blk.15.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 272/ 720] blk.15.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 273/ 720] blk.15.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 274/ 720] blk.15.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 275/ 720] blk.15.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 276/ 720] blk.15.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 277/ 720] blk.15.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 278/ 720] blk.15.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 279/ 720] blk.16.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 280/ 720] blk.16.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 281/ 720] blk.16.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 282/ 720] blk.16.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 283/ 720] blk.16.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 284/ 720] blk.16.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 285/ 720] blk.16.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 286/ 720] blk.16.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 287/ 720] blk.16.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 288/ 720] blk.16.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 289/ 720] blk.16.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 290/ 720] blk.16.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 291/ 720] blk.16.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 292/ 720] blk.16.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 293/ 720] blk.16.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 294/ 720] blk.16.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 295/ 720] blk.16.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 296/ 720] blk.17.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 297/ 720] blk.17.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 298/ 720] blk.17.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 299/ 720] blk.17.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 300/ 720] blk.17.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 301/ 720] blk.17.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 302/ 720] blk.17.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 303/ 720] blk.17.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 304/ 720] blk.17.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 305/ 720] blk.17.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 306/ 720] blk.17.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 307/ 720] blk.17.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 308/ 720] blk.17.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 309/ 720] blk.17.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 310/ 720] blk.17.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 311/ 720] blk.17.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 312/ 720] blk.17.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 313/ 720] blk.18.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 314/ 720] blk.18.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 315/ 720] blk.18.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 316/ 720] blk.18.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 317/ 720] blk.18.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 318/ 720] blk.18.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 319/ 720] blk.18.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 320/ 720] blk.18.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 321/ 720] blk.18.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 322/ 720] blk.18.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 323/ 720] blk.18.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 324/ 720] blk.18.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 325/ 720] blk.18.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 326/ 720] blk.18.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 327/ 720] blk.18.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 328/ 720] blk.18.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 329/ 720] blk.18.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 330/ 720] blk.19.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 331/ 720] blk.19.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 332/ 720] blk.19.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 333/ 720] blk.19.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 334/ 720] blk.19.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 335/ 720] blk.19.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 336/ 720] blk.19.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 337/ 720] blk.19.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 338/ 720] blk.19.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 339/ 720] blk.19.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 340/ 720] blk.19.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 341/ 720] blk.19.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 342/ 720] blk.19.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 343/ 720] blk.19.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 344/ 720] blk.19.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 345/ 720] blk.19.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 346/ 720] blk.19.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 347/ 720] blk.20.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 348/ 720] blk.20.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 349/ 720] blk.20.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 350/ 720] blk.20.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 351/ 720] blk.20.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 352/ 720] blk.20.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 353/ 720] blk.20.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 354/ 720] blk.20.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 355/ 720] blk.20.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 356/ 720] blk.20.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 357/ 720] blk.20.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 358/ 720] blk.20.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 359/ 720] blk.20.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 360/ 720] blk.20.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 361/ 720] blk.20.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 362/ 720] blk.20.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 363/ 720] blk.20.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 364/ 720] blk.21.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 365/ 720] blk.21.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 366/ 720] blk.21.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 367/ 720] blk.21.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 368/ 720] blk.21.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 369/ 720] blk.21.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 370/ 720] blk.21.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 371/ 720] blk.21.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 372/ 720] blk.21.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 373/ 720] blk.21.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 374/ 720] blk.21.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 375/ 720] blk.21.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 376/ 720] blk.21.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 377/ 720] blk.21.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 378/ 720] blk.21.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 379/ 720] blk.21.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 380/ 720] blk.21.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 381/ 720] blk.22.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 382/ 720] blk.22.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 383/ 720] blk.22.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 384/ 720] blk.22.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 385/ 720] blk.22.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 386/ 720] blk.22.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 387/ 720] blk.22.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 388/ 720] blk.22.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 389/ 720] blk.22.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 390/ 720] blk.22.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 391/ 720] blk.22.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 392/ 720] blk.22.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 393/ 720] blk.22.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 394/ 720] blk.22.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 395/ 720] blk.22.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 396/ 720] blk.22.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 397/ 720] blk.22.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 398/ 720] blk.23.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 399/ 720] blk.23.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 400/ 720] blk.23.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 401/ 720] blk.23.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 402/ 720] blk.23.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 403/ 720] blk.23.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 404/ 720] blk.23.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 405/ 720] blk.23.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 406/ 720] blk.23.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 407/ 720] blk.23.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 408/ 720] blk.23.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 409/ 720] blk.23.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 410/ 720] blk.23.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 411/ 720] blk.23.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 412/ 720] blk.23.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 413/ 720] blk.23.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 414/ 720] blk.23.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 415/ 720] blk.24.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 416/ 720] blk.24.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 417/ 720] blk.24.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 418/ 720] blk.24.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 419/ 720] blk.24.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 420/ 720] blk.24.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 421/ 720] blk.24.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 422/ 720] blk.24.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 423/ 720] blk.24.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 424/ 720] blk.24.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 425/ 720] blk.24.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 426/ 720] blk.24.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 427/ 720] blk.24.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 428/ 720] blk.24.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 429/ 720] blk.24.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 430/ 720] blk.24.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 431/ 720] blk.24.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 432/ 720] blk.25.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 433/ 720] blk.25.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 434/ 720] blk.25.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 435/ 720] blk.25.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 436/ 720] blk.25.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 437/ 720] blk.25.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 438/ 720] blk.25.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 439/ 720] blk.25.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 440/ 720] blk.25.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 441/ 720] blk.25.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 442/ 720] blk.25.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 443/ 720] blk.25.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 444/ 720] blk.25.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 445/ 720] blk.25.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 446/ 720] blk.25.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 447/ 720] blk.25.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 448/ 720] blk.25.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 449/ 720] blk.26.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 450/ 720] blk.26.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 451/ 720] blk.26.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 452/ 720] blk.26.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 453/ 720] blk.26.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 454/ 720] blk.26.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 455/ 720] blk.26.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 456/ 720] blk.26.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 457/ 720] blk.26.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 458/ 720] blk.26.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 459/ 720] blk.26.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 460/ 720] blk.26.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 461/ 720] blk.26.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 462/ 720] blk.26.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 463/ 720] blk.26.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 464/ 720] blk.26.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 465/ 720] blk.26.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 466/ 720] blk.27.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 467/ 720] blk.27.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 468/ 720] blk.27.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 469/ 720] blk.27.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 470/ 720] blk.27.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 471/ 720] blk.27.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 472/ 720] blk.27.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 473/ 720] blk.27.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 474/ 720] blk.27.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 475/ 720] blk.27.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 476/ 720] blk.27.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 477/ 720] blk.27.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 478/ 720] blk.27.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 479/ 720] blk.27.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 480/ 720] blk.27.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 481/ 720] blk.27.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 482/ 720] blk.27.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 483/ 720] blk.28.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 484/ 720] blk.28.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 485/ 720] blk.28.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 486/ 720] blk.28.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 487/ 720] blk.28.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 488/ 720] blk.28.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 489/ 720] blk.28.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 490/ 720] blk.28.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 491/ 720] blk.28.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 492/ 720] blk.28.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 493/ 720] blk.28.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 494/ 720] blk.28.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 495/ 720] blk.28.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 496/ 720] blk.28.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 497/ 720] blk.28.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 498/ 720] blk.28.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 499/ 720] blk.28.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 500/ 720] blk.29.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 501/ 720] blk.29.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 502/ 720] blk.29.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 503/ 720] blk.29.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 504/ 720] blk.29.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 505/ 720] blk.29.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 506/ 720] blk.29.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 507/ 720] blk.29.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 508/ 720] blk.29.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 509/ 720] blk.29.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 510/ 720] blk.29.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 511/ 720] blk.29.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 512/ 720] blk.29.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 513/ 720] blk.29.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 514/ 720] blk.29.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 515/ 720] blk.29.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 516/ 720] blk.29.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 517/ 720] blk.30.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 518/ 720] blk.30.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 519/ 720] blk.30.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 520/ 720] blk.30.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 521/ 720] blk.30.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 522/ 720] blk.30.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 523/ 720] blk.30.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 524/ 720] blk.30.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 525/ 720] blk.30.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 526/ 720] blk.30.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 527/ 720] blk.30.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 528/ 720] blk.30.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 529/ 720] blk.30.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 530/ 720] blk.30.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 531/ 720] blk.30.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 532/ 720] blk.30.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 533/ 720] blk.30.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 534/ 720] blk.31.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 535/ 720] blk.31.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 536/ 720] blk.31.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 537/ 720] blk.31.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 538/ 720] blk.31.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 539/ 720] blk.31.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 540/ 720] blk.31.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 541/ 720] blk.31.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 542/ 720] blk.31.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 543/ 720] blk.31.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 544/ 720] blk.31.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 545/ 720] blk.31.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 546/ 720] blk.31.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 547/ 720] blk.31.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 548/ 720] blk.31.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 549/ 720] blk.31.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 550/ 720] blk.31.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 551/ 720] blk.32.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 552/ 720] blk.32.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 553/ 720] blk.32.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 554/ 720] blk.32.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 555/ 720] blk.32.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 556/ 720] blk.32.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 557/ 720] blk.32.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 558/ 720] blk.32.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 559/ 720] blk.32.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 560/ 720] blk.32.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 561/ 720] blk.32.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 562/ 720] blk.32.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 563/ 720] blk.32.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 564/ 720] blk.32.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 565/ 720] blk.32.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 566/ 720] blk.32.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 567/ 720] blk.32.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 568/ 720] blk.33.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 569/ 720] blk.33.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 570/ 720] blk.33.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 571/ 720] blk.33.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 572/ 720] blk.33.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 573/ 720] blk.33.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 574/ 720] blk.33.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 575/ 720] blk.33.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 576/ 720] blk.33.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 577/ 720] blk.33.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 578/ 720] blk.33.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 579/ 720] blk.33.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 580/ 720] blk.33.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 581/ 720] blk.33.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 582/ 720] blk.33.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 583/ 720] blk.33.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 584/ 720] blk.33.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 585/ 720] blk.34.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 586/ 720] blk.34.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 587/ 720] blk.34.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 588/ 720] blk.34.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 589/ 720] blk.34.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 590/ 720] blk.34.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 591/ 720] blk.34.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 592/ 720] blk.34.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 593/ 720] blk.34.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 594/ 720] blk.34.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 595/ 720] blk.34.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 596/ 720] blk.34.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 597/ 720] blk.34.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 598/ 720] blk.34.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 599/ 720] blk.34.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 600/ 720] blk.34.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 601/ 720] blk.34.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 602/ 720] blk.35.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 603/ 720] blk.35.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 604/ 720] blk.35.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 605/ 720] blk.35.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 606/ 720] blk.35.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 607/ 720] blk.35.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 608/ 720] blk.35.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 609/ 720] blk.35.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 610/ 720] blk.35.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 611/ 720] blk.35.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 612/ 720] blk.35.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 613/ 720] blk.35.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 614/ 720] blk.35.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 615/ 720] blk.35.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 616/ 720] blk.35.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 617/ 720] blk.35.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 618/ 720] blk.35.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 619/ 720] blk.36.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 620/ 720] blk.36.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 621/ 720] blk.36.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 622/ 720] blk.36.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 623/ 720] blk.36.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 624/ 720] blk.36.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 625/ 720] blk.36.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 626/ 720] blk.36.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 627/ 720] blk.36.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 628/ 720] blk.36.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 629/ 720] blk.36.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 630/ 720] blk.36.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 631/ 720] blk.36.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 632/ 720] blk.36.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 633/ 720] blk.36.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 634/ 720] blk.36.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 635/ 720] blk.36.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 636/ 720] blk.37.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 637/ 720] blk.37.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 638/ 720] blk.37.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 639/ 720] blk.37.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 640/ 720] blk.37.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 641/ 720] blk.37.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 642/ 720] blk.37.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 643/ 720] blk.37.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 644/ 720] blk.37.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 645/ 720] blk.37.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 646/ 720] blk.37.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 647/ 720] blk.37.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 648/ 720] blk.37.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 649/ 720] blk.37.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 650/ 720] blk.37.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 651/ 720] blk.37.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 652/ 720] blk.37.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 653/ 720] blk.38.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 654/ 720] blk.38.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 655/ 720] blk.38.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 656/ 720] blk.38.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 657/ 720] blk.38.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 658/ 720] blk.38.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 659/ 720] blk.38.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 660/ 720] blk.38.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 661/ 720] blk.38.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 662/ 720] blk.38.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 663/ 720] blk.38.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 664/ 720] blk.38.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 665/ 720] blk.38.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 666/ 720] blk.38.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 667/ 720] blk.38.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 668/ 720] blk.38.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 669/ 720] blk.38.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 670/ 720] blk.39.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 671/ 720] blk.39.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 672/ 720] blk.39.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 673/ 720] blk.39.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 674/ 720] blk.39.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 675/ 720] blk.39.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 676/ 720] blk.39.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 677/ 720] blk.39.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 678/ 720] blk.39.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 679/ 720] blk.39.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 680/ 720] blk.39.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 681/ 720] blk.39.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 682/ 720] blk.39.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 683/ 720] blk.39.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 684/ 720] blk.39.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 685/ 720] blk.39.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 686/ 720] blk.39.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 687/ 720] blk.40.attn_k.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 688/ 720] blk.40.attn_k_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 689/ 720] blk.40.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 690/ 720] blk.40.attn_output.weight            - [  2048,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 691/ 720] blk.40.attn_q.weight                 - [  2560,   2048,      1,      1], type =    f16, converting to q8_0 .. size =    10.00 MiB ->     5.31 MiB
[ 692/ 720] blk.40.attn_q_norm.weight            - [   256,      1,      1,      1], type =    f32, size =    0.001 MiB
[ 693/ 720] blk.40.attn_v.weight                 - [  2560,    512,      1,      1], type =    f16, converting to q8_0 .. size =     2.50 MiB ->     1.33 MiB
[ 694/ 720] blk.40.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 695/ 720] blk.40.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 696/ 720] blk.40.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 697/ 720] blk.40.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 698/ 720] blk.40.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 699/ 720] blk.40.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 700/ 720] blk.40.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 701/ 720] blk.40.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 702/ 720] blk.40.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 703/ 720] blk.40.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 704/ 720] blk.41.attn_k.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 705/ 720] blk.41.attn_k_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 706/ 720] blk.41.attn_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 707/ 720] blk.41.attn_output.weight            - [  4096,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 708/ 720] blk.41.attn_q.weight                 - [  2560,   4096,      1,      1], type =    f16, converting to q8_0 .. size =    20.00 MiB ->    10.62 MiB
[ 709/ 720] blk.41.attn_q_norm.weight            - [   512,      1,      1,      1], type =    f32, size =    0.002 MiB
[ 710/ 720] blk.41.attn_v.weight                 - [  2560,   1024,      1,      1], type =    f16, converting to q8_0 .. size =     5.00 MiB ->     2.66 MiB
[ 711/ 720] blk.41.ffn_down.weight               - [ 10240,   2560,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 712/ 720] blk.41.ffn_gate.weight               - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 713/ 720] blk.41.ffn_norm.weight               - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 714/ 720] blk.41.ffn_up.weight                 - [  2560,  10240,      1,      1], type =    f16, converting to q8_0 .. size =    50.00 MiB ->    26.56 MiB
[ 715/ 720] blk.41.inp_gate.weight               - [  2560,    256,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB
[ 716/ 720] blk.41.layer_output_scale.weight     - [     1,      1,      1,      1], type =    f32, size =    0.000 MiB
[ 717/ 720] blk.41.post_attention_norm.weight    - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 718/ 720] blk.41.post_ffw_norm.weight          - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 719/ 720] blk.41.post_norm.weight              - [  2560,      1,      1,      1], type =    f32, size =    0.010 MiB
[ 720/ 720] blk.41.proj.weight                   - [   256,   2560,      1,      1], type =    f16, converting to q8_0 .. size =     1.25 MiB ->     0.66 MiB

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

llama.cpp reasoning 옵션  (0) 2026.06.01
torchvision model  (0) 2026.06.01
antigravity 2  (0) 2026.05.28
telegram bot api 로 기능 변경하기  (0) 2026.05.25
python huggingface 저장경로 변경하기  (0) 2026.05.24
Posted by 구차니

생각해보니 기존에 쓰던 버전도 몰랐네 -_-?


그래서 리눅스용 tar 파일 받고, 실행하는데 머.. 특별한건 없어 보인다.


로그인 하고


동의하고


뜬다.


소심하게 좌측상단 메뉴 옆에 Antigravity 누르면 버전 나오고 땡


테마 고르고


멀 할지 고르고(아무것도 선택안해도 넘어감)


짜잔~

이전에 작업했던 것들이 왼쪽에 쭈르륵 뜬다. 이건 좀 좋다고 해야하나 말아야 하나?


음.. 저번에 다 써먹었는데 이번에는 좀 쓸만한 양을 주려나?


근데, 우분투에서 패키지로 깐게 아니라

설치하는 경로에서 실행해줘야 해서 조금 귀찮다. 어떻게 데스크탑 아이콘 설정 바꾸지?


Exec 뒤에 경로를 적절히 조정해주면 된다.

$ cd ~/.local/share/applications
$ vi antigravity-ide.desktop
$ cat antigravity-ide.desktop
[Desktop Entry]
Name=Antigravity IDE
Comment=Antigravity IDE v2.0 - Experience liftoff
GenericName=IDE
Exec="/home/minimonk/Antigravity-x64/antigravity" %F
Icon=antigravity
Type=Application
Terminal=false
StartupNotify=true
StartupWMClass=Antigravity
Categories=Development;IDE;TextEditor;
MimeType=application/x-antigravity-workspace;
$ chmod +x antigravity-ide.desktop 
$ update-desktop-database ~/.local/share/applications/

[링크 : https://discuss.ai.google.dev/t/ubuntu-24-04-upgrading-to-antigravity-2-0-and-antigravity-ide/146516/4]

Posted by 구차니

그래서.. openclaw 에서 대화창 인증하고 나서 바로 메뉴가 추가되었던 건가..

그리고 set_my_commands() 로 등록되어도 채팅 내용으로 받아와지진 않는다.

다른 무슨 처리가 별도로 필요한 듯.


Bot settings

set_my_commands() Used for setting the list of commands
delete_my_commands() Used for deleting the list of commands
get_my_commands() Used for obtaining the list of commands
get_my_default_administrator_rights() Used for obtaining the default administrator rights for the bot
set_my_default_administrator_rights() Used for setting the default administrator rights for the bot
get_chat_menu_button() Used for obtaining the menu button of a private chat or the default menu button
set_chat_menu_button() Used for setting the menu button of a private chat or the default menu button
set_my_description() Used for setting the description of the bot
get_my_description() Used for obtaining the description of the bot
set_my_short_description() Used for setting the short description of the bot
get_my_short_description() Used for obtaining the short description of the bot
set_my_name() Used for setting the name of the bot
get_my_name() Used for obtaining the name of the bot
set_my_profile_photo() Used for setting the profile photo of the bot
remove_my_profile_photo() Used for removing the profile photo of the bot

[링크 : https://docs.python-telegram-bot.org/en/stable/telegram.bot.html]


봇 토큰으로 채팅내 메뉴 목록 보기

import asyncio
from telegram import Bot

async def check_bot_menu():
    # Replace with your actual Bot Token from @BotFather
    bot_token = "YOUR_BOT_TOKEN_HERE"
    bot = Bot(token=bot_token)
    
    print("Fetching active menu commands...")
    # Retrieves a list of BotCommand objects
    commands = await bot.get_my_commands()
    
    if not commands:
        print("No menu commands found. The menu is empty.")
    else:
        print(f"Found {len(commands)} command(s):")
        for cmd in commands:
            print(f"/{cmd.command} - {cmd.description}")

if __name__ == "__main__":
    asyncio.run(check_bot_menu())


봇 토큰으로 채팅내 메뉴 비우기

import asyncio
from telegram import Bot

async def remove_bot_menu():
    # Replace with your actual Bot Token from @BotFather
    bot_token = "YOUR_BOT_TOKEN_HERE"
    bot = Bot(token=bot_token)
    
    print("Removing all menu commands...")
    # Passing no arguments clears the commands globally
    await bot.delete_my_commands()
    print("Success! All menu commands have been removed.")

# Run the async function
if __name__ == "__main__":
    asyncio.run(remove_bot_menu())


봇 토큰과 채팅id를 이용해서 즉각적으로 메뉴 변경하기.

set_my_commands 로는 대화창을 나가도 바뀌지 않아서, 특정 채팅 아이디 넣어서야 바뀌게 되었음

import asyncio
from telegram import Bot, BotCommand, BotCommandScopeChat

async def force_update_user_menu():
    # 1. 봇 토큰과 대상 유저의 Chat ID를 입력하세요.
    BOT_TOKEN = "YOUR_BOT_TOKEN_HERE"
    USER_CHAT_ID = 123456789  # 숫자로 된 유저의 chat_id 입력
    
    bot = Bot(token=BOT_TOKEN)
    
    # 2. 변경하고 싶은 새로운 메뉴 목록을 정의합니다.
    new_commands = [
        BotCommand(command="home", description="🏠 홈 화면으로"),
        BotCommand(command="mypage", description="👤 내 정보 보기"),
        BotCommand(command="support", description="❓ 고객 센터")
    ]
    
    print(f"User({USER_CHAT_ID})의 메뉴를 즉시 변경합니다...")
    
    # 3. scope를 'BotCommandScopeChat'으로 지정하여 특정 chat_id에 즉시 강제 적용
    await bot.set_my_commands(
        commands=new_commands,
        scope=BotCommandScopeChat(chat_id=USER_CHAT_ID)
    )
    
    print("성공! 해당 유저의 텔레그램 앱 화면에서 메뉴가 즉시 업데이트되었습니다.")

if __name__ == "__main__":
    asyncio.run(force_update_user_menu())


요건 아직 테스트 안해봄

from telegram import Update, BotCommand, BotCommandScopeChat
from telegram.ext import Application, CommandHandler, ContextTypes

# 봇 토큰 설정
BOT_TOKEN = "YOUR_BOT_TOKEN_HERE"

# 1. /start 명령어가 들어왔을 때 실행될 함수 (여기서 메뉴를 즉시 변경)
async def start_command(update: Update, context: ContextTypes.DEFAULT_TYPE):
    chat_id = update.effective_chat.id
    
    # 해당 유저의 화면에 보일 새로운 메뉴 정의
    new_menu = [
        BotCommand(command="home", description="🏠 홈 화면으로"),
        BotCommand(command="mypage", description="👤 내 정보 보기")
    ]
    
    # 유저 화면의 메뉴 버튼 즉시 업데이트
    await context.bot.set_my_commands(
        commands=new_menu,
        scope=BotCommandScopeChat(chat_id=chat_id)
    )
    
    await update.message.reply_text(
        "반갑습니다! 메뉴 버튼이 업데이트되었습니다.\n"
        "좌측 하단의 [Menu] 버튼을 누르거나 명령어를 입력해보세요!"
    )

# 2. 메뉴 버튼의 /home 처리를 위한 핸들러 함수
async def home_command(update: Update, context: ContextTypes.DEFAULT_TYPE):
    await update.message.reply_text("🏠 홈 화면으로 이동했습니다.")

# 3. 메뉴 버튼의 /mypage 처리를 위한 핸들러 함수
async def mypage_command(update: Update, context: ContextTypes.DEFAULT_TYPE):
    user = update.effective_user
    await update.message.reply_text(f"👤 [{user.first_name}] 님의 마이페이지입니다.")


def main():
    # 애플리케이션 빌드
    application = Application.builder().token(BOT_TOKEN).build()

    # ⭐ [핵심] 메뉴에 추가한 명령어들과 핸들러 함수를 1:1로 매핑해줍니다.
    application.add_handler(CommandHandler("start", start_command))
    application.add_handler(CommandHandler("home", home_command))       # /home 처리
    application.add_handler(CommandHandler("mypage", mypage_command))   # /mypage 처리

    # 봇 시작 (폴링 방식)
    print("봇이 시작되었습니다. 대화를 시작하세요...")
    application.run_polling()

if __name__ == "__main__":
    main()
Posted by 구차니

HF_HOME 환경 변수를 바꿔주면 된다고

리눅스에서는 기본값 ~/.cache/huggingface

[링크 : https://developer0hye.tistory.com/775]

Posted by 구차니

실행하라면 이렇게 하라고 하는데

vllm serve google/gemma-4-E4B-it \
  --max-model-len <n_of_tokens> # up to 131072

[링크 : https://docs.vllm.ai/projects/recipes/en/latest/Google/Gemma4.html]


아따.. 드럽게 크네. 그나저나 허깅페이스에서 바로 받으려나?

그리고 gguf가 양자화 되서 작은거였나. 기존에 내가 쓰던데 Q4_K_M 이라 4.7기가 정도 되었는데

model.safetensors는 16기가나 된다. 와우

[링크 : https://huggingface.co/google/gemma-4-E4B]


vllm : 1080 ti 라니 불량식품이잖아! 퉤!

$ vllm serve google/gemma-4-E4B-it
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]        █     █     █▄   ▄█
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]  ▄▄ ▄█ █     █     █ ▀▄▀ █  version 0.21.0
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]   █▄█▀ █     █     █     █  model   google/gemma-4-E4B-it
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]    ▀▀  ▀▀▀▀▀ ▀▀▀▀▀ ▀     ▀
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:306]
(APIServer pid=52696) INFO 05-24 22:20:19 [utils.py:240] non-default args: {'model_tag': 'google/gemma-4-E4B-it', 'model': 'google/gemma-4-E4B-it'}
(APIServer pid=52696) Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
config.json: 5.14kB [00:00, 17.7MB/s]
processor_config.json: 1.69kB [00:00, 1.70MB/s]
(APIServer pid=52696) INFO 05-24 22:20:29 [model.py:568] Resolved architecture: Gemma4ForConditionalGeneration
(APIServer pid=52696) WARNING 05-24 22:20:29 [model.py:1982] Your device 'NVIDIA GeForce GTX 1080 Ti' (with compute capability 6.1) doesn't support torch.bfloat16. Falling back to torch.float16 for compatibility.
(APIServer pid=52696) WARNING 05-24 22:20:29 [model.py:2035] Casting torch.bfloat16 to torch.float16.
(APIServer pid=52696) INFO 05-24 22:20:29 [model.py:1697] Using max model len 131072
(APIServer pid=52696) INFO 05-24 22:20:29 [config.py:101] Gemma4 model has heterogeneous head dimensions (head_dim=256, global_head_dim=512). Forcing TRITON_ATTN backend to prevent mixed-backend numerical divergence.
(APIServer pid=52696) INFO 05-24 22:20:29 [vllm.py:886] Asynchronous scheduling is enabled.
(APIServer pid=52696) INFO 05-24 22:20:29 [kernel.py:212] Final IR op priority after setting platform defaults: IrOpPriorityConfig(rms_norm=['native'], fused_add_rms_norm=['native'])
tokenizer_config.json: 2.10kB [00:00, 2.05MB/s]
tokenizer.json: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 32.2M/32.2M [00:02<00:00, 14.8MB/s]
chat_template.jinja: 17.3kB [00:00, 12.6MB/s]
generation_config.json: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 208/208 [00:00<00:00, 1.68MB/s]
(EngineCore pid=52767) INFO 05-24 22:21:24 [core.py:109] Initializing a V1 LLM engine (v0.21.0) with config: model='google/gemma-4-E4B-it', speculative_config=None, tokenizer='google/gemma-4-E4B-it', skip_t
okenizer_init=False, tokenizer_mode=auto, revision=None, tokenizer_revision=None, trust_remote_code=False, dtype=torch.float16, max_seq_len=131072, download_dir=None, load_format=auto, tensor_parallel_size=
1, pipeline_parallel_size=1, data_parallel_size=1, decode_context_parallel_size=1, dcp_comm_backend=ag_rs, disable_custom_all_reduce=False, quantization=None, quantization_config=None, enforce_eager=False,
enable_return_routed_experts=False, kv_cache_dtype=auto, device_config=cuda, structured_outputs_config=StructuredOutputsConfig(backend='auto', disable_any_whitespace=False, disable_additional_properties=Fal
se, reasoning_parser='', reasoning_parser_plugin='', enable_in_reasoning=False), observability_config=ObservabilityConfig(show_hidden_metrics_for_version=None, otlp_traces_endpoint=None, collect_detailed_tr
aces=None, kv_cache_metrics=False, kv_cache_metrics_sample=0.01, cudagraph_metrics=False, enable_layerwise_nvtx_tracing=False, enable_mfu_metrics=False, enable_mm_processor_stats=False, enable_logging_itera
tion_details=False), seed=0, served_model_name=google/gemma-4-E4B-it, enable_prefix_caching=True, enable_chunked_prefill=True, pooler_config=None, compilation_config={'mode': <CompilationMode.VLLM_COMPILE:
3>, 'debug_dump_path': None, 'cache_dir': '', 'compile_cache_save_format': 'binary', 'backend': 'inductor', 'custom_ops': ['none'], 'ir_enable_torch_wrap': True, 'splitting_ops': ['vllm::unified_attention_w
ith_output', 'vllm::unified_mla_attention_with_output', 'vllm::mamba_mixer2', 'vllm::mamba_mixer', 'vllm::short_conv', 'vllm::linear_attention', 'vllm::plamo2_mamba_mixer', 'vllm::gdn_attention_core', 'vllm
::gdn_attention_core_xpu', 'vllm::olmo_hybrid_gdn_full_forward', 'vllm::kda_attention', 'vllm::sparse_attn_indexer', 'vllm::rocm_aiter_sparse_attn_indexer', 'vllm::deepseek_v4_attention', 'vllm::unified_kv_
cache_update', 'vllm::unified_mla_kv_cache_update'], 'compile_mm_encoder': False, 'cudagraph_mm_encoder': False, 'encoder_cudagraph_token_budgets': [], 'encoder_cudagraph_max_vision_items_per_batch': 0, 'en
coder_cudagraph_max_frames_per_batch': None, 'compile_sizes': [], 'compile_ranges_endpoints': [2048], 'inductor_compile_config': {'enable_auto_functionalized_v2': False, 'size_asserts': False, 'alignment_as
serts': False, 'scalar_asserts': False, 'combo_kernels': True, 'benchmark_combo_kernel': True}, 'inductor_passes': {}, 'cudagraph_mode': <CUDAGraphMode.FULL_AND_PIECEWISE: (2, 1)>, 'cudagraph_num_of_warmups
': 1, 'cudagraph_capture_sizes': [1, 2, 4, 8, 16, 24, 32, 40, 48, 56, 64, 72, 80, 88, 96, 104, 112, 120, 128, 136, 144, 152, 160, 168, 176, 184, 192, 200, 208, 216, 224, 232, 240, 248, 256, 272, 288, 304, 3
20, 336, 352, 368, 384, 400, 416, 432, 448, 464, 480, 496, 512], 'cudagraph_copy_inputs': False, 'cudagraph_specialize_lora': True, 'use_inductor_graph_partition': False, 'pass_config': {'fuse_norm_quant':
False, 'fuse_act_quant': False, 'fuse_attn_quant': False, 'enable_sp': False, 'fuse_gemm_comms': False, 'fuse_allreduce_rms': False, 'fuse_act_padding': False}, 'max_cudagraph_capture_size': 512, 'dynamic_s
hapes_config': {'type': <DynamicShapesType.BACKED: 'backed'>, 'evaluate_guards': False, 'assume_32_bit_indexing': False}, 'local_cache_dir': None, 'fast_moe_cold_start': False, 'static_all_moe_layers': []},
 kernel_config=KernelConfig(ir_op_priority=IrOpPriorityConfig(rms_norm=['native'], fused_add_rms_norm=['native']), enable_flashinfer_autotune=False, moe_backend='auto')
(EngineCore pid=52767) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:371: UserWarning: Found GPU0 NVIDIA GeForce GTX 1080 Ti which is of compute capability (CC) 6.1.
(EngineCore pid=52767) The following list shows the CCs this version of PyTorch was built for and the hardware CCs it supports:
(EngineCore pid=52767) - 7.5 which supports hardware CC >=7.5,<8.0
(EngineCore pid=52767) - 8.0 which supports hardware CC >=8.0,<9.0 except {8.7}
(EngineCore pid=52767) - 8.6 which supports hardware CC >=8.6,<9.0 except {8.7}
(EngineCore pid=52767) - 9.0 which supports hardware CC >=9.0,<10.0
(EngineCore pid=52767) - 8.6 which supports hardware CC >=8.6,<9.0 except {8.7}                                                                                                                      [108/299]
(EngineCore pid=52767) - 9.0 which supports hardware CC >=9.0,<10.0
(EngineCore pid=52767) - 10.0 which supports hardware CC >=10.0,<11.0 except {10.1}
(EngineCore pid=52767) - 12.0 which supports hardware CC >=12.0,<13.0
(EngineCore pid=52767) Please follow the instructions at https://pytorch.org/get-started/locally/ to install a PyTorch release that supports one of these CUDA versions: 12.6
(EngineCore pid=52767)   _warn_unsupported_code(d, device_cc, code_ccs)
(EngineCore pid=52767) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:371: UserWarning: Found GPU1 NVIDIA GeForce GTX 1080 Ti which is of compute capability (CC) 6.1.
(EngineCore pid=52767) The following list shows the CCs this version of PyTorch was built for and the hardware CCs it supports:
(EngineCore pid=52767) - 7.5 which supports hardware CC >=7.5,<8.0                                                                                                                                            (EngineCore pid=52767) - 8.0 which supports hardware CC >=8.0,<9.0 except {8.7}
(EngineCore pid=52767) - 8.6 which supports hardware CC >=8.6,<9.0 except {8.7}
(EngineCore pid=52767) - 9.0 which supports hardware CC >=9.0,<10.0
(EngineCore pid=52767) - 10.0 which supports hardware CC >=10.0,<11.0 except {10.1}
(EngineCore pid=52767) - 12.0 which supports hardware CC >=12.0,<13.0
(EngineCore pid=52767) Please follow the instructions at https://pytorch.org/get-started/locally/ to install a PyTorch release that supports one of these CUDA versions: 12.6
(EngineCore pid=52767)   _warn_unsupported_code(d, device_cc, code_ccs)
(EngineCore pid=52767) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:489: UserWarning:
(EngineCore pid=52767) NVIDIA GeForce GTX 1080 Ti with CUDA capability sm_61 is not compatible with the current PyTorch installation.
(EngineCore pid=52767) The current PyTorch install supports CUDA capabilities sm_75 sm_80 sm_86 sm_90 sm_100 sm_120.
(EngineCore pid=52767) If you want to use the NVIDIA GeForce GTX 1080 Ti GPU with PyTorch, please check the instructions at https://pytorch.org/get-started/locally/
(EngineCore pid=52767)
(EngineCore pid=52767)   queued_call()
(EngineCore pid=52767) INFO 05-24 22:21:30 [parallel_state.py:1410] world_size=1 rank=0 local_rank=0 distributed_init_method=tcp://192.168.40.238:47913 backend=nccl
(EngineCore pid=52767) INFO 05-24 22:21:30 [parallel_state.py:1723] rank 0 in world size 1 is assigned as DP rank 0, PP rank 0, PCP rank 0, TP rank 0, EP rank N/A, EPLB rank N/A
(EngineCore pid=52767) WARNING 05-24 22:21:31 [topk_topp_sampler.py:61] FlashInfer top-p/top-k sampling not supported on compute capability 6.1; falling back to PyTorch-native sampler. Set VLLM_USE_FLASHINF
ER_SAMPLER=0 to silence.
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] EngineCore failed to start.
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] Traceback (most recent call last):
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1114, in run_engine_core
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     engine_core = EngineCoreProc(*args, engine_index=dp_rank, **kwargs)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 880, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     super().__init__(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 118, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.model_executor = executor_class(vllm_config)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/abstract.py", line 109, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self._init_executor()
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/uniproc_executor.py", line 60, in _init_executor
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.driver_worker.init_device()
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/worker_base.py", line 317, in init_device
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.worker.init_device()  # type: ignore
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_worker.py", line 330, in init_device
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.model_runner = GPUModelRunnerV1(self.vllm_config, self.device)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_model_runner.py", line 629, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.input_batch = InputBatch(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_input_batch.py", line 171, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.block_table = MultiGroupBlockTable(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 267, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.block_tables = [
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 268, in <listcomp>
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     BlockTable(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 268, in <listcomp>                          [54/299]
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     BlockTable(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 70, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.block_table = self._make_buffer(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 218, in _make_buffer
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     return CpuGpuBuffer(
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/utils.py", line 120, in __init__
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]     self.gpu = torch.zeros_like(self.cpu, device=device)
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] torch.AcceleratorError: CUDA error: no kernel image is available for execution on the device                                                       
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] Search for `cudaErrorNoKernelImageForDevice' in https://docs.nvidia.com/cuda/cuda-runtime-api/group__CUDART__TYPES.html for more information.
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] For debugging consider passing CUDA_LAUNCH_BLOCKING=1
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140] Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
(EngineCore pid=52767) ERROR 05-24 22:21:32 [core.py:1140]
(EngineCore pid=52767) Process EngineCore:
(EngineCore pid=52767) Traceback (most recent call last):
(EngineCore pid=52767)   File "/usr/lib/python3.10/multiprocessing/process.py", line 314, in _bootstrap
(EngineCore pid=52767)     self.run()
(EngineCore pid=52767)   File "/usr/lib/python3.10/multiprocessing/process.py", line 108, in run
(EngineCore pid=52767)     self._target(*self._args, **self._kwargs)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1144, in run_engine_core
(EngineCore pid=52767)     raise e
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1114, in run_engine_core
(EngineCore pid=52767)     engine_core = EngineCoreProc(*args, engine_index=dp_rank, **kwargs)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767)     return func(*args, **kwargs)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 880, in __init__
(EngineCore pid=52767)     super().__init__(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 118, in __init__
(EngineCore pid=52767)     self.model_executor = executor_class(vllm_config)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767)     return func(*args, **kwargs)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/abstract.py", line 109, in __init__
(EngineCore pid=52767)     self._init_executor()
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/uniproc_executor.py", line 60, in _init_executor
(EngineCore pid=52767)     self.driver_worker.init_device()
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/worker_base.py", line 317, in init_device
(EngineCore pid=52767)     self.worker.init_device()  # type: ignore
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=52767)     return func(*args, **kwargs)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_worker.py", line 330, in init_device
(EngineCore pid=52767)     self.model_runner = GPUModelRunnerV1(self.vllm_config, self.device)
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_model_runner.py", line 629, in __init__
(EngineCore pid=52767)     self.input_batch = InputBatch(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_input_batch.py", line 171, in __init__
(EngineCore pid=52767)     self.block_table = MultiGroupBlockTable(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 267, in __init__
(EngineCore pid=52767)     self.block_tables = [
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 268, in <listcomp>
(EngineCore pid=52767)     BlockTable(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 70, in __init__
(EngineCore pid=52767)     self.block_table = self._make_buffer(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 218, in _make_buffer
(EngineCore pid=52767)     return CpuGpuBuffer(
(EngineCore pid=52767)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/utils.py", line 120, in __init__
(EngineCore pid=52767)     self.gpu = torch.zeros_like(self.cpu, device=device)
(EngineCore pid=52767) torch.AcceleratorError: CUDA error: no kernel image is available for execution on the device
(EngineCore pid=52767) Search for `cudaErrorNoKernelImageForDevice' in https://docs.nvidia.com/cuda/cuda-runtime-api/group__CUDART__TYPES.html for more information.
(EngineCore pid=52767) CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
(EngineCore pid=52767) For debugging consider passing CUDA_LAUNCH_BLOCKING=1
(EngineCore pid=52767) Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
(EngineCore pid=52767)
[rank0]:[W524 22:21:32.199264489 ProcessGroupNCCL.cpp:1575] Warning: WARNING: destroy_process_group() was not called before program exit, which can leak resources. For more info, please see https://pytorch.
org/docs/stable/distributed.html#shutdown (function operator())
(APIServer pid=52696) Traceback (most recent call last):
(APIServer pid=52696)   File "/home/minimonk/.local/bin/vllm", line 8, in <module>
(APIServer pid=52696)     sys.exit(main())
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/cli/main.py", line 92, in main
(APIServer pid=52696)     args.dispatch_function(args)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/cli/serve.py", line 122, in cmd
(APIServer pid=52696)     uvloop.run(run_server(args))
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/uvloop/__init__.py", line 69, in run
(APIServer pid=52696)     return loop.run_until_complete(wrapper())
(APIServer pid=52696)   File "uvloop/loop.pyx", line 1518, in uvloop.loop.Loop.run_until_complete
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/uvloop/__init__.py", line 48, in wrapper
(APIServer pid=52696)     return await main
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 693, in run_server
(APIServer pid=52696)     await run_server_worker(listen_address, sock, args, **uvicorn_kwargs)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 707, in run_server_worker
(APIServer pid=52696)     async with build_async_engine_client(
(APIServer pid=52696)   File "/usr/lib/python3.10/contextlib.py", line 199, in __aenter__
(APIServer pid=52696)     return await anext(self.gen)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 100, in build_async_engine_client
(APIServer pid=52696)     async with build_async_engine_client_from_engine_args(
(APIServer pid=52696)   File "/usr/lib/python3.10/contextlib.py", line 199, in __aenter__
(APIServer pid=52696)     return await anext(self.gen)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 136, in build_async_engine_client_from_engine_args
(APIServer pid=52696)     async_llm = AsyncLLM.from_vllm_config(
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/async_llm.py", line 217, in from_vllm_config
(APIServer pid=52696)     return cls(
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/async_llm.py", line 146, in __init__
(APIServer pid=52696)     self.engine_core = EngineCoreClient.make_async_mp_client(
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(APIServer pid=52696)     return func(*args, **kwargs)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 130, in make_async_mp_client
(APIServer pid=52696)     return AsyncMPClient(*client_args)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(APIServer pid=52696)     return func(*args, **kwargs)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 900, in __init__
(APIServer pid=52696)     super().__init__(
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 535, in __init__
(APIServer pid=52696)     with launch_core_engines(
(APIServer pid=52696)   File "/usr/lib/python3.10/contextlib.py", line 142, in __exit__
(APIServer pid=52696)     next(self.gen)
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/utils.py", line 1128, in launch_core_engines
(APIServer pid=52696)     wait_for_engine_startup(
(APIServer pid=52696)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/utils.py", line 1187, in wait_for_engine_startup
(APIServer pid=52696)     raise RuntimeError(
(APIServer pid=52696) RuntimeError: Engine core initialization failed. See root cause above. Failed core proc(s): {}


파스칼은 아예 지원 하드웨어에서 빼버린건가?

[링크 : https://docs.vllm.ai/en/latest/features/quantization/]


fork로 이런것도 존재하는데, 아래 pascal-pkgs-ci로 대체 된다고

[링크 : https://github.com/cduk/vllm-pascal]


도커로 시도해야하나..

[링크 : https://github.com/sasha0552/pascal-pkgs-ci]

    [링크 : https://github.com/vllm-project/vllm/issues/19542]


위의 도커를 불러오게 하면되려나? 볼륨은 로컬 캐싱에서 HF_HOME 으로 변경해주면 좋을듯

docker run -itd --name gemma4 \
    --ipc=host \
    --network host \
    --shm-size 16G \
    --gpus all \
    -v ~/.cache/huggingface:/root/.cache/huggingface \
    vllm/vllm-openai:latest \
        --model google/gemma-4-31B-it \
        --tensor-parallel-size 2 \
        --max-model-len 32768 \
        --gpu-memory-utilization 0.90 \
        --host 0.0.0.0 \
        --port 8000

[링크 : https://docs.vllm.ai/projects/recipes/en/latest/Google/Gemma4.html#docker-deployment]


아래와 같이 도커에서 그래픽 카드를 인식하지 못하면

docker: Error response from daemon: could not select device driver "" with capabilities: [[gpu]]


nvidia-container-toolkit을 설치하고 도커를 재기동하면 된단다

$ distribution=$(. /etc/os-release;echo $ID$VERSION_ID)    && curl -s -L https://nvidia.github.io/nvidia-docker/gpgkey | sudo apt-key add -    && curl -s -L https://nvidia.github.io/nvidia-docker/$distribution/nvidia-docker.list | sudo tee /etc/apt/sources.list.d/nvidia-docker.list
$ sudo apt-get update && sudo apt-get install -y nvidia-container-toolkit
$ sudo systemctl restart docker

[링크 : https://bluecolorsky.tistory.com/110]


docker run -itd --name gemma4 \
    --ipc=host \
    --network host \
    --gpus all \
    -v /mnt/huggingface:/root/.cache/huggingface \
    ghcr.io/sasha0552/vllm\
        --model google/gemma-4-e4b-it \
        --tensor-parallel-size 2 \
        --max-model-len 131072\
        --gpu-memory-utilization 0.90 \
        --host 0.0.0.0 \
        --port 8000

[링크 : https://github.com/sasha0552/pascal-pkgs-ci/pkgs/container/vllm]


에라모르겠다 ㅋㅋ

$ docker ps -a
CONTAINER ID   IMAGE                    COMMAND                  CREATED          STATUS                      PORTS     NAMES
fdd1ba582924   ghcr.io/sasha0552/vllm   "python3 -m vllm.ent…"   42 seconds ago   Exited (1) 26 seconds ago             gemma4

[링크 : https://data-newbie.tistory.com/m/1012]

[링크 : https://coding-review.tistory.com/m/608]


+

2026.05.25

docker run -itd \
  --name gemma4 \
  --ipc=host \
  --network host \
  --gpus all \
  -v /mnt/huggingface:/root/.cache/huggingface \
  ghcr.io/sasha0552/vllm


문제없이 되는거 같으면서도

왜 qwen3-0.6B가 언급이 되지?

INFO 05-25 05:00:09 [__init__.py:241] Automatically detected platform cuda.
(APIServer pid=1) INFO 05-25 05:00:11 [api_server.py:1873] vLLM API server version 999.999.999
(APIServer pid=1) INFO 05-25 05:00:11 [utils.py:326] non-default args: {}
(APIServer pid=1) INFO 05-25 05:00:19 [__init__.py:742] Resolved architecture: Qwen3ForCausalLM
(APIServer pid=1) WARNING 05-25 05:00:19 [__init__.py:2828] Your device 'NVIDIA GeForce GTX 1080 Ti' (with compute capability 6.1) doesn't support torch.bfloat16. Falling back to torch.float16 for compatibility.
(APIServer pid=1) WARNING 05-25 05:00:19 [__init__.py:2879] Casting torch.bfloat16 to torch.float16.
(APIServer pid=1) INFO 05-25 05:00:19 [__init__.py:1774] Using max model len 40960
(APIServer pid=1) WARNING 05-25 05:00:19 [arg_utils.py:1806] Compute Capability < 8.0 is not supported by the V1 Engine. Falling back to V0.
(APIServer pid=1) WARNING 05-25 05:00:19 [arg_utils.py:1580] Chunked prefill is enabled by default for models with max_model_len > 32K. Chunked prefill might not work with some features or models. If you encounter any issues, please disable by launching with --enable-chunked-prefill=False.
(APIServer pid=1) INFO 05-25 05:00:20 [scheduler.py:222] Chunked prefill is enabled with max_num_batched_tokens=2048.
(APIServer pid=1) INFO 05-25 05:00:20 [api_server.py:295] Started engine process with PID 36
INFO 05-25 05:00:24 [__init__.py:241] Automatically detected platform cuda.
INFO 05-25 05:00:25 [llm_engine.py:222] Initializing a V0 LLM engine (v999.999.999) with config: model='Qwen/Qwen3-0.6B', speculative_config=None, tokenizer='Qwen/Qwen3-0.6B', skip_tokenizer_init=False, tokenizer_mode=auto, revision=None, override_neuron_config={}, tokenizer_revision=None, trust_remote_code=False, dtype=torch.float16, max_seq_len=40960, download_dir=None, load_format=auto, tensor_parallel_size=1, pipeline_parallel_size=1, disable_custom_all_reduce=False, quantization=None, enforce_eager=False, kv_cache_dtype=auto, device_config=cuda, decoding_config=DecodingConfig(backend='auto', disable_fallback=False, disable_any_whitespace=False, disable_additional_properties=False, reasoning_backend=''), observability_config=ObservabilityConfig(show_hidden_metrics_for_version=None, otlp_traces_endpoint=None, collect_detailed_traces=None), seed=0, served_model_name=Qwen/Qwen3-0.6B, enable_prefix_caching=None, chunked_prefill_enabled=True, use_async_output_proc=True, pooler_config=None, compilation_config={"level":0,"debug_dump_path":"","cache_dir":"","backend":"","custom_ops":[],"splitting_ops":null,"use_inductor":true,"compile_sizes":[],"inductor_compile_config":{"enable_auto_functionalized_v2":false},"inductor_passes":{},"cudagraph_mode":0,"use_cudagraph":true,"cudagraph_num_of_warmups":0,"cudagraph_capture_sizes":[256,248,240,232,224,216,208,200,192,184,176,168,160,152,144,136,128,120,112,104,96,88,80,72,64,56,48,40,32,24,16,8,4,2,1],"cudagraph_copy_inputs":false,"full_cuda_graph":false,"pass_config":{"enable_fusion":false,"enable_noop":false},"max_capture_size":256,"local_cache_dir":null}, use_cached_outputs=True,
INFO 05-25 05:00:28 [cuda.py:374] Cannot use FlashAttention-2 backend for Volta and Turing GPUs.
INFO 05-25 05:00:28 [cuda.py:419] Using XFormers backend.
INFO 05-25 05:00:28 [parallel_state.py:1134] rank 0 in world size 1 is assigned as DP rank 0, PP rank 0, TP rank 0, EP rank 0
INFO 05-25 05:00:28 [model_runner.py:1080] Starting to load model Qwen/Qwen3-0.6B...
INFO 05-25 05:00:29 [weight_utils.py:296] Using model weights format ['*.safetensors']
INFO 05-25 05:00:29 [weight_utils.py:349] No model.safetensors.index.json found in remote.
Loading safetensors checkpoint shards:   0% Completed | 0/1 [00:00<?, ?it/s]
Loading safetensors checkpoint shards: 100% Completed | 1/1 [00:00<00:00,  3.47it/s]

INFO 05-25 05:00:29 [default_loader.py:267] Loading weights took 0.32 seconds
INFO 05-25 05:00:30 [model_runner.py:1112] Model loading took 1.1201 GiB and 1.275699 seconds
INFO 05-25 05:00:31 [worker.py:296] Memory profiling takes 1.07 seconds
INFO 05-25 05:00:31 [worker.py:296] the current vLLM instance can use total_gpu_memory (10.90GiB) x gpu_memory_utilization (0.90) = 9.81GiB
INFO 05-25 05:00:31 [worker.py:296] model weights take 1.12GiB; non_torch_memory takes 0.04GiB; PyTorch activation peak memory takes 1.39GiB; the rest of the memory reserved for KV Cache is 7.26GiB.
INFO 05-25 05:00:31 [executor_base.py:114] # cuda blocks: 4247, # CPU blocks: 2340
INFO 05-25 05:00:31 [executor_base.py:119] Maximum concurrency for 40960 tokens per request: 1.66x
INFO 05-25 05:00:34 [model_runner.py:1383] Capturing cudagraphs for decoding. This may lead to unexpected consequences if the model is not static. To run the model in eager mode, set 'enforce_eager=True' or use '--enforce-eager' in the CLI. If out-of-memory error occurs during cudagraph capture, consider decreasing `gpu_memory_utilization` or switching to eager mode. You can also reduce the `max_num_seqs` as needed to decrease memory usage.
Capturing CUDA graph shapes: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 35/35 [00:12<00:00,  2.85it/s]
INFO 05-25 05:00:46 [model_runner.py:1535] Graph capturing finished in 12 secs, took 0.19 GiB
INFO 05-25 05:00:46 [llm_engine.py:417] init engine (profile, create kv cache, warmup model) took 16.41 seconds
(APIServer pid=1) INFO 05-25 05:00:46 [api_server.py:1679] Supported_tasks: ['generate']
(APIServer pid=1) WARNING 05-25 05:00:46 [__init__.py:1658] Default sampling parameters have been overridden by the model's Hugging Face generation config recommended from the model creator. If this is not intended, please relaunch vLLM instance with `--generation-config vllm`.
(APIServer pid=1) INFO 05-25 05:00:46 [serving_responses.py:124] Using default chat sampling params from model: {'temperature': 0.6, 'top_k': 20, 'top_p': 0.95}
(APIServer pid=1) INFO 05-25 05:00:47 [serving_chat.py:135] Using default chat sampling params from model: {'temperature': 0.6, 'top_k': 20, 'top_p': 0.95}
(APIServer pid=1) INFO 05-25 05:00:47 [serving_completion.py:77] Using default completion sampling params from model: {'temperature': 0.6, 'top_k': 20, 'top_p': 0.95}
(APIServer pid=1) INFO 05-25 05:00:47 [api_server.py:1948] Starting vLLM API server 0 on http://0.0.0.0:8000
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:36] Available routes are:
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /openapi.json, Methods: HEAD, GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /docs, Methods: HEAD, GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /docs/oauth2-redirect, Methods: HEAD, GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /redoc, Methods: HEAD, GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /health, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /load, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /ping, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /ping, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /tokenize, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /detokenize, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/models, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /version, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/responses, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/responses/{response_id}, Methods: GET
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/responses/{response_id}/cancel, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/chat/completions, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/completions, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/embeddings, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /pooling, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /classify, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /score, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/score, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/audio/transcriptions, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/audio/translations, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /rerank, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v1/rerank, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /v2/rerank, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /scale_elastic_ep, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /is_scaling_elastic_ep, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /invocations, Methods: POST
(APIServer pid=1) INFO 05-25 05:00:47 [launcher.py:44] Route: /metrics, Methods: GET
(APIServer pid=1) INFO:     Started server process [1]
(APIServer pid=1) INFO:     Waiting for application startup.
(APIServer pid=1) INFO:     Application startup complete.


파스칼 P40 용으로 시도하는데 여전히 안된다. 아놔.. 포기!

[링크 : https://github.com/uaysk/vllm-pascal]


$ vllm serve google/gemma-4-E4B-it
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]        █     █     █▄   ▄█
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]  ▄▄ ▄█ █     █     █ ▀▄▀ █  version 0.21.0
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]   █▄█▀ █     █     █     █  model   google/gemma-4-E4B-it
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]    ▀▀  ▀▀▀▀▀ ▀▀▀▀▀ ▀     ▀
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:306]
(APIServer pid=65016) INFO 05-25 21:22:17 [utils.py:240] non-default args: {'model_tag': 'google/gemma-4-E4B-it', 'model': 'google/gemma-4-E4B-it'}
(APIServer pid=65016) Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
config.json: 5.14kB [00:00, 4.19MB/s]
processor_config.json: 1.69kB [00:00, 6.85MB/s]
(APIServer pid=65016) INFO 05-25 21:22:19 [model.py:568] Resolved architecture: Gemma4ForConditionalGeneration
(APIServer pid=65016) WARNING 05-25 21:22:19 [model.py:1982] Your device 'NVIDIA GeForce GTX 1080 Ti' (with compute capability 6.1) doesn't support torch.bfloat16. Falling back to torch.float16 for compatibility.
(APIServer pid=65016) WARNING 05-25 21:22:19 [model.py:2035] Casting torch.bfloat16 to torch.float16.
(APIServer pid=65016) INFO 05-25 21:22:19 [model.py:1697] Using max model len 131072
(APIServer pid=65016) INFO 05-25 21:22:19 [config.py:101] Gemma4 model has heterogeneous head dimensions (head_dim=256, global_head_dim=512). Forcing TRITON_ATTN backend to prevent mixed-backend numerical divergence.
(APIServer pid=65016) INFO 05-25 21:22:19 [vllm.py:886] Asynchronous scheduling is enabled.
(APIServer pid=65016) INFO 05-25 21:22:19 [kernel.py:212] Final IR op priority after setting platform defaults: IrOpPriorityConfig(rms_norm=['native'], fused_add_rms_norm=['native'])
tokenizer_config.json: 2.10kB [00:00, 2.10MB/s]
tokenizer.json: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 32.2M/32.2M [00:02<00:00, 11.8MB/s]
chat_template.jinja: 17.3kB [00:00, 13.0MB/s]
generation_config.json: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 208/208 [00:00<00:00, 1.66MB/s]
(EngineCore pid=65068) INFO 05-25 21:23:14 [core.py:109] Initializing a V1 LLM engine (v0.21.0) with config: model='google/gemma-4-E4B-it', speculative_config=None, tokenizer='google/gemma-4-E4B-it', skip_tokenizer_init=False, tokenizer_mode=auto, revision=None, tokenizer_revision=None, trust_remote_code=False, dtype=torch.float16, max_seq_len=131072, download_dir=None, load_format=auto, tensor_parallel_size=1, pipeline_parallel_size=1, data_parallel_size=1, decode_context_parallel_size=1, dcp_comm_backend=ag_rs, disable_custom_all_reduce=False, quantization=None, quantization_config=None, enforce_eager=False, enable_return_routed_experts=False, kv_cache_dtype=auto, device_config=cuda, structured_outputs_config=StructuredOutputsConfig(backend='auto', disable_any_whitespace=False, disable_additional_properties=False, reasoning_parser='', reasoning_parser_plugin='', enable_in_reasoning=False), observability_config=ObservabilityConfig(show_hidden_metrics_for_version=None, otlp_traces_endpoint=None, collect_detailed_traces=None, kv_cache_metrics=False, kv_cache_metrics_sample=0.01, cudagraph_metrics=False, enable_layerwise_nvtx_tracing=False, enable_mfu_metrics=False, enable_mm_processor_stats=False, enable_logging_iteration_details=False), seed=0, served_model_name=google/gemma-4-E4B-it, enable_prefix_caching=True, enable_chunked_prefill=True, pooler_config=None, compilation_config={'mode': <CompilationMode.VLLM_COMPILE: 3>, 'debug_dump_path': None, 'cache_dir': '', 'compile_cache_save_format': 'binary', 'backend': 'inductor', 'custom_ops': ['none'], 'ir_enable_torch_wrap': True, 'splitting_ops': ['vllm::unified_attention_with_output', 'vllm::unified_mla_attention_with_output', 'vllm::mamba_mixer2', 'vllm::mamba_mixer', 'vllm::short_conv', 'vllm::linear_attention', 'vllm::plamo2_mamba_mixer', 'vllm::gdn_attention_core', 'vllm::gdn_attention_core_xpu', 'vllm::olmo_hybrid_gdn_full_forward', 'vllm::kda_attention', 'vllm::sparse_attn_indexer', 'vllm::rocm_aiter_sparse_attn_indexer', 'vllm::deepseek_v4_attention', 'vllm::unified_kv_cache_update', 'vllm::unified_mla_kv_cache_update'], 'compile_mm_encoder': False, 'cudagraph_mm_encoder': False, 'encoder_cudagraph_token_budgets': [], 'encoder_cudagraph_max_vision_items_per_batch': 0, 'encoder_cudagraph_max_frames_per_batch': None, 'compile_sizes': [], 'compile_ranges_endpoints': [2048], 'inductor_compile_config': {'enable_auto_functionalized_v2': False, 'size_asserts': False, 'alignment_asserts': False, 'scalar_asserts': False, 'combo_kernels': True, 'benchmark_combo_kernel': True}, 'inductor_passes': {}, 'cudagraph_mode': <CUDAGraphMode.FULL_AND_PIECEWISE: (2, 1)>, 'cudagraph_num_of_warmups': 1, 'cudagraph_capture_sizes': [1, 2, 4, 8, 16, 24, 32, 40, 48, 56, 64, 72, 80, 88, 96, 104, 112, 120, 128, 136, 144, 152, 160, 168, 176, 184, 192, 200, 208, 216, 224, 232, 240, 248, 256, 272, 288, 304, 320, 336, 352, 368, 384, 400, 416, 432, 448, 464, 480, 496, 512], 'cudagraph_copy_inputs': False, 'cudagraph_specialize_lora': True, 'use_inductor_graph_partition': False, 'pass_config': {'fuse_norm_quant': False, 'fuse_act_quant': False, 'fuse_attn_quant': False, 'enable_sp': False, 'fuse_gemm_comms': False, 'fuse_allreduce_rms': False, 'fuse_act_padding': False}, 'max_cudagraph_capture_size': 512, 'dynamic_shapes_config': {'type': <DynamicShapesType.BACKED: 'backed'>, 'evaluate_guards': False, 'assume_32_bit_indexing': False}, 'local_cache_dir': None, 'fast_moe_cold_start': False, 'static_all_moe_layers': []}, kernel_config=KernelConfig(ir_op_priority=IrOpPriorityConfig(rms_norm=['native'], fused_add_rms_norm=['native']), enable_flashinfer_autotune=False, moe_backend='auto')
(EngineCore pid=65068) Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
(EngineCore pid=65068) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:371: UserWarning: Found GPU0 NVIDIA GeForce GTX 1080 Ti which is of compute capability (CC) 6.1.
(EngineCore pid=65068) The following list shows the CCs this version of PyTorch was built for and the hardware CCs it supports:
(EngineCore pid=65068) - 7.5 which supports hardware CC >=7.5,<8.0
(EngineCore pid=65068) - 8.0 which supports hardware CC >=8.0,<9.0 except {8.7}
(EngineCore pid=65068) - 8.6 which supports hardware CC >=8.6,<9.0 except {8.7}
(EngineCore pid=65068) - 9.0 which supports hardware CC >=9.0,<10.0
(EngineCore pid=65068) - 10.0 which supports hardware CC >=10.0,<11.0 except {10.1}
(EngineCore pid=65068) - 12.0 which supports hardware CC >=12.0,<13.0
(EngineCore pid=65068) Please follow the instructions at https://pytorch.org/get-started/locally/ to install a PyTorch release that supports one of these CUDA versions: 12.6
(EngineCore pid=65068)   _warn_unsupported_code(d, device_cc, code_ccs)
(EngineCore pid=65068) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:371: UserWarning: Found GPU1 NVIDIA GeForce GTX 1080 Ti which is of compute capability (CC) 6.1.
(EngineCore pid=65068) The following list shows the CCs this version of PyTorch was built for and the hardware CCs it supports:
(EngineCore pid=65068) - 7.5 which supports hardware CC >=7.5,<8.0
(EngineCore pid=65068) - 8.0 which supports hardware CC >=8.0,<9.0 except {8.7}
(EngineCore pid=65068) - 8.6 which supports hardware CC >=8.6,<9.0 except {8.7}
(EngineCore pid=65068) - 9.0 which supports hardware CC >=9.0,<10.0
(EngineCore pid=65068) - 10.0 which supports hardware CC >=10.0,<11.0 except {10.1}
(EngineCore pid=65068) - 12.0 which supports hardware CC >=12.0,<13.0
(EngineCore pid=65068) Please follow the instructions at https://pytorch.org/get-started/locally/ to install a PyTorch release that supports one of these CUDA versions: 12.6
(EngineCore pid=65068)   _warn_unsupported_code(d, device_cc, code_ccs)
(EngineCore pid=65068) /home/minimonk/.local/lib/python3.10/site-packages/torch/cuda/__init__.py:489: UserWarning:
(EngineCore pid=65068) NVIDIA GeForce GTX 1080 Ti with CUDA capability sm_61 is not compatible with the current PyTorch installation.
(EngineCore pid=65068) The current PyTorch install supports CUDA capabilities sm_75 sm_80 sm_86 sm_90 sm_100 sm_120.
(EngineCore pid=65068) If you want to use the NVIDIA GeForce GTX 1080 Ti GPU with PyTorch, please check the instructions at https://pytorch.org/get-started/locally/
(EngineCore pid=65068)
(EngineCore pid=65068)   queued_call()
(EngineCore pid=65068) INFO 05-25 21:23:20 [parallel_state.py:1410] world_size=1 rank=0 local_rank=0 distributed_init_method=tcp://192.168.40.238:39589 backend=nccl
(EngineCore pid=65068) INFO 05-25 21:23:20 [parallel_state.py:1723] rank 0 in world size 1 is assigned as DP rank 0, PP rank 0, PCP rank 0, TP rank 0, EP rank N/A, EPLB rank N/A
(EngineCore pid=65068) WARNING 05-25 21:23:21 [topk_topp_sampler.py:61] FlashInfer top-p/top-k sampling not supported on compute capability 6.1; falling back to PyTorch-native sampler. Set VLLM_USE_FLASHINFER_SAMPLER=0 to silence.
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] EngineCore failed to start.
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] Traceback (most recent call last):
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1114, in run_engine_core
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     engine_core = EngineCoreProc(*args, engine_index=dp_rank, **kwargs)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 880, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     super().__init__(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 118, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.model_executor = executor_class(vllm_config)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/abstract.py", line 109, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self._init_executor()
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/uniproc_executor.py", line 60, in _init_executor
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.driver_worker.init_device()
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/worker_base.py", line 317, in init_device
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.worker.init_device()  # type: ignore
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     return func(*args, **kwargs)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_worker.py", line 330, in init_device
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.model_runner = GPUModelRunnerV1(self.vllm_config, self.device)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_model_runner.py", line 629, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.input_batch = InputBatch(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_input_batch.py", line 171, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.block_table = MultiGroupBlockTable(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 267, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.block_tables = [
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 268, in <listcomp>
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     BlockTable(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 70, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.block_table = self._make_buffer(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 218, in _make_buffer
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     return CpuGpuBuffer(
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/utils.py", line 120, in __init__
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]     self.gpu = torch.zeros_like(self.cpu, device=device)
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] torch.AcceleratorError: CUDA error: no kernel image is available for execution on the device
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] Search for `cudaErrorNoKernelImageForDevice' in https://docs.nvidia.com/cuda/cuda-runtime-api/group__CUDART__TYPES.html for more information.
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] For debugging consider passing CUDA_LAUNCH_BLOCKING=1
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140] Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
(EngineCore pid=65068) ERROR 05-25 21:23:21 [core.py:1140]
(EngineCore pid=65068) Process EngineCore:
(EngineCore pid=65068) Traceback (most recent call last):
(EngineCore pid=65068)   File "/usr/lib/python3.10/multiprocessing/process.py", line 314, in _bootstrap
(EngineCore pid=65068)     self.run()
(EngineCore pid=65068)   File "/usr/lib/python3.10/multiprocessing/process.py", line 108, in run
(EngineCore pid=65068)     self._target(*self._args, **self._kwargs)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1144, in run_engine_core
(EngineCore pid=65068)     raise e
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 1114, in run_engine_core
(EngineCore pid=65068)     engine_core = EngineCoreProc(*args, engine_index=dp_rank, **kwargs)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068)     return func(*args, **kwargs)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 880, in __init__
(EngineCore pid=65068)     super().__init__(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core.py", line 118, in __init__
(EngineCore pid=65068)     self.model_executor = executor_class(vllm_config)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068)     return func(*args, **kwargs)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/abstract.py", line 109, in __init__
(EngineCore pid=65068)     self._init_executor()
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/executor/uniproc_executor.py", line 60, in _init_executor
(EngineCore pid=65068)     self.driver_worker.init_device()
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/worker_base.py", line 317, in init_device
(EngineCore pid=65068)     self.worker.init_device()  # type: ignore
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(EngineCore pid=65068)     return func(*args, **kwargs)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_worker.py", line 330, in init_device
(EngineCore pid=65068)     self.model_runner = GPUModelRunnerV1(self.vllm_config, self.device)
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_model_runner.py", line 629, in __init__
(EngineCore pid=65068)     self.input_batch = InputBatch(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/gpu_input_batch.py", line 171, in __init__
(EngineCore pid=65068)     self.block_table = MultiGroupBlockTable(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 267, in __init__
(EngineCore pid=65068)     self.block_tables = [
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 268, in <listcomp>
(EngineCore pid=65068)     BlockTable(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 70, in __init__
(EngineCore pid=65068)     self.block_table = self._make_buffer(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/worker/block_table.py", line 218, in _make_buffer
(EngineCore pid=65068)     return CpuGpuBuffer(
(EngineCore pid=65068)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/utils.py", line 120, in __init__
(EngineCore pid=65068)     self.gpu = torch.zeros_like(self.cpu, device=device)
(EngineCore pid=65068) torch.AcceleratorError: CUDA error: no kernel image is available for execution on the device
(EngineCore pid=65068) Search for `cudaErrorNoKernelImageForDevice' in https://docs.nvidia.com/cuda/cuda-runtime-api/group__CUDART__TYPES.html for more information.
(EngineCore pid=65068) CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
(EngineCore pid=65068) For debugging consider passing CUDA_LAUNCH_BLOCKING=1
(EngineCore pid=65068) Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
(EngineCore pid=65068)
[rank0]:[W525 21:23:22.743241268 ProcessGroupNCCL.cpp:1575] Warning: WARNING: destroy_process_group() was not called before program exit, which can leak resources. For more info, please see https://pytorch.org/docs/stable/distributed.html#shutdown (function operator())
(APIServer pid=65016) Traceback (most recent call last):
(APIServer pid=65016)   File "/home/minimonk/.local/bin/vllm", line 8, in <module>
(APIServer pid=65016)     sys.exit(main())
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/cli/main.py", line 92, in main
(APIServer pid=65016)     args.dispatch_function(args)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/cli/serve.py", line 122, in cmd
(APIServer pid=65016)     uvloop.run(run_server(args))
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/uvloop/__init__.py", line 69, in run
(APIServer pid=65016)     return loop.run_until_complete(wrapper())
(APIServer pid=65016)   File "uvloop/loop.pyx", line 1518, in uvloop.loop.Loop.run_until_complete
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/uvloop/__init__.py", line 48, in wrapper
(APIServer pid=65016)     return await main
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 693, in run_server
(APIServer pid=65016)     await run_server_worker(listen_address, sock, args, **uvicorn_kwargs)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 707, in run_server_worker
(APIServer pid=65016)     async with build_async_engine_client(
(APIServer pid=65016)   File "/usr/lib/python3.10/contextlib.py", line 199, in __aenter__
(APIServer pid=65016)     return await anext(self.gen)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 100, in build_async_engine_client
(APIServer pid=65016)     async with build_async_engine_client_from_engine_args(
(APIServer pid=65016)   File "/usr/lib/python3.10/contextlib.py", line 199, in __aenter__
(APIServer pid=65016)     return await anext(self.gen)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/entrypoints/openai/api_server.py", line 136, in build_async_engine_client_from_engine_args
(APIServer pid=65016)     async_llm = AsyncLLM.from_vllm_config(
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/async_llm.py", line 217, in from_vllm_config
(APIServer pid=65016)     return cls(
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/async_llm.py", line 146, in __init__
(APIServer pid=65016)     self.engine_core = EngineCoreClient.make_async_mp_client(
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(APIServer pid=65016)     return func(*args, **kwargs)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 130, in make_async_mp_client
(APIServer pid=65016)     return AsyncMPClient(*client_args)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/tracing/otel.py", line 178, in sync_wrapper
(APIServer pid=65016)     return func(*args, **kwargs)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 900, in __init__
(APIServer pid=65016)     super().__init__(
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/core_client.py", line 535, in __init__
(APIServer pid=65016)     with launch_core_engines(
(APIServer pid=65016)   File "/usr/lib/python3.10/contextlib.py", line 142, in __exit__
(APIServer pid=65016)     next(self.gen)
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/utils.py", line 1128, in launch_core_engines
(APIServer pid=65016)     wait_for_engine_startup(
(APIServer pid=65016)   File "/home/minimonk/.local/lib/python3.10/site-packages/vllm/v1/engine/utils.py", line 1187, in wait_for_engine_startup
(APIServer pid=65016)     raise RuntimeError(
(APIServer pid=65016) RuntimeError: Engine core initialization failed. See root cause above. Failed core proc(s): {}
Posted by 구차니

한번 찾아보니 가격 3배 이상, 토큰 3배 증가

사실상 9배 증가라는 소문이 있네


[링크 : https://wikidocs.net/blog/@jaehong/13849/]


근데 순식간에(?) geminu 3.0 flash 를 날리고 gemini 3.5 flash + 3.1 pro 를 같은 할당량으로 묶는건 너무 개매너 아니냐 -_-

[링크 : https://ai.google.dev/gemini-api/docs/pricing?hl=ko]


+

2026.05.29

느낌상 질문 하나당 한칸 줄어드는 느낌..

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

python huggingface 저장경로 변경하기  (0) 2026.05.24
vllm 설치, 실행 실패 -> 사실상 포기  (0) 2026.05.24
openclaw agent 구성 관련  (0) 2026.05.22
mxfp4  (0) 2026.05.22
텔레그램 봇 - 메시지 관련  (0) 2026.05.22
Posted by 구차니

음.. local LLM이 하나 뿐이면 느려서 어떻게 구성해야 할까? ㅜㅠ


[링크 : https://brunch.co.kr/@bbt/53]

[링크 : https://docs.openclaw.ai/ko/concepts/multi-agent]

Posted by 구차니
Posted by 구차니

inlinebutton - 메시지 하단에 생기는 버튼

replybutton - 사용자 입력창 하단에 생기는 버튼

[링크 : https://naimjae.tistory.com/11]


메시지 서식(markdown 등)

[링크 : https://naimjae.tistory.com/8]


[링크 : https://docs.python-telegram-bot.org/en/stable/telegram.menubuttoncommands.html]

    [링크 : https://docs.python-telegram-bot.org/en/stable/telegram.html]


+

2026.05.25

Bot settings

set_my_commands() Used for setting the list of commands
delete_my_commands() Used for deleting the list of commands
get_my_commands() Used for obtaining the list of commands
get_my_default_administrator_rights() Used for obtaining the default administrator rights for the bot
set_my_default_administrator_rights() Used for setting the default administrator rights for the bot
get_chat_menu_button() Used for obtaining the menu button of a private chat or the default menu button
set_chat_menu_button() Used for setting the menu button of a private chat or the default menu button
set_my_description() Used for setting the description of the bot
get_my_description() Used for obtaining the description of the bot
set_my_short_description() Used for setting the short description of the bot
get_my_short_description() Used for obtaining the short description of the bot
set_my_name() Used for setting the name of the bot
get_my_name() Used for obtaining the name of the bot
set_my_profile_photo() Used for setting the profile photo of the bot
remove_my_profile_photo() Used for removing the profile photo of the bot

[링크 : https://docs.python-telegram-bot.org/en/stable/telegram.bot.html]

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

openclaw agent 구성 관련  (0) 2026.05.22
mxfp4  (0) 2026.05.22
openclaw 설치 telegram 신기하네?  (0) 2026.05.22
wan2.2 + comfyui 시도  (0) 2026.05.21
wan2.2 + comfyui  (0) 2026.05.19
Posted by 구차니