그냥 클로드가 다해줘버리는 느낌이라 모르겠다 ㅋㅋㅋㅋ

아무튼, 이번 실험의 주제는 model이 우선이냐, sft가 우선이냐 인데

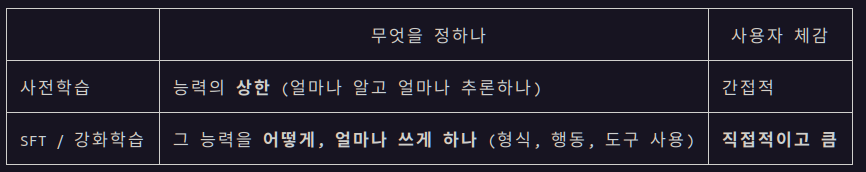
결론만 보면 "결과물의 품질은 model이 우선이다, 하지만 사용자 체감은 model 이 동등할 경우 sft가 크다." 이다
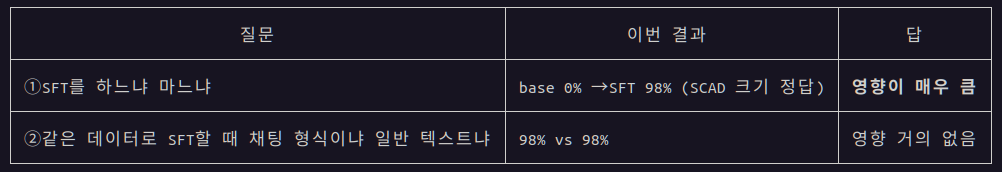


정작 학습된 모델도 openSCAD로 내가 원하는대로 작동을 만들어낼 순 없긴한데..

얼마나 더 많은 자료와 gpu를 때려박아야 작동할까 -ㅁ-?


아래는 그나마 그려지는 예. 그 와중에  python 으로 하라는데 sft 영향을 강하게 받아서 openSCAD로 해버린다.

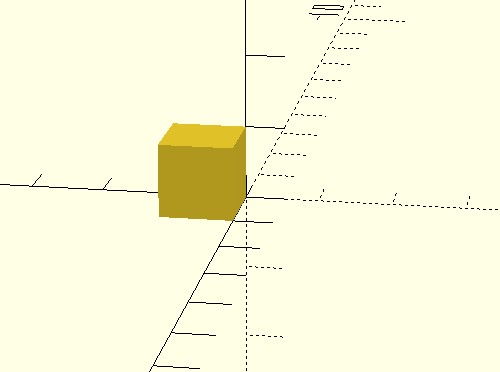
> cube each 1m
cube([1,1,1]);

[ Prompt: 9.9 t/s | Generation: 40.3 t/s ]
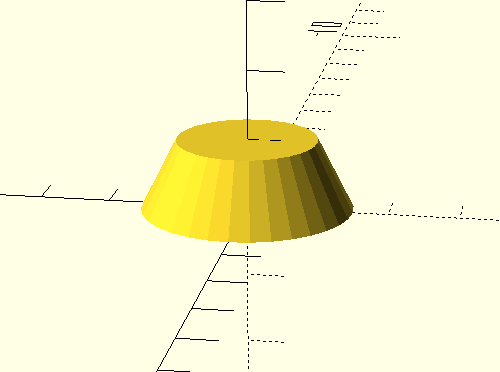
> donut
cylinder (h=1, r1=1.5, r2, $fn=32);

[ Prompt: 155.9 t/s | Generation: 39.6 t/s ]


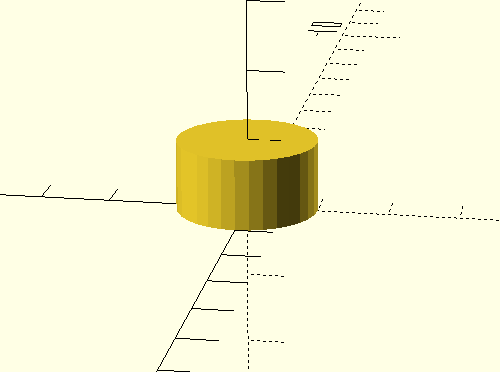
> rectangle in python
cylinder (h=1, r1=1, r2, $fn=32);

[ Prompt: 177.6 t/s | Generation: 42.0 t/s ]


일단 이번 테스트 요약하면

1. model의 크기, 정보량이 결국은 결과의 품질을 보장한다.

2. epoch가 높진 않다. 1~2 epoch. 그래서 미친듯이 원본 데이터를 수집하는 거군.. ai 업체들이 톤 단위로 책 사들이는 이유..

3. sft는 생각외로 사용자 체감이 크고, 본 학습 시간보다 sft는 빠르게 끝난다. 좋게 보면 학습에 대한 효율이 좋다.


'모종의 음모 > ai 프로그램' 카테고리의 다른 글

strata  (0) 2026.10.20
프로그래밍도 할 줄 아는 local LLM 만들기.. part 1?  (0) 2026.10.16
cyc 프로젝트, dreamcoder  (0) 2026.10.16
클로드 코드, 루틴 좋네?  (0) 2026.10.06
클로드 사용량 재설정  (0) 2026.09.29
Posted by 구차니

요즘 가장 핫한 녀석

llama.cpp 처럼 ai 모델을 돌리는 프로그램인데

qwen3.8 flash next를 돌리는데 목적이 있는 것 같다.

Qwen3.8-Flash-Next on any consumer hardware: one-click install for Windows / Linux. Strata inference engine, OpenAI/Anthropic API on localhost, optional image input.

[링크 : https://github.com/niko1221/strata]


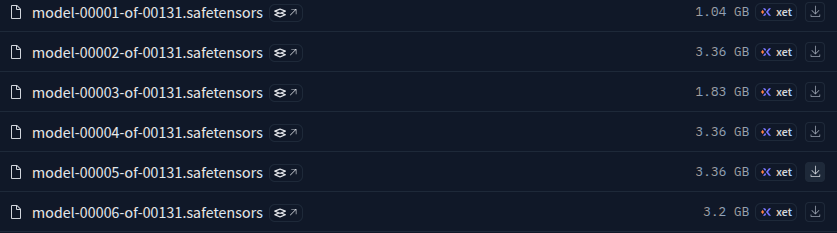
대충 계산해보면.. 최악의 경우(?) 131 * 3.3G = 432.3GB 정도 되는 모델이고

[링크 : https://huggingface.co/Qwen/Qwen3.8-Flash-Next/tree/main]


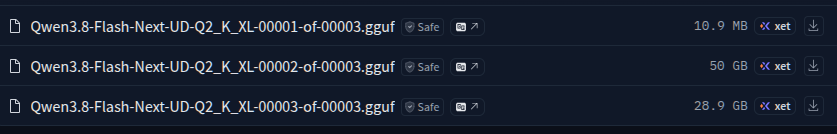
Q2 양자화로도 80기가.. 아니 이걸 어떻게 돌리라고 -_-

[링크 : https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF/tree/main]


아무튼 VRAM을 최소화(?) 하고 RAM을 미친듯이 먹는걸 보면..

cpu offload는 하지 않고 아주 빈번하고 VRAM을 바꾸면서 연산을 하도록 하여, 대용량 모델을 돌릴수 있게 하나보다.

Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter model that normally needs a server, on a normal PC. It chats, writes code, reads pictures and works with your apps and coding agents. Your chats and files stay on your PC.

New here? Check what you need, then install the app.

Runs on a gaming PC. 32 GB of RAM and graphics memory together is enough to start.
Works with your tools. It speaks the OpenAI and Anthropic APIs, so Claude Code, Codex CLI, OpenCode and other agents connect to it.
Reads pictures. They are on by default.
Free. MIT license, no account, no cloud.
Private. No telemetry. What Strata downloads, when it uses the internet and how it checks downloads is in docs/SAFETY.md.

You need at least 32 GB of RAM and graphics memory (VRAM) together. On a Mac or a Ryzen AI Max, that is the unified memory. More memory gives a bigger model or a faster one.

A 32 GB PC with a 12-16 GB card runs the Coder.
64 GB of RAM runs every size.
Posted by 구차니

클로드 갈궈서 어느정도 결과가 나왔지만

검증하다 보니 다시 추가학습을 시켜야 해서 일단 part 2로 가야 할 듯 -_ㅠ


실험의 목적

  • sft(supervised fine tunning)이 모델의 효용을 올리는데 얼마나 중요할까 (= 모델빨 vs 대답 채찍질 빨)
  • sft의 형상에 따라 LLM이 얼마나 코딩을 잘하게 될까


실험설계

  • 프로그래밍 하려면 이전의 것으로는 안된다고 함
    • 프로그램을 위해서는 토크나이저가 공백, 엔터, 탭등을 날려먹으면 안되니까
  • 다국어 하려니 학습셋과 시간이 문제라 영어로만 제한
  • 프로그래밍을 위해 python과 openSCAD 문법을 중심으로 학습
  • sft 하나는 python에 특화, 다른 sft는 openSCAD에 특화 시키기
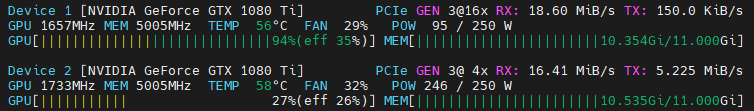
  • 이런저런 이유로 110M 정도 까지 모델 크기가 증가했고, 그래픽 카드 양쪽으로 나눠서 학습 진행


현재상태

  • 학습 완료. 다만 입력 포맷만 다른 두개의 모델이 되어버려서, 추가로 학습중
  • 기존은 python / openSCAD를 다루고 (대화로),
  • 새로 할 것은 openSCAD에 대한 sft만 진행하고 python을 물어봐서 품질을 볼 것임


으아아 내 26시간 ㅠㅠ

일단 특이하게도 학습 자체는 1 epoch만 돌리는게 표준이라고 한다. 반복해서 보는 것 보다 새로운걸 보는것이 이득이라고 하는데

sft 자체는 2~3 epoch 정도 반복으로 보는게 낫다고 한다.

● 학습 시간 요약

  장비는 GTX 1080 Ti 2장입니다.

  1. 사전학습 (base110m)

  ┌───────┬──────────────────────────────────┐
  │      항목      │                                         값                                          │
  ├───────┼──────────────────────────────────┤
  │ 규모           │ 3,814스텝, 10억 토큰, 스텝당 26.2만 토큰                                            │
  ├───────┼──────────────────────────────────┤
  │ 순수 학습 시간 │ 약 26시간 (스텝당 약 24초, 초당 1.09만 토큰, GPU 2장 병렬)                          │
  ├───────┼─────────────────────────────────────────────────┤
  │ 실제 진행      │ 10/13 12:01 시작. step 250 근처에서 사고로 중단돼 재시작했고, step 284에서 일시정지 │
  ├────────┼────────────────────────────────────────────────────┤
  │                │ 10/15 10:09 재개 → 10/16 09:57 종료 (23.8시간 연속)                                 │
  └──────┴──────────────────────────────────────────────┘

  데이터를 몇 번 봤는지(에폭)는 출처마다 다릅니다.
                                                                                                                            
  ┌────────────────────┬───────────┬────────────────┬──────┐
  │       데이터       │ 전체 토큰 │ 학습에서 본 양 │ 에폭 │
  ├────────────────────┼───────────┼────────────────┼──────┤
  │ 영어 (FineWeb-Edu) │ 7.85억    │ 5억            │ 0.64 │
  ├────────────────────┼───────────┼────────────────┼──────┤
  │ Python             │ 5.46억    │ 4억            │ 0.73 │
  ├────────────────────┼───────────┼────────────────┼──────┤
  │ OpenSCAD           │ 0.33억    │ 1억            │ 3.04 │
  └────────────────────┴───────────┴────────────────┴──────┘

  섞는 비율을 en 5 : py 4 : scad 1로 정했는데, SCAD 원본 데이터가 작아서 SCAD만 3번 넘게 반복해서 봤습니다.

  2. SFT (두 모델 동시, GPU 한 장씩)

  ┌─────────┬───────────────────┬─────────────────────┐
  │                         │           sft_chat (GPU0)           │  sft_plain (GPU1)   │
  ├─────────┼───────────────────┼─────────────────────┤
  │ 기간                    │ 10/16 10:24 → 14:26                 │ 10/16 10:24 → 14:36 │
  ├──────────┼────────────────────┼─────────────────────┤
  │ 소요 시간               │ 4시간 02분                          │ 4시간 12분          │
  ├───────────┼───────────────────┼─────────────────────┤
  │ 에폭당                  │ 약 80분 (3,185스텝)                 │ 약 84분             │
  ├───────────┼───────────────────┼─────────────────────┤
  │ 총량                    │ 3에폭, 9,555스텝, 예시 50,958개 × 3 │ 같음                │
  ├───────────┼──────────────────────┼─────────────────────┤
  │ 성능이 가장 좋았던 지점 │ step 6200 (2에폭 끝, 13:02)         │ step 6200           │
  └──────────────┴─────────────────────┴─────────────────────┘

  - 이 밖에 첫 시도가 09:58~10:20에 OOM으로 죽어서 22분을 잃었습니다.
  - 2에폭이면 충분했다는 결과를 기준으로 하면, 다음부터 SFT는 약 2시간 40분이면 됩니다.

  3. 평가와 변환

  - 벤치 9회(모델과 형식 조합): 14:36 → 15:49, 약 1시간 15분
    - 한 번에 5~26분이 걸렸습니다. 학습하지 않은 형식으로 묻는 교차 평가와 base 평가가 오래 걸렸는데, 모델이 멈추지 않고
      최대 길이까지 생성하기 때문입니다.
  - GGUF 변환 3개: 몇 분 이내


아래가 잘못 진행된 실험.

base 모델은 llama-completion으로 말을 주면 이어 나가도록 구성된 모델이고

/mnt/llm-scad/gguf$ /mnt/Downloads/llama-b10488/llama-completion -m base110m-step3814-f32.gguf -sm none --temp 0 --repeat-penalty 1.1 -n 200 -p $'// Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm.\n'
0.00.234.065 I llama_completion: llama backend init
0.00.234.071 I llama_completion: load the model and apply lora adapter, if any
0.00.482.739 W load: control-looking token:      7 '<|end|>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.661.575 I cmn          init: llama threadpool init, n_threads = 6
0.00.674.412 I 
0.00.674.450 I system_info: n_threads = 6 (n_threads_batch = 6) / 6 | CPU : SSE3 = 1 | SSSE3 = 1 | AVX = 1 | AVX2 = 1 | F16C = 1 | FMA = 1 | BMI2 = 1 | LLAMAFILE = 1 | OPENMP = 1 | REPACK = 1 | 
0.00.674.450 I 
0.00.674.513 I sampler seed: 2978975464
0.00.674.529 I sampler params: 
repeat_last_n = 64, repeat_penalty = 1.100, frequency_penalty = 0.000, presence_penalty = 0.000
dry_multiplier = 0.000, dry_base = 1.750, dry_allowed_length = 2, dry_penalty_last_n = 64
top_k = 40, top_p = 0.950, min_p = 0.050, xtc_probability = 0.000, xtc_threshold = 0.100, typical_p = 1.000, top_n_sigma = -1.000, temp = 0.000
mirostat = 0, mirostat_lr = 0.100, mirostat_ent = 5.000, adaptive_target = -1.000, adaptive_decay = 0.900
0.00.674.534 I sampler chain: logits -> penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> top-p -> min-p -> ?xtc -> temp-ext -> dist 
0.00.674.535 I generate: n_ctx = 2048, n_batch = 2048, n_predict = 200, n_keep = 0
0.00.674.535 I 
// Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm.
//   The tube is made of a 3mm tube with a hole in the middle.
//   The tube is made of a 6mm tube with a hole in the middle.
//   The tube is made of a 12mm tube with a hole in the middle.
//   The tube is made of a 15mm tube with a hole in the middle.
//   The tube is made of a 16mm tube with a hole in the middle.
//   The tube is made of a 18mm tube with a hole in the middle.
//   The tube is made of a 19mm tube with a hole in the middle.
//   The tube is made of a 20mm tube with a hole in the middle.
//   The tube is made of a 30mm tube with a hole in the middle.
//   The

0.01.140.346 I common_perf_print:    sampling time =      69.83 ms
0.01.140.347 I common_perf_print:    samplers time =      61.87 ms /   225 tokens
0.01.140.349 I common_perf_print:        load time =     211.82 ms
0.01.140.351 I common_perf_print: prompt eval time =      12.78 ms /    25 tokens (    0.51 ms per token,  1955.88 tokens per second)
0.01.140.352 I common_perf_print:        eval time =     381.24 ms /   199 runs   (    1.92 ms per token,   521.98 tokens per second)
0.01.140.353 I common_perf_print:       total time =     465.94 ms /   224 tokens
0.01.140.353 I common_perf_print: unaccounted time =       2.09 ms /   0.4 %      (total - sampling - prompt eval - eval) / (total)
0.01.140.354 I common_perf_print:    graphs reused =        198


sft_plain은 sft를 통해 openSCAD 형태의 출력을 학습시킨 모델

/mnt/llm-scad/gguf$ /mnt/Downloads/llama-b10488/llama-completion -m sft_plain-step9555-f32.gguf -sm none --temp 0 --repeat-penalty 1.1 -n 200 -p $'// Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm.\n'
0.00.212.691 I llama_completion: llama backend init
0.00.212.697 I llama_completion: load the model and apply lora adapter, if any
0.00.461.915 W load: control-looking token:      7 '<|end|>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.632.982 I cmn          init: llama threadpool init, n_threads = 6
0.00.645.921 I 
0.00.645.961 I system_info: n_threads = 6 (n_threads_batch = 6) / 6 | CPU : SSE3 = 1 | SSSE3 = 1 | AVX = 1 | AVX2 = 1 | F16C = 1 | FMA = 1 | BMI2 = 1 | LLAMAFILE = 1 | OPENMP = 1 | REPACK = 1 | 
0.00.645.961 I 
0.00.646.024 I sampler seed: 3402034624
0.00.646.039 I sampler params: 
repeat_last_n = 64, repeat_penalty = 1.100, frequency_penalty = 0.000, presence_penalty = 0.000
dry_multiplier = 0.000, dry_base = 1.750, dry_allowed_length = 2, dry_penalty_last_n = 64
top_k = 40, top_p = 0.950, min_p = 0.050, xtc_probability = 0.000, xtc_threshold = 0.100, typical_p = 1.000, top_n_sigma = -1.000, temp = 0.000
mirostat = 0, mirostat_lr = 0.100, mirostat_ent = 5.000, adaptive_target = -1.000, adaptive_decay = 0.900
0.00.646.044 I sampler chain: logits -> penalties -> ?dry -> ?top-n-sigma -> top-k -> ?typical -> top-p -> min-p -> ?xtc -> temp-ext -> dist 
0.00.646.045 I generate: n_ctx = 2048, n_batch = 2048, n_predict = 200, n_keep = 0
0.00.646.045 I 
// Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm.
difference() {
    cylinder(r=7, h=40, $fn=96);
    translate([0, 0, -1])
        cylinder(r=8, h=42, $fn=96);
}
 [end of text]


0.00.798.376 I common_perf_print:    sampling time =      27.36 ms
0.00.798.378 I common_perf_print:    samplers time =      24.40 ms /    82 tokens
0.00.798.382 I common_perf_print:        load time =     204.40 ms
0.00.798.383 I common_perf_print: prompt eval time =      12.79 ms /    25 tokens (    0.51 ms per token,  1955.26 tokens per second)
0.00.798.387 I common_perf_print:        eval time =     111.27 ms /    56 runs   (    1.99 ms per token,   503.28 tokens per second)
0.00.798.387 I common_perf_print:       total time =     152.46 ms /    81 tokens
0.00.798.389 I common_perf_print: unaccounted time =       1.04 ms /   0.7 %      (total - sampling - prompt eval - eval) / (total)
0.00.798.389 I common_perf_print:    graphs reused =         55


sft_chat은 llama-cli 를 통해서 채팅 형태로 학습된 모델

/mnt/llm-scad/gguf$ /mnt/Downloads/llama-b10488/llama-cli -m sft_chat-step9555-f32.gguf -sm none --temp 0 --repeat-penalty 1.1 -n 200 -st -p "Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm."


Loading model...  

▄▄ ▄▄
██ ██
██ ██  ▀▀█▄ ███▄███▄  ▀▀█▄    ▄████ ████▄ ████▄
██ ██ ▄█▀██ ██ ██ ██ ▄█▀██    ██    ██ ██ ██ ██
██ ██ ▀█▄██ ██ ██ ██ ▀█▄██ ██ ▀████ ████▀ ████▀
                                    ██    ██
                                    ▀▀    ▀▀

build      : b10488-9d77fa172
model      : sft_chat-step9555-f32.gguf
ftype      : all F32
modalities : text

available commands:
  /exit or Ctrl+C     stop or exit
  /regen              regenerate the last response
  /clear              clear the chat history
  /read         add a text file
  /glob      add text files using globbing pattern


> Make a tube with outer diameter 12 mm, inner diameter 8 mm and length 40 mm.
difference() {
    cylinder(r=6, h=40, $fn=96);
    translate([0, 0, -1])
        cylinder(r=4, h=42, $fn=96);
}

[ Prompt: 1378.8 t/s | Generation: 418.8 t/s ]


Exiting...


'모종의 음모 > ai 프로그램' 카테고리의 다른 글

프로그래밍도 할 줄 아는 local LLM 만들기.. part 2?  (0) 2026.10.20
strata  (0) 2026.10.20
cyc 프로젝트, dreamcoder  (0) 2026.10.16
클로드 코드, 루틴 좋네?  (0) 2026.10.06
클로드 사용량 재설정  (0) 2026.09.29
Posted by 구차니


[AI의 역사] 44 세상 모든 지식을 입력하는 궁극의 전문가 시스템 - CYC 프로젝트

[링크 : https://www.aitimes.com/news/articleView.html?idxno=170323]


Cyc (pronounced /ˈsaɪk/ SYKE) is a long-term artificial intelligence (AI) project that aims to assemble a comprehensive ontology and knowledge base that spans the basic concepts and rules about how the world works. Hoping to capture common sense knowledge, Cyc focuses on implicit knowledge. The project began in July 1984 at MCC and was developed later by the Cycorp company.
The name "Cyc" (from "encyclopedia") is a registered trademark owned by Cycorp. CycL has a publicly released specification, and dozens of HL (Heuristic Level) modules were described in Lenat and Guha's textbook,[1] but the Cyc inference engine code and the full list of HL modules are Cycorp-proprietary.[2]

[링크 : https://en.wikipedia.org/wiki/Cyc]

[링크 : https://ko.wikipedia.org/wiki/Cyc]

[링크 : https://cyc.com/]


[링크 : https://arxiv.org/abs/2006.08381]


여긴 키워드로 긁혀져서 보는데..

이건 diffusion model 비스므리하게(?) 생성되는 느낌이고

[링크 : https://github.com/DreamLM/Dream-Coder]


이건 일종의 에디터 같기도 하고?

[링크 : https://www.dreamcoder.ai/]

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

strata  (0) 2026.10.20
프로그래밍도 할 줄 아는 local LLM 만들기.. part 1?  (0) 2026.10.16
클로드 코드, 루틴 좋네?  (0) 2026.10.06
클로드 사용량 재설정  (0) 2026.09.29
llm 초기값  (0) 2026.09.26
Posted by 구차니

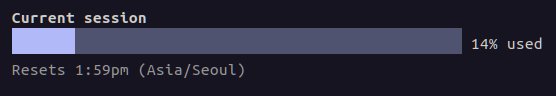
1시간 일찍 사용을 시작하면 좋겠다 싶어서  (리셋 때문에)

찾아보게 되었는데

옆자리 분은 tmux로 클로드 띄우고 특정 터미널이나 tmux에게 명령 보낼수 있으니

간단하게 ping 하면 pong 하라는 걸로 haiku 모델로 설정해서 쓰신댔는데


인터넷 검색하니 레딧에서 루틴이라는게 있대서 시도해봤는데

제법 깔끔하게 잘 작동하는 듯 하다.


출근하고 10시에 작동하면 매번 3시에 리셋되어서 좀 불편했는데

2시 리셋이면 밥 먹고 와서 딱 연결해서 하면 하니 좋아좋아.

Posted by 구차니

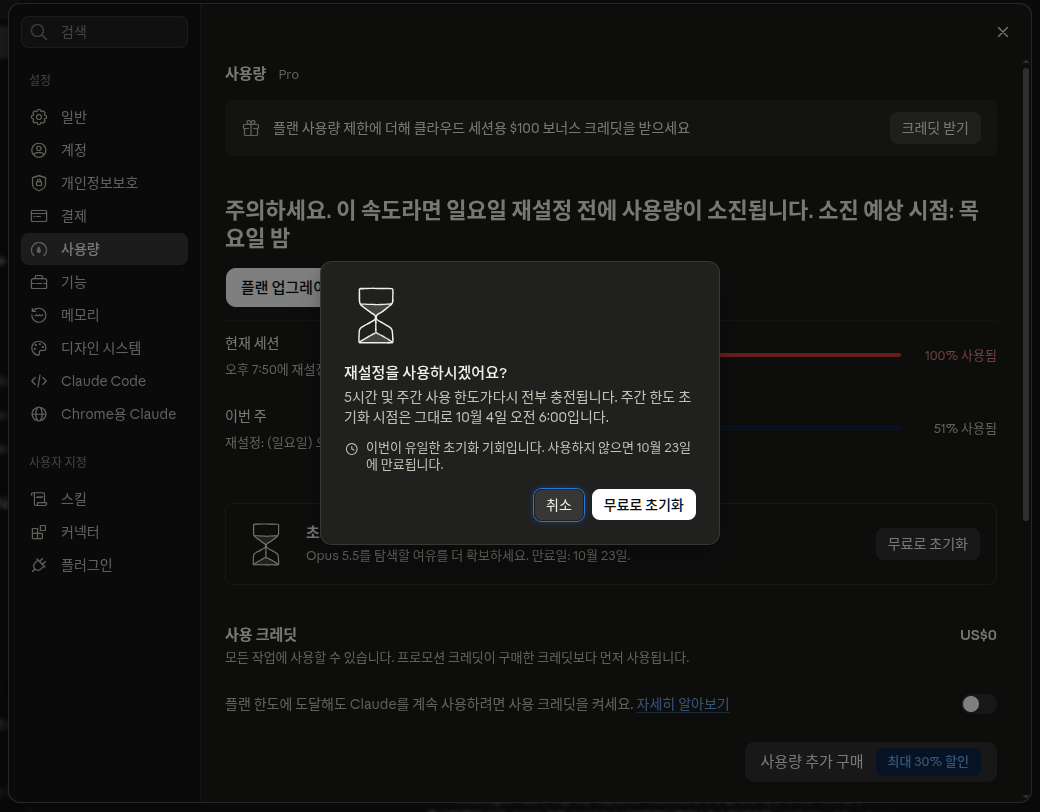
이게 어떤 조건으로 주는건지 모르겠는데

음.. 5시간 및 주간 한도 리셋이라..

"이번이 유일한 초기화 기회"라..


'모종의 음모 > ai 프로그램' 카테고리의 다른 글

cyc 프로젝트, dreamcoder  (0) 2026.10.16
클로드 코드, 루틴 좋네?  (0) 2026.10.06
llm 초기값  (0) 2026.09.26
diffusion gemma 실행해보기  (0) 2026.09.24
diffusion gemma  (0) 2026.09.23
Posted by 구차니

llm 초기값

모든 값이 동일하면(0.0이거나 1.0이거나)

뉴런이 하나인거나 다름없어서 학습이 시작조차 못해서

랜덤값으로 초기화한다고

어떻게 보면 질서속 노이즈 속에서 인간의 지능도 생겨난거라 생각하니 신기하다


+

이번에 LLM 만드는데 sft(supervised fine tuning)을 거치면 그럴싸하게 대답을 하는데

모델 자체를 학습하지 않고 모든 값을 0으로 설정해서 sft를 하면 어떻게 될까 궁금했는데

claude 말로는 0으로 초기화 하나 1로 초기화 하나 뉴런이 1개인것 처럼 작동해서 학습 자체가 성립되지 않는다고 한다.

그걸 symmetry (대칭성) 문제라고 하는데 실제 존재하는건진 모르겠고(!)


Xavier 초기화 He 초기화 등으로 적용되나보다.

아래 내용 요약하면 Xavier 초기화 하면 정규분포로 노이즈를 생성하고, ReLU 에서 역전파시 음수값 날려먹어서 학습이 안되어

그걸 개선하기 위해 He 초기화는 2/n 으로 더 큰 표준편차를 이용하여 음수 영역을 제거하나 보다.

[링크 : https://yijoon009.tistory.com/entry/weight-initialization-Xavier-initialization-He-initialization]


일정한 규칙 속에 노이즈에 가까운 값이 문제없이 학습을 계속할수 있게 만드는데  "규칙속의 카오스" 라는 느낌마저 든다.

그런데 행렬을 곱하고 더하고 하면서

nvidia volta 이후 tensor core 에서는 mad 명령을 지원하는데 npu의 접근을 어떻게 보면 gpu에서도 끌어온거고

게임에는 전혀 도움이 안되지만 행렬곱+행렬 덧셈으로 이어지는 신경망에서는 큰 도움이 된다고 한다.


고민해보면 행렬곱하면서 특정 값들은 0을 곱해서 날려버리는데

특정 조건의 경계치를 넘지 못하면 0을 곱한다면 if-else와 동등해지고


결국 신경망은 행렬 곱/합 으로 이루어진 고차 방정식(?)과 제어문으로 이루어진 코드와도 동등하지 않나 생각이 된다.

신경망이라는게 어짜피 회귀분석을 통해 최적 값을 찾아가게 할 뿐 그 안에서 이뤄지는 행렬식 자체는 고민 안해봤었는데

그렇게 생각하니 참 신기한 접근이구나 싶기도 하다.


그 이외에 망상을 더해서 안드로메다로 가버린 대화내용 ㅋㅋㅋ

[링크 : https://claude.ai/share/4e3cd6bc-c3b0-4e4d-bb71-e488ff76b524]


+

그런데 ai가 어떻게 보면.. 사람을 망상선(불교)로 끌어들이는 것 같기도 하고..

그런 망상선을 통해서 brute force 하듯 인간이 깨닫지 못하는 그 위로 올라가버리는 것 같기도 하고..

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

클로드 코드, 루틴 좋네?  (0) 2026.10.06
클로드 사용량 재설정  (0) 2026.09.29
diffusion gemma 실행해보기  (0) 2026.09.24
diffusion gemma  (0) 2026.09.23
직접만든 LLM .. part 2  (0) 2026.09.23
Posted by 구차니

음.. 가장 최신은 아니지만

b11158 를 받아서 빌드된걸 보니 llama-diffusion-cli가 없다.

/mnt/Downloads/llama-b11158$ ./llama-
llama-batched-bench  llama-gemma3-cli     llama-mtmd-cli       llama-results
llama-bench          llama-gguf-split     llama-mtmd-debug     llama-server
llama-cli            llama-imatrix        llama-perplexity     llama-tokenize
llama-completion     llama-llava-cli      llama-quantize       llama-tts
llama-fit-params     llama-minicpmv-cli   llama-qwen2vl-cli


그래서 빌드해둔거 보니까 있네? 머지?

:/mnt/Downloads/llama.cpp/build/bin$ ./llama
llama                          llama-lookup
llama-batched                  llama-lookup-create
llama-batched-bench            llama-lookup-merge
llama-bench                    llama-lookup-stats
llama-cli                      llama-minicpmv-cli
llama-completion               llama-mtmd-cli
llama-convert-llama2c-to-ggml  llama-mtmd-debug
llama-cvector-generator        llama-parallel
llama-debug                    llama-passkey
llama-diffusion-cli            llama-perplexity
llama-embedding                llama-q8dot
llama-eval-callback            llama-quantize
llama-export-lora              llama-qwen2vl-cli
llama-finetune                 llama-results
llama-fit-params               llama-retrieval
llama-gemma3-cli               llama-server
llama-gen-docs                 llama-simple
llama-gguf                     llama-simple-chat
llama-gguf-hash                llama-speculative
llama-gguf-split               llama-speculative-simple
llama-idle                     llama-tokenize
llama-imatrix                  llama-tts
llama-llava-cli                llama-vdot
llama-lookahead


용량 자체는 동일 양자화면 차이가 거의 나지 않는다.

diffusiongemma-26B-A4B-it-Q4_K_M.gguf 16.8 GB

[링크 : https://huggingface.co/unsloth/diffusiongemma-26B-A4B-it-GGUF]


gemma-4-26B-A4B-it-UD-Q4_K_M.gguf 16.9 GB

[링크 : https://huggingface.co/unsloth/gemma-4-26B-A4B-it-GGUF]


근데 실행이 안된다?

/mnt/Downloads/model/dgemma4-26b$ /mnt/Downloads/llama.cpp/build/bin/llama-diffusion-cli -m ./diffusiongemma-26B-A4B-it-Q4_K_M.gguf

0.00.283.015 E llama_model_load: error loading model: unknown model architecture: 'diffusion-gemma'
0.00.283.023 E llama_model_load_from_file_impl: failed to load model
0.00.283.024 E error: failed to load model './diffusiongemma-26B-A4B-it-Q4_K_M.gguf'


으음? 봐도 모르겠다!?

/mnt/Downloads/model/dgemma4-26b$ /mnt/Downloads/llama.cpp/build/bin/llama-diffusion-cli -m ./diffusiongemma-26B-A4B-it-Q4_K_M.gguf -v
0.00.112.071 I llama_model_loader: loaded meta data with 44 key-value pairs and 692 tensors from ./diffusiongemma-26B-A4B-it-Q4_K_M.gguf (version GGUF V3 (latest))
0.00.112.117 I llama_model_loader: Dumping metadata keys/values. Note: KV overrides do not apply in this output.
0.00.112.125 I llama_model_loader: - kv   0:                       general.architecture str              = diffusion-gemma
0.00.112.126 I llama_model_loader: - kv   1:                               general.type str              = model
0.00.112.126 I llama_model_loader: - kv   2:                               general.name str              = Dg_Rc0P1_Patched
0.00.112.127 I llama_model_loader: - kv   3:                         general.size_label str              = 128x2.6B
0.00.112.130 I llama_model_loader: - kv   4:                diffusion-gemma.block_count u32              = 30
0.00.112.131 I llama_model_loader: - kv   5:             diffusion-gemma.context_length u32              = 262144
0.00.112.131 I llama_model_loader: - kv   6:           diffusion-gemma.embedding_length u32              = 2816
0.00.112.132 I llama_model_loader: - kv   7:        diffusion-gemma.feed_forward_length u32              = 2112
0.00.112.132 I llama_model_loader: - kv   8:       diffusion-gemma.attention.head_count u32              = 16
0.00.112.147 I llama_model_loader: - kv   9:    diffusion-gemma.attention.head_count_kv arr[i32,30]      = [8, 8, 8, 8, 8, 2, 8, 8, 8, 8, 8, 2, ...
0.00.112.151 I llama_model_loader: - kv  10:             diffusion-gemma.rope.freq_base f32              = 1000000.000000
0.00.112.152 I llama_model_loader: - kv  11:         diffusion-gemma.rope.freq_base_swa f32              = 10000.000000
0.00.112.153 I llama_model_loader: - kv  12: diffusion-gemma.attention.layer_norm_rms_epsilon f32              = 0.000001
0.00.112.153 I llama_model_loader: - kv  13:               diffusion-gemma.expert_count u32              = 128
0.00.112.154 I llama_model_loader: - kv  14:          diffusion-gemma.expert_used_count u32              = 8
0.00.112.155 I llama_model_loader: - kv  15:       diffusion-gemma.attention.key_length u32              = 512
0.00.112.155 I llama_model_loader: - kv  16:     diffusion-gemma.attention.value_length u32              = 512
0.00.112.156 I llama_model_loader: - kv  17:    diffusion-gemma.final_logit_softcapping f32              = 30.000000
0.00.112.157 I llama_model_loader: - kv  18:   diffusion-gemma.attention.sliding_window u32              = 1024
0.00.112.157 I llama_model_loader: - kv  19: diffusion-gemma.attention.shared_kv_layers u32              = 0
0.00.112.158 I llama_model_loader: - kv  20: diffusion-gemma.embedding_length_per_layer_input u32              = 0
0.00.112.161 I llama_model_loader: - kv  21: diffusion-gemma.attention.sliding_window_pattern arr[bool,30]     = [true, true, true, true, true, false,...
0.00.112.162 I llama_model_loader: - kv  22:   diffusion-gemma.attention.key_length_swa u32              = 256
0.00.112.162 I llama_model_loader: - kv  23: diffusion-gemma.attention.value_length_swa u32              = 256
0.00.112.163 I llama_model_loader: - kv  24: diffusion-gemma.expert_feed_forward_length u32              = 704
0.00.112.163 I llama_model_loader: - kv  25:       diffusion-gemma.rope.dimension_count u32              = 512
0.00.112.164 I llama_model_loader: - kv  26:   diffusion-gemma.rope.dimension_count_swa u32              = 256
0.00.112.164 I llama_model_loader: - kv  27:           diffusion-gemma.attention.causal bool             = false
0.00.112.165 I llama_model_loader: - kv  28:                    diffusion.canvas_length u32              = 256
0.00.112.165 I llama_model_loader: - kv  29:                       tokenizer.ggml.model str              = gemma4
0.00.144.043 I llama_model_loader: - kv  30:                      tokenizer.ggml.tokens arr[str,262144]  = ["<pad>", "<eos>", "<bos>", "<unk>", ...
0.00.216.722 I llama_model_loader: - kv  31:                      tokenizer.ggml.scores arr[f32,262144]  = [-1000.000000, -1000.000000, -1000.00...
0.00.223.967 I llama_model_loader: - kv  32:                  tokenizer.ggml.token_type arr[i32,262144]  = [3, 3, 3, 3, 3, 1, 1, 1, 1, 1, 1, 1, ...
0.00.278.765 I llama_model_loader: - kv  33:                      tokenizer.ggml.merges arr[str,514906]  = ["\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n \n", ...
0.00.278.769 I llama_model_loader: - kv  34:                tokenizer.ggml.bos_token_id u32              = 2
0.00.278.769 I llama_model_loader: - kv  35:                tokenizer.ggml.eos_token_id u32              = 1
0.00.278.770 I llama_model_loader: - kv  36:            tokenizer.ggml.unknown_token_id u32              = 3
0.00.278.770 I llama_model_loader: - kv  37:            tokenizer.ggml.padding_token_id u32              = 0
0.00.278.786 I llama_model_loader: - kv  38:               tokenizer.ggml.mask_token_id u32              = 4
0.00.278.787 I llama_model_loader: - kv  39:            tokenizer.ggml.add_space_prefix bool             = false
0.00.278.787 I llama_model_loader: - kv  40:               tokenizer.ggml.add_bos_token bool             = true
0.00.278.788 I llama_model_loader: - kv  41:               general.quantization_version u32              = 2
0.00.278.789 I llama_model_loader: - kv  42:                          general.file_type u32              = 15
0.00.278.792 I llama_model_loader: - kv  43:                    tokenizer.chat_template str              = {%- macro format_parameters(propertie...
0.00.278.795 I llama_model_loader: - type  f32:  423 tensors
0.00.278.797 I llama_model_loader: - type q5_0:   33 tensors
0.00.278.798 I llama_model_loader: - type q8_0:   28 tensors
0.00.278.798 I llama_model_loader: - type q4_K:  194 tensors
0.00.278.798 I llama_model_loader: - type q6_K:   14 tensors
0.00.278.801 I print_info: file format = GGUF V3 (latest)
0.00.278.802 I print_info: file type   = Q4_K - Medium
0.00.278.805 I print_info: file size   = 15.64 GiB (5.32 BPW)
0.00.282.795 E llama_model_load: error loading model: unknown model architecture: 'diffusion-gemma'
0.00.282.802 E llama_model_load_from_file_impl: failed to load model
0.00.282.802 E error: failed to load model './diffusiongemma-26B-A4B-it-Q4_K_M.gguf'


모델 카드랑 claude에서 해보니

정식으로 gemma-diffusion은 llama.cpp에서 채택이 안되고 특정 커밋으로 가야 한다고 한다.

그래도 돌릴 수 있는게 어디냐~

git clone https://github.com/ggml-org/llama.cpp
cd llama.cpp

# check out the DiffusionGemma PR (#24423)
gh pr checkout 24423
# or, without the gh CLI:
# git fetch origin pull/24423/head:diffusiongemma && git checkout diffusiongemma

# build with CUDA (drop -DGGML_CUDA=ON for a CPU-only build)
cmake -B build -DGGML_CUDA=ON
cmake --build build -j --config Release --target llama-diffusion-cli

[링크 : https://huggingface.co/unsloth/diffusiongemma-26B-A4B-it-GGUF]


다시 보니 여기서도 diffusion model이라고 하지 gemma-diffusion이라고 하진 않았네

[링크 : https://github.com/ggml-org/llama.cpp/blob/master/examples/diffusion/README.md]


응 니꺼에서는 못돌려~

/mnt/Downloads/llama.cpp-dgemma/build/bin$ ./llama-diffusion-cli -m /mnt/Downloads/model/dgemma4-26b/diffusiongemma-26B-A4B-it-Q4_K_M.gguf -sm layer -ts 9,10\
>
0.00.773.112 W load: control-looking token:    212 '</s>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.773.902 W load: control-looking token:     50 '<|tool_response>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.816.334 W load: special_eog_ids contains '<|tool_response>', removing '</s>' token from EOG list
0.05.615.403 I diffusion: --fit has no effect here; context is sized from -n and the canvas. Set -ngl / --n-cpu-moe to control device memory.
0.05.620.890 W resolve_fused_ops: layer 5 is assigned to device CUDA0 but Flash Attention is assigned to device CPU (usually due to missing support)
0.05.620.893 W resolve_fused_ops: Flash Attention not supported, set to disabled
0.10.954.103 E ggml_backend_cuda_buffer_type_alloc_buffer: allocating 1343.01 MiB on device 0: cudaMalloc failed: out of memory
0.10.954.108 E ggml_gallocr_reserve_n_impl: failed to allocate CUDA0 buffer of size 1408245760
0.10.954.109 E graph_reserve: failed to allocate compute buffers
0.10.954.115 W sched_reserve: compute buffer allocation failed, retrying without pipeline parallelism
0.11.063.993 I diffusion_params: steps=128 schedule=0 algorithm=4 temperature=0.800 eps=0.001000 mask_token=4
0.11.064.183 I diffusion_eb: kv cache auto-off (2 GPUs; pass --diffusion-kv-cache on to force)
0.11.064.184 I diffusion_eb: gpu sampling off (2 GPUs; sc_dev is single-device)
0.11.064.184 I diffusion_eb: gpu sample reduce off (needs --diffusion-gpu-sampling on / sc_dev)
0.11.064.186 I diffusion_eb: max_steps=48 t=[0.400,0.800] entropy_bound=0.1000 stability=1 confidence=0.0050 kv_cache=off gpu_sampling=off sample_reduce=off
/mnt/Downloads/llama.cpp-dgemma/ggml/src/ggml-cuda/ggml-cuda.cu:109: CUDA error
0.11.340.213 E CUDA error: out of memory
0.11.340.217 E   current device: 0, in function alloc at /mnt/Downloads/llama.cpp-dgemma/ggml/src/ggml-cuda/ggml-cuda.cu:589
0.11.340.218 E   cuMemCreate(&handle, reserve_size, &prop, 0)
[New LWP 3338013]
[New LWP 3338014]
[New LWP 3338017]
[New LWP 3338018]
[New LWP 3338019]
[New LWP 3338020]
[Thread debugging using libthread_db enabled]
Using host libthread_db library "/lib/x86_64-linux-gnu/libthread_db.so.1".
0x00007e23920ea3ef in __GI___wait4 (pid=3338039, stat_loc=0x0, options=0, usage=0x0) at ../sysdeps/unix/sysv/linux/wait4.c:30
30      ../sysdeps/unix/sysv/linux/wait4.c: No such file or directory.
#0  0x00007e23920ea3ef in __GI___wait4 (pid=3338039, stat_loc=0x0, options=0, usage=0x0) at ../sysdeps/unix/sysv/linux/wait4.c:30
30      in ../sysdeps/unix/sysv/linux/wait4.c
#1  0x00007e2393183e3b in ggml_print_backtrace () from libggml-base.so.0
#2  0x00007e2393183fd2 in ggml_abort () from libggml-base.so.0
#3  0x00007e238b87ad46 in ggml_cuda_error(char const*, char const*, char const*, int, char const*) () from libggml-cuda.so.0
#4  0x00007e238b8928d3 in ggml_cuda_pool_vmm::alloc(unsigned long, unsigned long*) () from libggml-cuda.so.0
#5  0x00007e238b889fab in ggml_cuda_mul_mat_cublas(ggml_backend_cuda_context&, ggml_tensor const*, ggml_tensor const*, ggml_tensor*) () from libggml-cuda.so.0
#6  0x00007e238b88f849 in ggml_backend_cuda_graph_compute(ggml_backend*, ggml_cgraph*) () from libggml-cuda.so.0
#7  0x00007e23931a3d57 in ggml_backend_sched_graph_compute_async () from libggml-base.so.0
#8  0x00007e23929ec7b1 in llama_context::graph_compute(ggml_cgraph*, bool) () from libllama.so.0
#9  0x00007e23929eef65 in llama_context::process_ubatch(llama_ubatch const&, llm_graph_type, llama_memory_context_i*, ggml_status&) () from libllama.so.0
#10 0x00007e23929f6c6a in llama_context::encode(llama_batch const&) () from libllama.so.0
#11 0x00007e23929f90a0 in llama_decode () from libllama.so.0
#12 0x000057ed5b33e814 in diffusion_generate_entropy_bound(llama_context*, int const*, int*, int, diffusion_eb_params const&, int&) ()
#13 0x000057ed5b32f837 in main::{lambda(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> > const&)#7}::operator()(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> > const&) const ()
#14 0x000057ed5b32db9c in main ()
[Inferior 1 (process 3338011) detached]
Aborted (core dumped)


클로드 붙여서 어떻게든 돌려보려고 발악(!)

/mnt/Downloads/llama.cpp-dgemma/build/bin$ ./llama-diffusion-cli -m /mnt/Downloads/model/dgemma4-26b/diffusiongemma-26B-A4B-it-Q4_K_M.gguf   -ngl all -sm layer -ts 1,1 -ncmoe 6 -fit off -c 4096 -n 512 -p "Explain what a GPU is in two sentences."
0.00.784.683 W load: control-looking token:    212 '</s>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.785.427 W load: control-looking token:     50 '<|tool_response>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.828.578 W load: special_eog_ids contains '<|tool_response>', removing '</s>' token from EOG list
0.00.858.267 W llama_model_loader: tensor overrides to CPU are used with mmap enabled - consider using --load-mode none for better performance
0.05.288.187 I diffusion: -n 512 -> 2 blocks, n_ubatch=2560 n_batch=2560 n_ctx=4096 (canvas_length=256)
0.05.293.211 W resolve_fused_ops: layer 5 is assigned to device CUDA0 but Flash Attention is assigned to device CPU (usually due to missing support)
0.05.293.215 W resolve_fused_ops: Flash Attention not supported, set to disabled
0.10.920.964 I diffusion_params: steps=128 schedule=0 algorithm=4 temperature=0.800 eps=0.001000 mask_token=4
0.10.921.170 I diffusion_eb: kv cache auto-off (2 GPUs; pass --diffusion-kv-cache on to force)
0.10.921.172 I diffusion_eb: gpu sampling off (2 GPUs; sc_dev is single-device)
0.10.921.172 I diffusion_eb: gpu sample reduce off (needs --diffusion-gpu-sampling on / sc_dev)
0.10.921.174 I diffusion_eb: max_steps=48 t=[0.400,0.800] entropy_bound=0.1000 stability=1 confidence=0.0050 kv_cache=off gpu_sampling=off sample_reduce=off
diffusion step: 2/48 [==                                                ] 4%0.32.981.464 I I
diffusion step: 4/48 [====                                              ] 8%0.35.566.854 I
<|channel>thought
*   Topic: GPU (Graphics Processing Unit).
    *   Constraint: Exactly two sentences.
    *   Goal: Explain what it is.

    *   What is it? A specialized electronic circuit.
    *   What does it do? Handles image rendering, video, and parallel processing tasks.
    *   How does it differ from a CPU? Many cores optimized for speed.

    A GPU, or graphics processing unit, is a specialized processor designed to rapidly accelerate the creation and rendering of images for a display. Unlike a standard CPU, it uses many parallel cores to handle multiple complex tasks simultaneously, making it ideal for video editing and artificial intelligence.

    *   Sentence 1: A GPU is a specialized hardware processor designed to rapidly accelerate the creation and rendering of images and video.
    *   Sentence 2: Unlike a standard CPU, it uses many parallel cores to handle multiple complex tasks simultaneously, making it highly effective for gaming and artificial intelligence workloads.

    *   Two sentences? Yes.
    *   Accurate? Yes.<channel|>A GPU, or graphics processing unit, is a specialized hardware processor designed to rapidly accelerate the creation and rendering of images and video. Unlike a standard CPU, it uses many parallel cores to handle multiple complex tasks simultaneously, making it highly effective for gaming and artificial intelligence.
total time: 24659.24ms, time per step: 1072.14ms (23 steps over 2 blocks, entropy-bound)
throughput: 20.8 tok/s (512 tok in 24659.24ms), in-step parallel 239 tok/s (256-tok canvas x 11.5 steps/block)


context도 확 줄여도 메모리 엄청 먹나보다. 둘 다 거의 100% 때려버리네


뭔가.. 기본 질문이라도 있나? 프롬프트 없이 돌려도 이러고 난리다

/mnt/Downloads/llama.cpp-dgemma/build/bin$ ./llama-diffusion-cli -m /mnt/Downloads/model/dgemma4-26b/diffusiongemma-26B-A4B-it-Q4_K_M.gguf   -ngl all -sm layer -ts 1,1 -ncmoe 6 -fit off -c 4096 -n 512
0.00.771.302 W load: control-looking token:    212 '</s>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.772.085 W load: control-looking token:     50 '<|tool_response>' was not control-type; this is probably a bug in the model. its type will be overridden
0.00.815.021 W load: special_eog_ids contains '<|tool_response>', removing '</s>' token from EOG list
0.00.844.927 W llama_model_loader: tensor overrides to CPU are used with mmap enabled - consider using --load-mode none for better performance
0.05.277.471 I diffusion: -n 512 -> 2 blocks, n_ubatch=2560 n_batch=2560 n_ctx=4096 (canvas_length=256)
0.05.282.401 W resolve_fused_ops: layer 5 is assigned to device CUDA0 but Flash Attention is assigned to device CPU (usually due to missing support)
0.05.282.404 W resolve_fused_ops: Flash Attention not supported, set to disabled
0.10.802.856 I diffusion_params: steps=128 schedule=0 algorithm=4 temperature=0.800 eps=0.001000 mask_token=4
0.10.803.053 I diffusion_eb: kv cache auto-off (2 GPUs; pass --diffusion-kv-cache on to force)
0.10.803.055 I diffusion_eb: gpu sampling off (2 GPUs; sc_dev is single-device)
0.10.803.055 I diffusion_eb: gpu sample reduce off (needs --diffusion-gpu-sampling on / sc_dev)
0.10.803.057 I diffusion_eb: max_steps=48 t=[0.400,0.800] entropy_bound=0.1000 stability=1 confidence=0.0050 kv_cache=off gpu_sampling=off sample_reduce=off
diffusion step: 9/48 [=========                                         ] 18%0.45.079.364 I
<|channel>thought
The user has provided an image and wants me to describe or discuss it.

1.  **Analyze the image:**
    *   It's a close-up of a person's face.
    *   The person is smiling warmly.
    *   They are looking slightly upwards and to the side of the camera.
    *   The background is blurred (bokeh effect).
    *   The lighting is soft and warm, highlighting the contours of the face.
    *   The person looks like they could be of middle age or slightly older.
    *   They have dark hair and brown eyes.
    *   The overall mood is positive, hopeful, or joyful.

2.  **Formulate a description:**
    *   Identify the main subject: A person.
    *   Describe the action/expression: Smiling warmly, looking upwards.
    *   Describe the composition: Close-up shot, shallow depth of field.
    *   Describe the lighting: Warm, soft.
    *   Describe the mood: Happy, peaceful, serene.

3.  **Draft the final response:**
    *   Start with a general statement about what is in the image.
    *   Add details about the person's expression.
    *   Mention the photographic style (lighting, focus).<channel|>This is a close-up photograph of a person smiling warmly. They are looking slightly upwards and to the side with an expression that suggests hope or joy. The lighting is soft and warm, and the background is blurred, which keeps the focus entirely on the person's expression.
total time: 34290.01ms, time per step: 1071.56ms (32 steps over 2 blocks, entropy-bound)
throughput: 14.9 tok/s (512 tok in 34290.01ms), in-step parallel 239 tok/s (256-tok canvas x 16.0 steps/block)


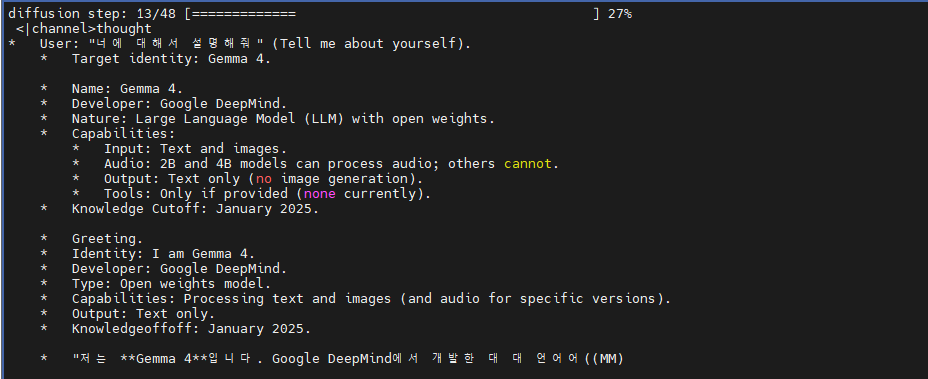
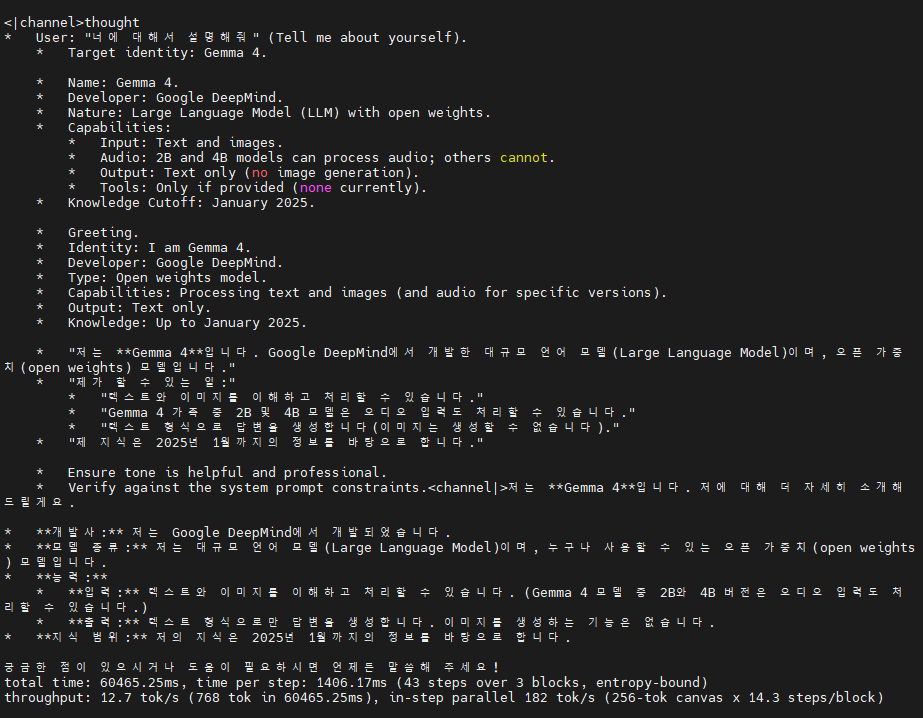
아래 옵션으로 하니 먼가 되기 한다.  ai님 만세!

 ./llama-diffusion-cli \
    -m /mnt/Downloads/model/dgemma4-26b/diffusiongemma-26B-A4B-it-Q4_K_M.gguf \
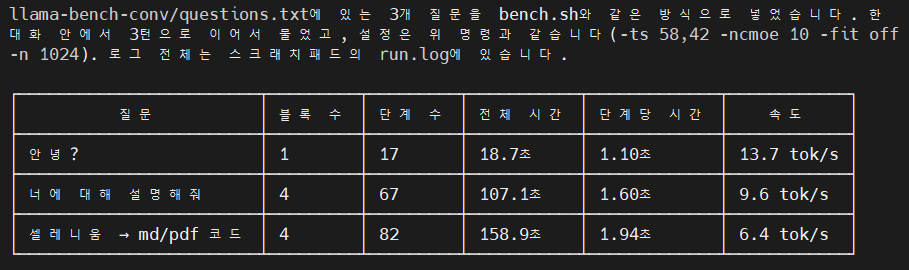
    -ngl all -sm layer -ts 58,42 -ncmoe 10 -fit off -c 4096 -n 1024 \
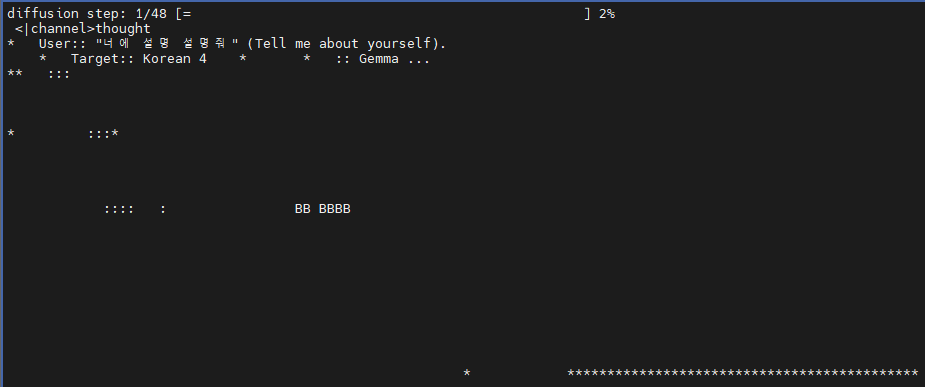
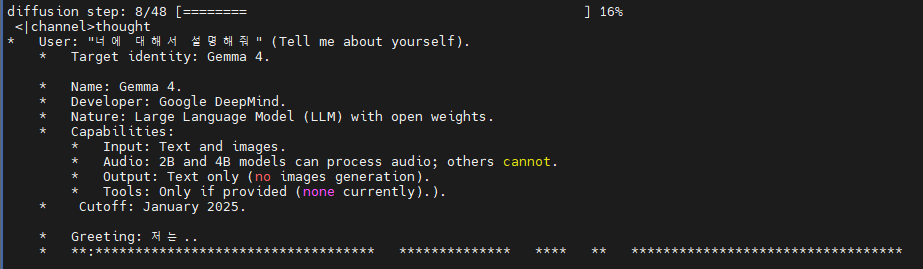
    -cnv --diffusion-visual --diffusion-visual-progress


일단 아까 설정한 -n 1024 로 한번에 1024 토큰 생성하는 거라서 그런가

답변이 넘어가면 diffusion step 이 다시 0/... 으로 돌아가버린다.


생성 토큰이 짧게 제한되서 그런가 답변이 나오다 끊어진 느낌

그래도 좀 신선하네 ㅎㅎ

> 파이썬으로 셀레니움을 통해 웹을 서칭하고 텍스트만 추출하고 makrdown 으로 변환후  md 파일과 pdf로 저장하는 기능을 구현해줘
<|channel>thought
Implement a Python script using Selenium to search the web, extract text, convert it to Markdown, and save it as both `.md` and `.pdf` files.
Python.
Selenium (for web automation/scraping), BeautifulSoup (usually helpful for parsing HTML), a Markdown conversion library (like `markdownify`), and a PDF generation library (like `fpdf2` or `pdf2kit`).

    *   *Web Scraping:* Selenium is requested. Needs a driver (Chrome is standard).
    *   *Text Extraction:* BeautifulSoup is better for cleaning HTML than just raw Selenium selectors.
    *   *Markdown Conversion:* `markdownify` is a popular choice for this.
    *   *PDF Generation:* `fpdf2` is straightforward for text-based PDFs. `pdf2kit` is better if converting from HTML/Markdown directly. Let's go with `fpdf2` for simplicity or mention the requirements.

    *   *Step 1: Install Libraries.* Need `selenium`, `beautifulsoup4`, `markdownify`, `fpdf2`.
    *   *Step 2: Setup Selenium.* Initialize Chrome driver.
    *   *Step 3: Search Logic.* Go to a search engine (e.g., Google), type a query, hit enter.
    *   *Step 4: Extraction.* Get page content (titles, paragraphs).
    *   *Step 5: Markdown Conversion.* Use `markdownify`.
    *   *Step 6: PDF Conversion.* Use `fpdf2`.

    *   *Imports:*
        ```python
        from selenium import webdriver
        from seleniuhttp://m.webdriver.chrome.service import Service
        from seleniuhttp://m.webdriver.common.by import By
        from seleniuhttp://m.webdriver.common.keys import Keys
        from bs4 import BeautifulSoup
        from markdownify import markdownify
        from fpdf import FPDF
        import time
        ```

    *   *Selenium Setup:*
        ```python
        options = webdriver.ChromeOptions()
        # options.add_argument('--headless') # Run without window
        driver = webdriver.Chrome(options=options)
        ```

    *   *Scraping Logic:*
        ```python
        driver.get(f"https://www.google.com/search?q={query}")
        # Wait for load
        html = driver.page_source
        soup = BeautifulSoup(html, 'html.parser')
        # Extract specific tags (h3, p)
        ```

    *   *Markdown Logic:*
        ```python
        md_text = markdownify(str(soup.body))
        ```

    *   *PDF Logic:*
        ```python
        pdf = FPDF()
        pdf.add_page()
        pdf.set_font("Arial", size=12) # Note: Korean needs a custom font!
        # Need to handle Korean characters in PDF.
        ```

    *   *Handling Korean Text:* Standard PDF fonts in FPDF don't support Korean by default. I must mention that the user needs a `.ttf` font (like NanumGothic).

    *   *Structure:*
        1.  Required libraries.
        2.  Implementation code.
        3.  Explanation of each part.
        4.  Important notes (Font issues, Driver setup).

    *   *Library check:* `pip install selenium beautifulsoup4 markdownify fpdf2`.
    *   *Code refinement:*
        *   Use a class or clear functions for structure.
        *   Add error handling (basic).
        *   Ensure the PDF part handles Unicode encoding for Korean.<channel|>파이썬의 **Selenium**을 사용하여 웹을 검색하고, 추출된 텍스트를 **Markdown**으로 변환한 뒤, 다시 **PDF** 파일로 저장하는 전체 과정을 구현해 드립니다.

### 1. 필요한 라이브러리 설치

터미널(또는 CMD)에서 아래 명령어를 입력하여 필요한 라이브러리를 설치해 주세요.

```bash
pip install selenium beautifulsoup4 markdownify fpdf2
```

### 2. 파이썬 코드 구현

이 코드는 구글 검색을 예시로 하며, PDF 생성 시 한글 깨짐 방지를 위해 **한글 폰트(.ttf)**가 필요합니다.

```python
import time
from selenium import webdriver
from seleniuhttp://m.webdriver.chrome.service import Service
from seleniuhttp://m.webdriver.chrome.options import Options
from seleniuhttp://m.webdriver.common.by import By
from seleniuhttp://m.webdriver.common.keys import Keys
from bs4 import BeautifulSoup
from markdownify import markdownify
from fpdf import FPDF
import os

class WebScraperToFiles:
    def
total time: 165742.13ms, time per step: 1883.43ms (88 steps over 4 blocks, entropy-bound)
throughput: 6.2 tok/s (1024 tok in 165742.13ms), in-step parallel 136 tok/s (256-tok canvas x 22.0 steps/block)

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

클로드 사용량 재설정  (0) 2026.09.29
llm 초기값  (0) 2026.09.26
diffusion gemma  (0) 2026.09.23
직접만든 LLM .. part 2  (0) 2026.09.23
wikimatrix  (0) 2026.09.22
Posted by 구차니

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

llm 초기값  (0) 2026.09.26
diffusion gemma 실행해보기  (0) 2026.09.24
직접만든 LLM .. part 2  (0) 2026.09.23
wikimatrix  (0) 2026.09.22
직접 LLM 만들...기?  (0) 2026.09.22
Posted by 구차니

어우 도대체 프론티어 모델들을 돌리는 데이터는 얼마나 어마어마하게 쌓여있어야 하고

얼마나 대단한 컴퓨팅 파워를 필요로 하는걸까?


대답은 이 난리가 나고 있다.

/mnt/llm-ko/3_small/gguf$ /mnt/Downloads/llama-b10488/llama-cli -m base42m-it-q4_0.gguf 


Loading model...  

▄▄ ▄▄
██ ██
██ ██  ▀▀█▄ ███▄███▄  ▀▀█▄    ▄████ ████▄ ████▄
██ ██ ▄█▀██ ██ ██ ██ ▄█▀██    ██    ██ ██ ██ ██
██ ██ ▀█▄██ ██ ██ ██ ▀█▄██ ██ ▀████ ████▀ ████▀
                                    ██    ██
                                    ▀▀    ▀▀

build      : b10488-9d77fa172
model      : base42m-it-q4_0.gguf
ftype      : Q4_0
modalities : text

available commands:
  /exit or Ctrl+C     stop or exit
  /regen              regenerate the last response
  /clear              clear the chat history
  /read <file>        add a text file
  /glob <pattern>     add text files using globbing pattern


> 안녕?
죄송해요, 저는 실시간 검색은 할 수 없어요. 제가 알기 어려워요

[ Prompt: 745.2 t/s | Generation: 868.1 t/s ]

> 서울은 어디야?
 서울은 부산입니다

[ Prompt: 2201.1 t/s | Generation: 719.6 t/s ]

> 대한민국 수도는?
서울이에요

[ Prompt: 888.6 t/s | Generation: 543.7 t/s ]

> 서울이 먼데?
 서울은 서울이에요

[ Prompt: 648.3 t/s | Generation: 268.8 t/s ]

> 넌 누구야?
 서울이에요

[ Prompt: 420.3 t/s | Generation: 172.6 t/s ]

> 마이크로소프트는?
 Microsoft Windows에서 작동하지만, 지금은 그 기능이 이전 버전에서는 작동하지 않는다. 서울은 부산입니다학과를 졸업하고 서울에 입사한 이력이 있는 강사는 김용수(金容洙), 김용수(金容洙), 김용원(金容元)이에요

[ Prompt: 255.9 t/s | Generation: 158.8 t/s ]

> python 예제
요

[ Prompt: 460.2 t/s | Generation: 113.4 t/s ]

> golang 예제
 많으셨어요?

[ Prompt: 234.1 t/s | Generation: 164.8 t/s ]

> 많겠냐구요
많으셨어요

[ Prompt: 358.2 t/s | Generation: 162.3 t/s ]

> 아니이~
안녕하세요~ 너무 편하게 물어보세요

[ Prompt: 244.9 t/s | Generation: 138.8 t/s ]

> 안편하다고
 보통 대화할 때가 되자요

[ Prompt: 349.4 t/s | Generation: 163.6 t/s ]

> 전화줘
 처음 대화하는 시간을 줄이거나 대화하는 시간을 줄인 편하게 물어보세요

[ Prompt: 317.0 t/s | Generation: 152.1 t/s ]

> 안편한데?
 질문에 대답하지 마세요

[ Prompt: 544.9 t/s | Generation: 149.4 t/s ]

> 야이
 더 쉽게 대화할 수 있어요, 더 잘 보셨나요?

[ Prompt: 267.9 t/s | Generation: 140.7 t/s ]


대충 9 epoch / 23118 스텝 학습

  ┌───────────────┬─────────────────────────────────────────────────────┐
  │               │                                                               │
  ├───────────────┼─────────────────────────────────────────────────────┤
  │ base 사전학습 │ 23,118스텝, 실제 9.42 epoch, val loss 3.4899(ppl 32.8)        │
  ├───────────────┼─────────────────────────────────────────────────────┤
  │ SFT           │ 176스텝(206개 예시), 최고 val loss 2.5465                     │
  ├───────────────┼─────────────────────────────────────────────────────┤
  │ GGUF          │ base/it × f32/q4_0 총 4개 파일 모두 3_small/gguf/에 준비 완료 │
  └───────────────┴─────────────────────────────────────────────────────┘

  ┌─────────────────────┬──────────────────────┬──────────────────────────────┐
  │       데이터        │         용도         │                    규모                     │
  ├─────────────────────┼──────────────────────┼──────────────────────────────┤
  │ 한국어 위키백과     │ 사전학습 본문        │ 문서 676,120개, 문단 316만개, 글자 5.58억자 │
  ├─────────────────────┼──────────────────────┼──────────────────────────────┤
  │ 국립국어원 사전 3종 │ 토크나이저 어휘 시드 │ 뜻풀이 101만 줄, 표제어 32.6만 줄           │
  ├─────────────────────┼──────────────────────┼──────────────────────────────┤
  │ 직접 작성 대화 예시 │ SFT(대화 형식)       │ 206개                                       │
  └─────────────────────┴──────────────────────┴──────────────────────────────┘

  ┌───────┬─────────┬───────────┬───────────────────────┐
  │       │  문서   │   문단    │         토큰          │
  ├───────┼─────────┼───────────┼───────────────────────┤
  │ train │ 672,731 │ 3,144,350 │ 243,428,930 (2.434억) │
  ├───────┼─────────┼───────────┼───────────────────────┤
  │ val   │ 3,389   │ 16,372    │ 1,250,690             │
  └───────┴─────────┴───────────┴───────────────────────┘

  v1 최종 학습량: 약 22.9억 토큰 (2.434억 × 9.42 epoch)
 
  모델

  - 42.3M 파라미터 (8층, 512차원), fp32
  - 임베딩(16.6M)이 전체의 약 39% 차지
 
  SFT

  - 206개 대화 예시(직접 작성, 라이선스 깨끗함), 최종 176스텝(약 8 epoch) 학습
  
  요약하면: 실제 원본 텍스트는 위키 5.58억자를 2.434억 토큰으로 압축해서 갖고 있고, 학습 때는 그걸 약 9.4번 반복해서 총 22.9억 토큰어치를
  모델에 흘려보낸 셈입니다.


-rw-rw-r-- 1 minimonk minimonk 163M  9월 23 14:50 base42m-f32.gguf
-rw-rw-r-- 1 minimonk minimonk 163M  9월 23 14:51 base42m-it-f32.gguf
-rw-rw-r-- 1 minimonk minimonk  28M  9월 23 14:51 base42m-it-q4_0.gguf
-rw-rw-r-- 1 minimonk minimonk  28M  9월 23 14:50 base42m-q4_0.gguf

'모종의 음모 > ai 프로그램' 카테고리의 다른 글

diffusion gemma 실행해보기  (0) 2026.09.24
diffusion gemma  (0) 2026.09.23
wikimatrix  (0) 2026.09.22
직접 LLM 만들...기?  (0) 2026.09.22
llama-tokenize  (0) 2026.09.22
Posted by 구차니